# Welcome to Waterflai

Welcome to the official documentation for Waterflai, your all-in-one platform for building and deploying powerful AI applications without the need for complex coding. Whether you're a seasoned AI developer or just starting your journey into the world of artificial intelligence, Waterflai provides the tools and flexibility you need to bring your ideas to life.

### What is Waterflai?

Waterflai is a cutting-edge, no-code platform designed to democratize AI development. Our platform empowers individuals and organizations to harness the power of large language models (LLMs) and create sophisticated AI applications such as chatbots, workflows, and analytics solutions with ease.

Key features of Waterflai include:

* **No-Code Interface**: Build AI applications using an intuitive, visual interface.
* **Multi-Provider Support**: Connect to various LLM providers and models to suit your specific needs.
* **Knowledge Integration**: Easily incorporate your own data and knowledge bases into your AI applications.
* **Flexible Workflows**: Design complex, multi-step AI processes without writing a single line of code.
* **Analytics and Insights**: Gain valuable insights into your AI applications' performance and user interactions.
* **Seamless Deployment**: Publish and integrate your AI solutions with minimal effort.

### Who is Waterflai for?

Waterflai caters to a wide range of users, including:

* **Developers** looking to streamline their AI development process
* **Business Analysts** seeking to create AI-powered solutions without extensive coding knowledge
* **Product Managers** aiming to prototype and deploy AI features rapidly
* **Entrepreneurs** wanting to incorporate AI capabilities into their products or services
* **Researchers** exploring practical applications of AI in various domains
* **Educators** teaching AI concepts through hands-on, no-code experiences

### How to Use This Documentation

Our documentation is structured to guide you through every aspect of using Waterflai, from your first steps to advanced application development:

1. Start with the **Getting Started** section to familiarize yourself with key concepts and set up your first project.
2. Explore the **Providers** section to learn about connecting to different AI models and selecting the right ones for your needs.
3. Dive into the **Knowledge** section to understand how to leverage your own data within Waterflai.
4. Use the **Studio** section to master the art of creating chatbots, workflows, and other AI applications.
5. Learn how to gain insights from your applications in the **Analytics** section.
6. Manage your Waterflai account and team in the **Administration** section.
7. If you encounter any issues, check out the **Troubleshooting** section for solutions and FAQs.

### Getting Help

If you need additional assistance beyond what's covered in the documentation:

* Contact our support team at support(at)waterflai.ai for personalized help.
* Follow us on [LinkedIn](https://www.linkedin.com/company/gravia-ai) for the latest updates and tips.

We're excited to see what you'll create with Waterflai. Let's embark on this AI journey together!

### Jump right in

<table data-view="cards"><thead><tr><th></th><th></th><th data-hidden data-card-cover data-type="files"></th><th data-hidden></th><th data-hidden data-card-target data-type="content-ref"></th></tr></thead><tbody><tr><td><strong>Getting started</strong></td><td>Create your first app</td><td><a href="https://content.gitbook.com/content/GxqXoeVSKzSmLzXgA3zn/blobs/tdCMeyjKeLsTMblkYjvL/1.png">1.png</a></td><td></td><td><a href="/getting-started/concepts">Getting Started</a></td></tr><tr><td><strong>Providers</strong></td><td>Connect to AI providers</td><td><a href="https://content.gitbook.com/content/GxqXoeVSKzSmLzXgA3zn/blobs/TemqzIECRtBPKyphZmgW/2.png">2.png</a></td><td></td><td><a href="/providers/providers-overview">Providers</a></td></tr><tr><td><strong>Knowledge</strong></td><td>Connect to your data</td><td><a href="https://content.gitbook.com/content/GxqXoeVSKzSmLzXgA3zn/blobs/3pMD12MaJ2Ougks0TaRz/3.png">3.png</a></td><td></td><td><a href="/knowledge/knowledge-overview">Knowledge</a></td></tr><tr><td><strong>Studio</strong></td><td>Implement your use cases</td><td><a href="https://content.gitbook.com/content/GxqXoeVSKzSmLzXgA3zn/blobs/FY1K1KEwcQiSASHH3OvI/4.png">4.png</a></td><td></td><td><a href="/studio/studio-overview">Studio</a></td></tr><tr><td><strong>Analytics</strong></td><td>Get insights on usage</td><td><a href="https://content.gitbook.com/content/GxqXoeVSKzSmLzXgA3zn/blobs/tdCMeyjKeLsTMblkYjvL/1.png">1.png</a></td><td></td><td><a href="/analytics/analytics-overview">Analytics</a></td></tr><tr><td><strong>Administration</strong></td><td>Manage the access</td><td><a href="https://content.gitbook.com/content/GxqXoeVSKzSmLzXgA3zn/blobs/TemqzIECRtBPKyphZmgW/2.png">2.png</a></td><td></td><td><a href="/administration/organization-users">Administration</a></td></tr></tbody></table>


# Concepts

This page introduces the core concepts and terminology used throughout the Waterflai platform. Understanding these concepts will help you navigate the platform more effectively.

### Fundamental Concepts

#### AI Model

An AI model is a trained machine learning system capable of performing specific tasks, such as generating text, answering questions, or analyzing data. Waterflai supports various types of AI models, with a focus on Large Language Models (LLMs).

#### Provider

A provider is a service that offers access to one or more AI models. Examples include OpenAI, Mistral AI, Google, and Anthropic. Waterflai allows you to connect to multiple providers, giving you flexibility in choosing the best model for your needs.

#### Knowledge Base

A knowledge base is a collection of information that can be used to enhance the capabilities of AI models. In Waterflai, you can create and manage knowledge bases to provide context and domain-specific information to your AI applications.

#### Chatbot

A chatbot is an AI-powered conversational interface that can interact with users in natural language. Waterflai provides tools to create and customize chatbots for various purposes, from customer support to data analysis.

#### Workflow

A workflow in Waterflai is a series of interconnected steps that define a process or task. Workflows can combine AI model interactions, data processing, and integrations with external systems to create complex, automated processes.

#### Vector Store

A vector store is a specialized database designed to store and efficiently retrieve high-dimensional vectors. In the context of AI and Waterflai:

* **Purpose**: Vector stores are crucial for managing and searching large collections of embeddings, which are numerical representations of data (text, images, etc.).
* **Functionality**: They allow for fast similarity searches, enabling AI applications to find and retrieve the most relevant information quickly.
* **Use in** Waterflai: Vector stores are often used in conjunction with knowledge bases to enhance the retrieval of context-relevant information for AI models.

#### Embeddings

Embeddings are dense vector representations of data in a high-dimensional space. In the context of AI and natural language processing:

* **Definition**: An embedding is a way to represent words, sentences, or any piece of data as a list of numbers (a vector).
* **Properties**:
  * Captures semantic meaning: Similar concepts have similar embeddings.
  * Enables mathematical operations: You can perform calculations on embeddings to find relationships between concepts.
* **Applications in** Waterflai:
  * **Semantic Search**: Improve the relevance of search results in knowledge bases.
  * **Content Recommendation**: Suggest related content or responses based on similarity.
  * **Language Understanding**: Enhance the AI model's comprehension of user queries and context.
  * **Data Preprocessing**: Transform raw text data into a format that AI models can process more effectively.

#### Importance of Vector stores and embeddings

Understanding vector stores and embeddings is crucial for leveraging the full potential of Waterflai:

1. **Enhanced Retrieval**: By using embeddings and vector stores, your AI applications can quickly find and utilize the most relevant information from large datasets.
2. **Improved Accuracy**: Embeddings capture nuanced relationships between concepts, leading to more accurate and contextually appropriate AI responses.
3. **Scalability**: Vector stores efficiently manage large volumes of embedded data, allowing your applications to scale with growing knowledge bases.
4. **Cross-lingual Capabilities**: Some embedding models support multiple languages, enabling AI applications to work across language barriers.

### Waterflai Platform Components

#### Providers Space

The Providers Space is where you manage your connections to various AI model providers. Here, you can set up API keys, select models, and configure provider-specific settings.

#### Knowledge Space

The Knowledge Space is dedicated to creating, importing, and managing your knowledge bases. This is where you organize information that will be used to augment your AI applications.

#### Studio Space

The Studio Space is the heart of Waterflai, where you build your AI applications. It includes tools for creating chatbots, designing workflows, and testing your creations.

#### Analytics Space

The Analytics Space provides insights into your AI applications' performance and usage. Here, you can view dashboards, analyze logs, and gather data to optimize your applications.

### Key Features

#### No-Code Interface

Waterflai's no-code interface allows you to create AI applications using visual tools, without writing complex code. This includes drag-and-drop components, visual workflow builders, and intuitive configuration panels.

#### Flow Components

Flow components are the building blocks of workflows in Waterflai. These pre-built modules perform specific functions, such as calling an AI model, processing data, or integrating with external services.

#### Knowledge Connector

A knowledge connector is a tool that allows you to link your knowledge bases to your AI applications. This enables your applications to access and utilize specific information during interactions.

#### Publishing

Publishing in Waterflai refers to the process of making your AI application available for use. This can involve deploying a chatbot to a website, exposing a workflow as an API, or integrating your application with other systems.

#### Embedding

Embedding allows you to integrate Waterflai-built applications into your existing websites or applications. This feature enables seamless incorporation of AI capabilities into your digital products.

### Administrative Concepts

#### Organization

An organization in Waterflai represents a company or group that uses the platform. It encompasses all the users, workspaces, and resources associated with that entity.

#### Workspace

A workspace is a dedicated environment within your organization where specific projects or teams can work on AI applications. Workspaces help organize your work and manage access to resources.

#### User Roles

Waterflai supports different user roles (e.g., Admin, Creator, User) to manage access and permissions within your organization and workspaces.

Understanding these concepts will provide you with a solid foundation as you explore and use the Waterflai platform. As you progress through the documentation, you'll learn how these concepts come together to help you create powerful AI applications.


# Quickstart

Discover the product through our interactive tour!

{% embed url="<https://app.guideflow.com/player/lpnzm1lsjp>" %}


# Editor

GitBook has a powerful block-based editor that allows you to seamlessly create, update, and enhance your content.

<figure><img src="https://gitbookio.github.io/onboarding-template-images/editor-hero.png" alt=""><figcaption></figcaption></figure>

### Writing content

GitBook offers a range of block types for you to add to your content inline — from simple text and tables, to code blocks and more. These elements will make your pages more useful to readers, and offer extra information and context.

Either start typing below, or press `/` to see a list of the blocks you can insert into your page.


# Interactive blocks

In addition to the default Markdown you can write, GitBook has a number of out-of-the-box interactive blocks you can use. You can find interactive blocks by pressing `/` from within the editor.

<figure><img src="https://gitbookio.github.io/onboarding-template-images/interactive-hero.png" alt=""><figcaption></figcaption></figure>

### Tabs

{% tabs %}
{% tab title="First tab" %}
Each tab is like a mini page — it can contain multiple other blocks, of any type. So you can add code blocks, images, integration blocks and more to individual tabs in the same tab block.
{% endtab %}

{% tab title="Second tab" %}
Add images, embedded content, code blocks, and more.

```javascript
const handleFetchEvent = async (request, context) => {
    return new Response({message: "Hello World"});
};
```

{% endtab %}
{% endtabs %}

### Expandable sections

<details>

<summary>Click me to expand</summary>

Expandable blocks are helpful in condensing what could otherwise be a lengthy paragraph. They are also great in step-by-step guides and FAQs.
</details>

### Drawings

<img alt="" class="gitbook-drawing">

### Embedded content

{% embed url="<https://www.youtube.com/watch?v=YILlrDYzAm4>" %}

{% hint style="info" %}
GitBook supports thousands of embedded websites out-of-the-box, simply by pasting their links. Feel free to check out which ones[ are supported natively](https://iframely.com).
{% endhint %}


# OpenAPI

You can sync GitBook pages with an OpenAPI or Swagger file or a URL to include auto-generated API methods in your documentation.

### OpenAPI block

GitBook's OpenAPI block is powered by [Scalar](https://scalar.com/), so you can test your APIs directly from your docs.

{% openapi src="<https://petstore3.swagger.io/api/v3/openapi.json>" path="/pet" method="post" %}
<https://petstore3.swagger.io/api/v3/openapi.json>
{% endopenapi %}


# Integrations

GitBook integrations allow you to connect your GitBook spaces to some of your favorite platforms and services. You can install integrations into your GitBook page from the *Integrations* menu in the top left.

<figure><img src="https://gitbookio.github.io/onboarding-template-images/integrations-hero.png" alt=""><figcaption></figcaption></figure>

### Types of integrations

<table data-card-size="large" data-view="cards"><thead><tr><th></th><th></th><th data-hidden data-card-target data-type="content-ref"></th><th data-hidden data-card-cover data-type="files"></th><th data-hidden></th></tr></thead><tbody><tr><td><strong>Analytics</strong></td><td>Track analytics from your docs</td><td><a href="https://www.gitbook.com/integrations#analytics">https://www.gitbook.com/integrations#analytics</a></td><td><a href="https://content.gitbook.com/content/GxqXoeVSKzSmLzXgA3zn/blobs/TemqzIECRtBPKyphZmgW/2.png">2.png</a></td><td></td></tr><tr><td><strong>Support</strong></td><td>Add support widgets to your docs</td><td><a href="https://www.gitbook.com/integrations#support">https://www.gitbook.com/integrations#support</a></td><td><a href="https://content.gitbook.com/content/GxqXoeVSKzSmLzXgA3zn/blobs/3pMD12MaJ2Ougks0TaRz/3.png">3.png</a></td><td></td></tr><tr><td><strong>Interactive</strong></td><td>Add extra functionality to your docs</td><td><a href="https://www.gitbook.com/integrations#interactive">https://www.gitbook.com/integrations#interactive</a></td><td><a href="https://content.gitbook.com/content/GxqXoeVSKzSmLzXgA3zn/blobs/FY1K1KEwcQiSASHH3OvI/4.png">4.png</a></td><td></td></tr><tr><td><strong>Visitor Authentication</strong></td><td>Protect your docs and require sign-in</td><td><a href="https://www.gitbook.com/integrations#visitor-authentication">https://www.gitbook.com/integrations#visitor-authentication</a></td><td><a href="https://content.gitbook.com/content/GxqXoeVSKzSmLzXgA3zn/blobs/tdCMeyjKeLsTMblkYjvL/1.png">1.png</a></td><td></td></tr></tbody></table>


# Providers Overview

Welcome to the Providers section of Waterflai's documentation. This section is your guide to understanding, connecting, and effectively using various AI model providers within the Waterflai platform.

### What are Providers in Waterflai?

In Waterflai, providers are the services that offer access to AI models, particularly Large Language Models (LLMs). These providers form the foundation of your AI applications, enabling you to leverage state-of-the-art AI capabilities in your projects.

### What You'll Learn in This Section

* How to set up and manage connections to different AI model providers
* Understanding the various AI models available and their capabilities
* Guidance on choosing the right models for your specific use cases
* Best practices for working with multiple providers

### Key Topics

* **Providers Space**: Learn how to navigate and use the dedicated area for managing your provider connections.
* **Providers Setup**: Step-by-step guides on setting up connections to popular providers like OpenAI, Google, and Anthropic.
* **AI Models**: Detailed information about the different types of AI models available through various providers.
* **Choosing the Right Models**: Strategies and considerations for selecting the most appropriate models for your projects.

Whether you're new to working with AI providers or looking to optimize your use of multiple models, this section will equip you with the knowledge to make the most of Waterflai's multi-provider support.

Let's begin by exploring the Providers Space and setting up your first provider connection!


# Providers setup

This page will guide you through the process of setting up and managing AI providers in Waterflai.

### Adding a New Provider

To add a new AI provider to your Waterflai workspace:

1. Navigate to the Providers page in your Waterflai dashboard.
2. Click the "Add Provider" button.
3. In the provider selection modal, you'll see a grid of available provider types.
4. Use the search bar at the top to filter providers if needed.
5. Click on the provider card you wish to add.
6. Fill out the provider-specific form with the required details (e.g., API keys, endpoints).
7. Click "Save" to create the new provider connection.

### Managing Existing Providers

Once you've added providers, you can manage them from the Providers table:

#### Viewing Providers

* The Providers table displays all your connected providers.
* Each row shows the provider's name and logo for easy identification.

#### Importing Models

To import models from a provider:

1. Click the brain icon next to the provider in the table.
2. Select the models you wish to import in the modal that appears.
3. Click "Import" to add the selected models to your workspace.

#### Editing a Provider

To edit a provider's settings:

1. Click the three-dot menu at the end of the provider's row.
2. Select "Edit" from the dropdown menu.
3. Update the provider's details in the form that appears.
4. Click "Save" to apply your changes.

#### Deleting a Provider

To remove a provider:

1. Click the three-dot menu at the end of the provider's row.
2. Select "Delete" from the dropdown menu.
3. Confirm the deletion in the confirmation dialog.

> **Note:** Deleting a provider will remove access to its models. Ensure you're not using any of the provider's models in active projects before deletion.

### Provider-Specific Setup

Each provider may have unique setup requirements. Here are some general guidelines:

* **API Keys**: Most providers require an API key. Ensure you have an account with the provider and have generated an API key before adding the provider to Waterflai.
* **Endpoints**: Some providers, especially self-hosted ones, may require you to specify an endpoint URL.
* **Model Selection**: Certain providers allow you to select which models you want to use. Make sure you have the necessary permissions for the models you select.

### Best Practices

1. **Security**: Store API keys securely and never share them.
2. **Testing**: After adding a provider, test the connection by importing and using a model.
3. **Monitoring**: Regularly check your provider usage to manage costs and performance.
4. **Updates**: Keep an eye out for provider updates that may require changes to your setup.

By following these instructions, you'll be able to efficiently set up and manage your AI providers in Waterflai, enabling you to leverage a wide range of AI models for your applications.


# AI models

This page explains how to manage AI models in Waterflai. Models are the core components that power your AI applications, and Waterflai provides flexible ways to import and create models.

### Viewing Models

The Models table displays all the AI models available in your workspace. Each model entry includes:

* Name of the model
* Provider logo
* Model type (e.g., Text Generation, Embeddings, Reranker)
* A truncated description (hover over it to see the full description)

### Adding Models

Waterflai offers two primary methods for adding models to your workspace:

#### 1. Quick Import from Provider

This method allows you to quickly import multiple models from a configured provider.

1. In the Providers table, locate the provider you want to import models from.
2. Click the brain icon next to the provider's name.
3. In the Import Models modal:
   * You'll see a list of available models not yet imported.
   * For each model, select its type from the dropdown (if not automatically detected).
   * Click "Add" for each model you want to import.
4. The selected models will be immediately added to your workspace.

#### 2. Manual Model Creation

This method allows for more detailed configuration of individual models.

1. Click the "Add Model" button above the Models table.
2. In the Model Form modal:
   * Select the Provider from the dropdown.
   * Choose the specific Model from the provider's available models.
   * The Model Type will be auto-selected if detected, or you can manually choose it.
   * Enter a Name for the model (auto-filled with the provider's model name, but you can customize it).
   * Optionally, add or edit the Description.
3. Click "Create" to add the model to your workspace.

### Managing Models

#### Editing a Model

1. In the Models table, click the three-dot menu at the end of the model's row.
2. Select "Edit" from the dropdown menu.
3. In the Edit Model modal, you can modify the model's name and description.
4. Click "Save" to apply your changes.

#### Deleting a Model

1. In the Models table, click the three-dot menu at the end of the model's row.
2. Select "Delete" from the dropdown menu.
3. Confirm the deletion in the confirmation dialog.

> **Note:** Deleting a model will remove it from your workspace. Ensure the model isn't being used in any active projects before deletion.

### Best Practices

1. **Naming Convention**: Use clear, descriptive names for your models to easily identify their purpose or capabilities.
2. **Descriptions**: Provide detailed descriptions for your models, including their strengths, limitations, and ideal use cases.
3. **Regular Review**: Periodically review your model list to remove unused models and keep your workspace organized.
4. **Testing**: After adding a new model, test it in a sample project to ensure it performs as expected.

By following these instructions, you'll be able to efficiently manage AI models in your Waterflai workspace, enabling you to leverage a wide range of AI capabilities for your applications.


# Choose the right models

Selecting the appropriate AI models is crucial for achieving optimal performance and efficiency. This guide will help you navigate the process of choosing the right models in Waterflai.

### Understanding Model Types

Waterflai supports three main types of AI models:

1. **LLM (Text Generation)**: For creating human-like text, powering chatbots, and generating content.
2. **Text Embedding**: For converting text into numerical vectors, useful for semantic search and text similarity tasks.
3. **Reranker**: For improving search results by reordering a list of items based on their relevance to a query.

### Factors to Consider

When choosing a model, consider the following factors:

#### 1. Task Compatibility

* Ensure the model type aligns with your project's requirements.
* Some models are multi-purpose, while others are specialized for specific tasks.

#### 2. Performance

* Consider the model's accuracy, speed, and output quality for your specific use case.
* Larger models often provide better results but may be slower.

#### 3. Cost

* Different providers and models have varying pricing structures.
* Balance performance needs with budget constraints.

#### 4. Latency

* For real-time applications, prioritize models with lower latency.
* Consider the trade-off between response time and output quality.

#### 5. Ethical Considerations

* Be aware of any biases or limitations in the model's training data.
* Consider the model's impact on privacy and security.

#### 6. Model Specificities

* **Context Window**: For LLMs, consider the maximum length of text the model can process or generate. Longer context windows allow for more comprehensive understanding and generation but may increase processing time and cost.
* **Intelligence Level**: Evaluate the model's capability to understand complex queries, generate nuanced responses, or perform reasoning tasks.
* **Tool Use Capability**: For building agents, check if the model can effectively use tools or follow specific formats for tool use. This is crucial for creating AI agents that can interact with external systems or perform complex multi-step tasks.

#### 7. Specialized Capabilities

* Some models may have unique features or strengths in certain areas (e.g., multi-lingual support, code generation, mathematical reasoning).
* Consider these specializations when they align with your project needs.

### Comparison Strategies

To choose between similar models:

1. **Benchmark Testing**: Create a test set representative of your use case and compare model performance.
2. **A/B Testing**: If feasible, deploy multiple models and compare their real-world performance.
3. **Community Feedback**: Research user experiences and benchmarks shared by the AI community.

### Model Selection Process

1. **Define Requirements**: Clearly outline your project's needs and constraints.
2. **Shortlist Candidates**: Identify models that meet your basic criteria.
3. **Evaluate Options**: Use the factors above to compare shortlisted models.
4. **Test and Validate**: Conduct hands-on testing with sample data.
5. **Monitor and Iterate**: After deployment, continuously monitor performance and be prepared to switch or upgrade models as needed.

### Best Practices

1. **Start Simple**: Begin with simpler, well-documented models before moving to more complex ones.
2. **Combine Models**: For complex tasks, consider using multiple specialized models (e.g., an LLM for generation, a separate embedding model for search, and a reranker for result optimization).
3. **Stay Updated**: Keep track of new model releases and updates from providers.
4. **Document Decisions**: Maintain a record of why specific models were chosen for different parts of your project.
5. **Consider Ensemble Methods**: In some cases, combining outputs from multiple models can yield better results.

### Waterflai-Specific Tips

1. **Utilize Model Descriptions**: In Waterflai, hover over model names to view detailed descriptions, which can aid in selection.
2. **Leverage Provider Information**: The provider logo next to each model can give insights into the model's origin and potential strengths.
3. **Use Model Types**: Filter models by type in Waterflai to quickly find models suitable for your specific task (LLM, Text Embedding, or Reranker).
4. **Experiment with Import**: Use Waterflai's quick import feature to easily try out multiple models from a provider.
5. **Check Tool Compatibility**: When building agents, ensure the chosen LLM supports tool use and is compatible with Waterflai's agent-building features.

By carefully considering these factors and following this guide, you'll be better equipped to choose the right models for your AI projects in Waterflai, ensuring optimal performance and efficiency across text generation, embedding, and reranking tasks.


# Knowledge Overview

Welcome to the Knowledge section of Waterflai's documentation. This section will guide you through the process of creating, managing, and leveraging knowledge bases to enhance your AI applications.

### What is Knowledge Management in Waterflai?

Knowledge management in Waterflai refers to the tools and processes that allow you to incorporate your own data and information into your AI applications. By doing so, you can create more accurate, context-aware, and specialized AI solutions.

### What You'll Learn in This Section

* How to create and organize knowledge bases within Waterflai
* Techniques for importing and structuring your data
* Methods for connecting your knowledge bases to AI models
* Strategies for maintaining and updating your knowledge over time

### Key Topics

* **Knowledge Space**: An introduction to the dedicated area for managing your knowledge bases.
* **Knowledge Connectors**: Learn about the tools that link your knowledge bases to your AI applications.
* **Knowledge Collections**: Understand how to organize and categorize your information for optimal use.

Whether you're looking to create a specialized chatbot with domain-specific knowledge or enhance your AI workflows with proprietary data, this section will show you how to harness the full power of your information within Waterflai.

Let's start by exploring the Knowledge Space and creating your first knowledge base!


# Knowledge connectors

This page will guide you through the process of setting up and managing connectors.

### Adding a New Connector

To add a new Knowledge Connector to your Waterflai workspace:

1. Navigate to the Knowledge page in your Waterflai dashboard.
2. Click the "Add Connector" button in the Connectors section.
3. In the connector selection modal, you'll see a grid of available connector types.
4. Use the search bar at the top to filter connectors if needed.
5. Click on the connector card you wish to add.
6. Fill out the connector-specific form with the required details (e.g., API keys, endpoints).
7. Click "Save" to create the new connector.

### Managing Existing Connectors

Once you've added connectors, you can manage them from the Connectors table:

#### Viewing Connectors

* The Connectors table displays all your connected data sources.
* Each row shows the connector's name and logo for easy identification.

#### Editing a Connector

To edit a connector's settings:

1. Click the three-dot menu at the end of the connector's row.
2. Select "Edit" from the dropdown menu.
3. Update the connector's details in the form that appears.
4. Click "Save" to apply your changes.

#### Deleting a Connector

To remove a connector:

1. Click the three-dot menu at the end of the connector's row.
2. Select "Delete" from the dropdown menu.
3. Confirm the deletion in the confirmation dialog.

> **Note:** Deleting a connector will remove access to its associated data. Ensure you're not using the connector in any active collections before deletion.

### Supported Connectors

Waterflai supports several types of connectors, including:

* ChromaDB
* Milvus
* Pinecone
* Qdrant
* Zilliz

Each connector type has its own specific configuration requirements. Be sure to have the necessary credentials and information ready when setting up a new connector.

### Best Practices

1. **Security**: Store API keys and sensitive information securely.
2. **Testing**: After adding a connector, test the connection by creating a sample collection.
3. **Monitoring**: Regularly check your connector status to ensure continued access to your data sources.
4. **Documentation**: Keep track of the purpose and contents of each connector for easier management.

By following these instructions, you'll be able to effectively set up and manage Knowledge Connectors in Waterflai, enabling your AI applications to access and utilize a wide range of data sources.


# Knowledge collections

Knowledge Collections in Waterflai are organized sets of data that your AI applications can use as a knowledge base. This page will guide you through the process of creating and managing collections.

### Creating a New Collection

To create a new Knowledge Collection in your Waterflai workspace:

1. Navigate to the Knowledge page in your Waterflai dashboard.
2. Click the "Add Collection" button in the Collections section.
3. You'll be taken through a three-step process:

   Step 1: Source Selection

   * Choose the connector (data source) for your collection.

   Step 2: Collection Configuration

   * Configure the collection settings specific to the chosen connector.
   * Select an embeddings model for your collection.

   Step 3: Finalize

   * Provide a name and description for your collection.
4. Click "Save" to create the new collection.

### Managing Existing Collections

Once you've created collections, you can manage them from the Collections table:

#### Viewing Collections

* The Collections table displays all your knowledge collections.
* Each row shows the collection's name, a truncated description, and the associated connector type.

#### Editing a Collection

To edit a collection's settings:

1. Click on the collection name in the table.
2. You'll be taken to the collection edition page where you can modify all settings.
3. Navigate through the steps using the "Next" and "Back" buttons.
4. Click "Save" when you're done to apply your changes.

#### Deleting a Collection

To remove a collection:

1. Click the three-dot menu at the end of the collection's row.
2. Select "Delete" from the dropdown menu.
3. Confirm the deletion in the confirmation dialog.

> **Note:** Deleting a collection will permanently remove its data. Ensure you no longer need the collection before deletion.

### Collection Preview

When creating or editing a collection, you'll see a preview panel on the right side of the screen. This preview feature is a powerful tool designed to help you configure your collection accurately.

### Embeddings Models

When creating or editing a collection, you'll sometimes need to select an embeddings model (specially when using vector store). This model is used to convert your data into vector representations, enabling efficient similarity search and retrieval.

### Best Practices

1. **Naming**: Use clear, descriptive names for your collections to easily identify their purpose or contents.
2. **Description**: Provide detailed descriptions for your collections, including information about the data source and intended use.
3. **Regular Review**: Periodically review your collections to ensure they contain up-to-date and relevant information.
4. **Testing**: After creating or modifying a collection, test it in a sample project to ensure it performs as expected.

By following these instructions, you'll be able to effectively create and manage Knowledge Collections in Waterflai, providing your AI applications with rich, organized data sources to enhance their capabilities.


# Studio Overview

Welcome to the Studio section of Waterflai's documentation. The Studio is where your AI ideas come to life, providing you with powerful tools to create, test, and refine your AI applications.

### What is the Waterflai Studio?

The Waterflai Studio is a comprehensive no-code environment where you can build a wide range of AI applications, from simple chatbots to complex, multi-step workflows. It's designed to be intuitive for beginners while offering the flexibility and power that advanced users need.

### What You'll Learn in This Section

* How to navigate and use the Studio interface
* Techniques for creating various types of AI applications
* Methods for testing and debugging your creations
* Strategies for publishing and integrating your AI solutions

### Key Topics

1. **Studio Space**: An overview of the main workspace where you'll build your AI applications.
2. **Chatbots and Workflows**:
   * Creating basic chatbots
   * Designing customized flows
   * Building powerful workflows
   * Understanding and using flow components
   * Techniques for testing and debugging
3. **Publishing**: Learn how to make your AI applications available for use.
4. **Integration**: Explore methods for integrating your Waterflai-built solutions with external systems and websites.

Whether you're looking to create a simple Q\&A bot or a sophisticated AI-powered business process, this section will guide you through every step of the development process in Waterflai's Studio.

Let's dive in and start building your first AI application in the Waterflai Studio!


# Studio Builders

Welcome to the Chatbots and Workflows section of Waterflai's Studio. This is where you can create, manage, and deploy various types of AI-powered applications.

### Overview

Waterflai's Studio offers three main types of builders:

1. **Light Builder**: Straightforward chatbots for basic conversational interactions.
2. **Dream builder**: Advanced chatbots with complex conversation flows and logic.
3. **Workflow Builder**: Automated processes that can integrate AI with various tasks and systems.

### Creating a New Application

To create a new chatbot or workflow:

1. Click the "Create" button in the top right corner of the Studio page.
2. Choose the type of builder you want use:
   * Light Builder - to make fast POC's, or building basic chatbots.
   * Dream Builder - to build any AI solution you can image (AI agent, features, ...)
   * Workflow Builder - to automate processes (build a vector store)
3. Enter a name and optional description for your application.
4. By default, the usage of the application in production context are logged (including the message) and accessible under the Analytics (Logs) section of Waterflai. Uncheck the `Conversation Analytics` field to not store the inputs and outputs.
5. Click "Create" to generate your new application.

### Managing Your Applications

The Studio page displays a grid of cards, each representing one of your chatbots or workflows. Each card shows:

* The application's name
* A badge indicating the builder type used (Light, Dream, or Workflow)
* A truncated description (if provided)

#### Actions Available:

* **Edit Configuration**: Click on the card to open the configuration page for that application.
* **Integration Guide**: Click the code icon to view integration instructions for using the application via API.
* **Embedding Guide**: For chatbots built with the Light or Dream builder, click the globe icon to see how to embed the chatbot in a website.
* **More Options**: Click the three-dot menu to access additional actions:
  * Edit Information: Modify the name and description.
  * Publish: Make the latest version of your application live.
  * Duplicate: duplicate the app.
  * Delete: Remove the application from your workspace.

You can find more informations on those actions within pages of "Studio" section.

### Filtering and Searching

You can easily find specific applications using the following features:

* **Type Filters**: Use the buttons at the top to show All, Light, Dream, or Workflow applications.
* **Search**: Use the search bar to find applications by name.

### Best Practices

1. **Naming Convention**: Use clear, descriptive names for your chatbots and workflows.
2. **Regular Testing**: Frequently test your applications, especially after making changes.
3. **Version Control**: Consider creating new versions of your applications for significant changes.
4. **Documentation**: Maintain internal documentation about the purpose and functionality of each of your applications.

By leveraging these tools and features in Waterflai's Studio, you can efficiently create, manage, and deploy sophisticated AI-powered chatbots and workflows tailored to your specific needs.


# Light Builder

The Light Builder allows you to create straightforward, yet powerful conversational AI applications. This page guides you through the process of configuring and testing your basic chatbot.

Cost: 1 credit for basic chatbot (without knowledge usage), and 2 credits for a RAG chatbot (with knowledge usage).

### Configuration

When you create or edit a basic chatbot, you'll see a configuration form with the following options:

#### Model Selection

1. **Primary Model**:
   * Select the main AI model for your chatbot.
   * Choose from a list of available models connected to your configured providers.
2. **Fallback Model** (Optional):
   * Select a secondary model to use if the primary model fails or is unavailable.
   * You can choose "None" if you don't want to use a fallback model.

#### Instruction

* Provide specific instructions or prompts for your chatbot.
* This sets the context and behavior for your chatbot's responses.
* Use this to define the chatbot's personality, knowledge base, or specific tasks it should perform.

#### Knowledge Integration

1. **Use Knowledge**:
   * Toggle this option to enable or disable the use of additional knowledge bases.
2. **Knowledge Collections**:
   * If "Use Knowledge" is enabled, you can select one or more knowledge collections to enhance your chatbot's responses.
   * These collections can provide domain-specific information to make your chatbot more informative and contextually aware.

### Live Experimentation

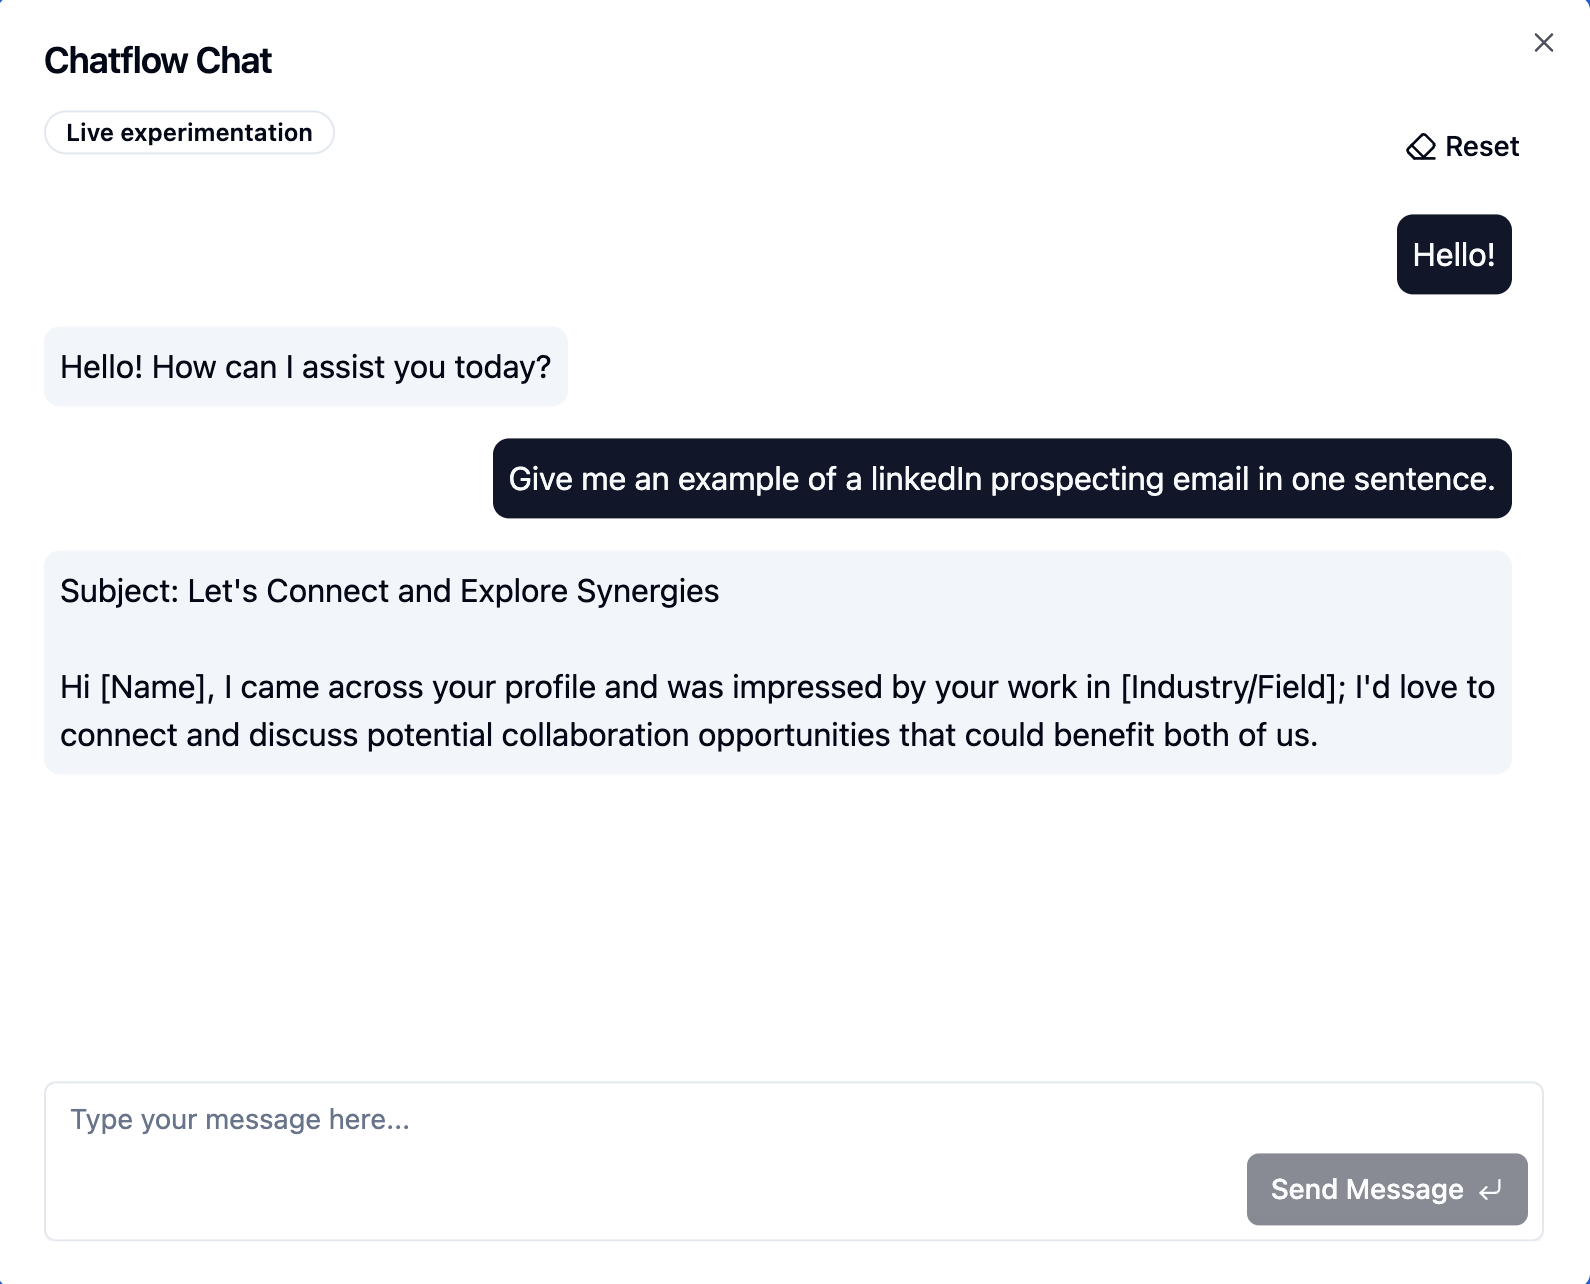
The Basic Chatbot configuration page includes a live chat interface for immediate testing:

* **Chat Interface**: Interact with your chatbot in real-time to test its responses based on your current configuration.
* **Reset Conversation**: Clear the chat history to start a fresh conversation.
* **Stop Generation**: Interrupt the chatbot's response generation if needed.

### Saving and Publishing

* **Save**: Updates your chatbot configuration without making it live.
* **Save and Publish**: Updates the configuration and makes the latest version of your chatbot available for use.

### Best Practices

1. **Clear Instructions**: Provide detailed and clear instructions to guide your chatbot's behavior effectively.
2. **Test Thoroughly**: Use the live chat interface to test various scenarios and refine your configuration.
3. **Iterative Improvement**: Start with a basic setup and gradually enhance your chatbot based on testing results.
4. **Knowledge Integration**: Carefully select relevant knowledge collections to improve the chatbot's domain-specific knowledge without overwhelming it.
5. **Fallback Strategy**: Consider using a fallback model for improved reliability, especially for critical applications.

### Tips for Effective Basic Chatbots

* **Define Purpose**: Clearly define the primary purpose of your chatbot (e.g., customer service, information retrieval, task assistance).
* **Personality**: Use the instruction field to give your chatbot a consistent personality that aligns with your brand or use case.
* **Handle Edge Cases**: Test and provide instructions for handling off-topic queries or sensitive information requests.
* **Monitor and Update**: Regularly review chatbot interactions and update your configuration to improve performance over time.

By leveraging these configuration options and best practices, you can create effective and engaging Basic Chatbots tailored to your specific needs using Waterflai.


# Dream Builder

The Dream Builder allows you to create sophisticated, multi-step conversational AI applications using a visual, flow-based interface. This page guides you through the process of creating, configuring, and testing your flow.

### Builder interface Overview

The Builder is divided into several key areas:

1. **Left Panel**: Contains a list of available components you can use in your flow.
2. **Main Canvas**: The central area where you build your flow by adding and connecting nodes.
3. **Action Buttons**: Located at the top, these buttons allow you to save, publish, and test your flow.
4. **Configuration Popover**: Appears when you select a node, allowing you to configure its specific settings.
5. **Execution Detail Panel**: Shows detailed information about the execution of your flow during testing.

### Creating a flow

1. **Start with a Template or Blank Canvas**:
   * When creating a new flow, you can choose from pre-built templates or start with a blank canvas.
   * Templates provide a quick starting point for common flow patterns.
2. **Add Components**:
   * Drag components from the Left Panel onto the Main Canvas.
   * Available components include for example (not exhaustive list):
     * Input Node
     * LLM Model Node
     * Agent Node
     * Knowledge Retrieval Node
     * Vector Store Insert Node
     * Various Loader Nodes (GitBook, Notion DB, Figma, Web Scraper)
     * Text Splitter Nodes
     * Reranker Node
     * Calculator Tool Node
     * Output Node
3. **Connect Nodes**:
   * Click and drag from one node's output to another node's input to create connections.
   * The flow of data and logic follows these connections.
4. **Configure Nodes**:
   * Click on a node to open its Configuration Popover.
   * Set parameters specific to each node type (e.g., model selection for LLM nodes, instructions for agents).

{% hint style="info" %}
**Mandatory nodes**: A flow built with Dream Builder must have one **Input** and one **Output** node.
{% endhint %}

{% hint style="info" %}
**Variable reference**: you can refer to parent nodes output through variables that can be inserted by using the **(x)** button next to compatible fields.
{% endhint %}

### Testing Your Flow

1. **Open Mini Chat**:
   * Click the "Chat" button in the Action Buttons area to open the testing interface.
2. **Interact with your flow**:
   * Send messages to test the behavior of your flow.
   * Observe how different nodes process and respond to inputs.
3. **View Execution Details**:
   * The Execution Detail Panel shows how data flows through your nodes during testing.
   * Use this information to debug and optimize your flow.

### Saving and Publishing

* **Save**: Updates your flow configuration without making it live.
* **Save and Publish**: Updates the configuration and makes the latest version of your flow available for use.

### Best Practices

1. **Start Simple**: Begin with a basic flow and gradually add complexity.
2. **Use Templates**: Leverage pre-built templates to quickly set up common patterns.
3. **Test Thoroughly**: Use the Mini Chat to test various scenarios and edge cases.
4. **Optimize Node Order**: Arrange nodes efficiently to minimize unnecessary processing.
5. **Document Your Flow**: Use clear node names and annotations to make your flow easy to understand.

### Advanced Features

* **Knowledge Integration**: Use Knowledge Retrieval nodes to incorporate external data sources.
* **Multi-Step Reasoning**: Combine LLM and Agent nodes for complex decision-making processes.
* **Dynamic Responses**: Utilize different output paths based on user inputs or AI decisions.

### Troubleshooting

* If a node is not behaving as expected, check its configuration in the Configuration Popover.
* Use the Execution Detail Panel to trace the flow of data and identify where issues might be occurring.
* Ensure all required fields in node configurations are filled correctly.

By leveraging the power of flows through the Dream Builder in Waterflai, you can create highly customized and intelligent conversational experiences that go beyond simple question-answering.


# Workflow Builder

The Workflow Builder allows you to create sophisticated, automated processes (e.g. vector store data ingestion, ...) that can integrate AI with various tasks and systems. This page guides you through the process of creating, configuring, and testing your workflows.

### Workflow interface Overview

The builder is divided into several key areas:

1. **Left Panel**: Contains a list of available components you can use in your workflow.
2. **Main Canvas**: The central area where you build your workflow by adding and connecting nodes.
3. **Action Buttons**: Located at the top, these buttons allow you to save, publish, and test your workflow.
4. **Configuration Popover**: Appears when you select a node, allowing you to configure its specific settings.
5. **Execution Detail Panel**: Shows detailed information about the execution of your workflow during testing.

### Creating a Workflow

1. **Start with a Template or Blank Canvas**:
   * When creating a new workflow, you can choose from pre-built templates or start with a blank canvas.
   * Templates provide a quick starting point for common workflow patterns.
2. **Add Components**:
   * Drag components from the Left Panel onto the Main Canvas.
   * Available components include various node types such as Input, LLM Model, Knowledge Retrieval, and more.
3. **Connect Nodes**:
   * Click and drag from one node's output to another node's input to create connections.
   * The flow of data and logic follows these connections.
4. **Configure Nodes**:
   * Click on a node to open its Configuration Popover.
   * Set parameters specific to each node type (e.g., model selection for LLM nodes, query parameters for knowledge retrieval).

### Testing Your Workflow

1. **Open Workflow Runner**:
   * Click the "Run" button in the Action Buttons area to open the testing interface.
2. **Input Data**:
   * If your workflow has an Input node, you can enter data in the main input field.
   * For additional inputs defined in your workflow, use the "Additional Inputs" section.
3. **Execute Workflow**:
   * Click "Execute Workflow" to run your workflow with the provided inputs.
   * Observe the output and any error messages in the runner interface.
4. **View Execution Details**:
   * The Execution Detail Panel shows how data flows through your nodes during testing.
   * Use this information to debug and optimize your workflow.

### Saving and Publishing

* **Save**: Updates your workflow configuration without making it live.
* **Save and Publish**: Updates the configuration and makes the latest version of your workflow available for use.

### Best Practices

1. **Start Simple**: Begin with a basic workflow and gradually add complexity.
2. **Use Templates**: Leverage pre-built templates to quickly set up common patterns.
3. **Test Thoroughly**: Use the Workflow Runner to test various scenarios and edge cases.
4. **Optimize Node Order**: Arrange nodes efficiently to minimize unnecessary processing.
5. **Document Your Flow**: Use clear node names and annotations to make your workflow easy to understand.

### Troubleshooting

* If a node is not behaving as expected, check its configuration in the Configuration Popover.
* Use the Execution Detail Panel to trace the flow of data and identify where issues might be occurring.
* Ensure all required fields in node configurations are filled correctly.
* Check for any error messages in the Workflow Runner output for specific issues during execution.

By leveraging the power of Workflows in Waterflai, you can create complex, automated processes that integrate AI capabilities with your existing systems and data sources.


# Flow components (nodes)

Flow Components are the building blocks used within Waterflai's flow builder to create AI-powered applications. Each component (node) serves a specific purpose and can be connected to form complex data processing and AI interaction flows.

### Data Types

Before diving into specific components, it's important to understand the core data types used throughout the flows:

#### Basic Types

* `string`: Text values
* `number`: Numeric values
* `boolean`: True/false values
* `object`: JavaScript/JSON objects
* `any`: Any type of value

#### Array Types

* `string[]`: Array of text values
* `number[]`: Array of numeric values
* `boolean[]`: Array of boolean values
* `object[]`: Array of objects
* `any[]`: Array of any values

#### Special Types

* `Document`: Represents a text document with metadata

  ```typescript
  {
    page_content: string;  // The main content of the document
    metadata: {           // Associated metadata
      [key: string]: any  // Custom key-value pairs
    }
  }
  ```
* `Document[]`: Array of documents
* `ChatMessage[]`: Array of chat messages

  ```typescript
  {
    role: "user" | "assistant" | "system";
    content: string | ChatMessageContent[]; // Either text-only or multimodal content
  }
  ```

Where ChatMessageContent (used mainly in multimodal cases) correspond to:

```
{
  type: "text" | "image_url"; // Type of content
  text?: string; // Text content if type is "text"
  image_url?: { // Image data if type is "image_url"
    [key: string]: any
  }
}
```

* `Tool`: Represents a tool that can be used by an agent

###

### Component Structure

Each component in a flow has:

* Input ports: Accept incoming connections
* Output ports: Provide data to other nodes
* Configuration panel: Settings and parameters
* Documentation: Usage guidelines and examples

### Best Practices

1. **Flow Design**
   * Keep flows modular and focused
   * Use meaningful node names (they should be unique when linked to a given other node, to allow variable reference)
   * Document complex configurations
   * Test flows incrementally
2. **Data Management**
   * Validate input data
   * Consider data volume
3. **Performance**
   * Optimize node configurations
   * Use appropriate batch sizes
   * Monitor execution times

### Common Issues

* Type mismatches between nodes
* Memory limitations
* Configuration errors
* Connection issues
* Resource constraints

Each component's detailed documentation provides specific configuration options, examples, and best practices for that particular node type.


# Input Node

### Overview

The Input Node serves as the entry point for data into your flow. It allows you to define and configure input variables that will be used throughout your flow. The input node automatically includes a mandatory "query" input, which can accept either a string or an array of chat messages, making it versatile for both simple text inputs and complex chat interactions.

Usage cost: 0 credit

### Configuration

#### Settings

1. **Query Input** (Default, non-removable):
   * Type: string or ChatMessage\[]
   * Required: Yes
   * Handles both simple text and chat history
2. **Custom Inputs** (User-defined):
   * Name: Unique identifier for the input
   * Type: Choose from:
     * Basic Types: string, number, boolean, object, any
     * Array Types: string\[], number\[], object\[], ChatMessage\[]
     * Document Types: pdf, pptx, markdown, csv, json, docx, odt
   * Required: Toggle whether the input is mandatory

#### Output

The node dynamically generates outputs based on your configured inputs. By default, it includes:

1. **Default outputs** (always present):
   * `user_message` (string): The latest user message
   * `complete_chat_prompt` (ChatMessage\[]): Full chat history including the latest message
   * `message_history` (ChatMessage\[]): Chat history excluding the latest message
2. **Custom outputs** (based on configured inputs):
   * For regular inputs: Output matches the configured input name and type
   * For file inputs: Creates two outputs per file:
     * `{input_name}_full`: Complete document content
     * `{input_name}_pages`: Array of individual pages/sections

### Best Practices

1. **Naming Conventions**
   * Use clear, descriptive names for inputs
   * Avoid special characters and spaces
2. **Input Organization**
   * Group related inputs together
   * Place required inputs first
   * Keep the number of inputs minimal and focused
3. **Type Selection**
   * Use specific types instead of 'any' when possible


# Output Node

### Overview

The Output Node is the final node in a flow, responsible for formatting and returning the flow's response. It allows you to template your response using variables from previous nodes, making it flexible for various use cases from simple text responses to complex formatted outputs.

Usage cost: 0 credit

### Configuration

#### Settings

* **Response Template** (Required):
  * A text field that supports variable interpolation
  * Can access any variable defined by previous nodes in the flow
* **Output as JSON** (`boolean`, Toggle):
  * **Off (Default):** The node outputs the final result generated from the 'Response Template' as a plain string.
  * **On:** Attempts to parse the final text generated from the 'Response Template' (after variable interpolation) as JSON. If parsing succeeds, the `response` output will contain a JSON object or array. If parsing fails, `response` will contain the raw interpolated string.
    * *Note:* Ensure the template produces valid JSON after variable interpolation when this is enabled.

#### Output

* **response** (string): The final interpolated response string

### Best Practices

1. **Variable Usage**
   * Always validate that required variables exist in the flow


# LLM model Node

### Overview

The LLM Model Node integrates Large Language Models into your flow, enabling natural language processing, generation, and understanding. It supports multiple model providers, temperature control, and a fallback mechanism to ensure reliability.

Usage cost: 1 credit

### Configuration

#### Settings

1. **Model Selection**
   * Primary Model\*: Select the main LLM model
   * Fallback Model: Optional backup model if primary fails
   * Temperature (0-1): Controls response randomness and creativity
     * Lower values (closer to 0): More focused, deterministic responses
     * Higher values (closer to 1): More creative, varied responses
2. **Prompts**
   * System Prompt: Instructions/context for the model's behavior
   * User Prompt: The main input to be processed
   * Past Message History: Optional chat history for context
3. **Output format**
   * **Output as JSON** (Toggle):
     * **Off (Default):** The node outputs the model's response as a plain string.
     * **On:** Instructs the model to format its response as JSON and attempts to parse the output string. If parsing succeeds, the `response` output port will contain a JSON object/array. If it fails, `response` will contain the original string.

*Note:* JSON structure and parsing success depend heavily on the model's ability to follow instructions. Clearly prompting for JSON format is recommended when this is enabled.

#### Output Ports

* `response` (string): The model's generated response

### Best Practices

1. **Model Selection**
   * Choose models based on your specific needs (cost, speed, capabilities)
   * Always configure a fallback model for critical flows
2. **Temperature Settings**
   * Use lower temperatures (0.1-0.3) for:
     * Factual responses
     * Structured output
     * Consistent results
   * Use higher temperatures (0.6-0.9) for:
     * Creative writing
     * Brainstorming
     * Conversational responses
3. **Prompt Engineering**
   * Keep system prompts clear and specific
   * Use variables in prompts to make them dynamic
   * Include relevant context in the prompt
   * Structure prompts with clear input/output expectations
4. **Message History**
   * Consider memory limitations of the model
   * Clean or truncate long conversation histories
5. **Using JSON Output**
   * Enable 'Output as JSON' when structured data is needed for downstream nodes or the final workflow output.
   * Instruct the model clearly in the prompt (User or System) to output *only* valid JSON. Specifying the exact desired keys and structure enhances reliability (e.g., "Respond ONLY with a valid JSON object containing 'name' (string) and 'items' (array of strings). Do not include any other text.").
   * Lower temperatures often improve the reliability of JSON generation.

### Common Issues

* High temperature settings may lead to inconsistent outputs
* Missing or poorly formatted system prompts can result in unexpected responses
* Token limits may be exceeded with long prompts or chat histories
* Rate limiting may affect response times
* JSON Output Failures: Even when requested, the model might produce invalid JSON, include explanatory text around the JSON, or fail to follow formatting instructions.


# Multimodal LLM Node

### Overview&#x20;

The Multimodal LLM Node enables your flow to process and analyze both text and images using Large Language Models with multimodal capabilities. This node can handle complex tasks such as image description, visual question answering, and combined text-image analysis, making it ideal for applications that require understanding of both visual and textual content.

Usage cost: 1 credit

### Configuration Settings

1. **Model Selection**
   * Primary Model\*: Select the main multimodal LLM model
   * Fallback Model: Optional backup model if primary fails
   * Temperature (0-1): Controls response randomness and creativity
     * Lower values (closer to 0): More focused, deterministic responses
     * Higher values (closer to 1): More creative, varied responses
2. **Prompts**
   * System Prompt: Instructions/context for the model's behavior
   * Prompt\*: The main instruction or question for the model
   * Images\*: One or more image inputs for visual analysis
   * Past Message History: Optional chat history for context
3. **Output format**

   * **Output as JSON** (Toggle):
     * **Off (Default):** The node outputs the model's response as a plain string.
     * **On:** Instructs the model to format its response as JSON and attempts to parse the output string. If parsing succeeds, the `response` output port will contain a JSON object/array. If it fails, `response` will contain the original string.

   *Note:* JSON structure and parsing success depend heavily on the model's ability to follow instructions. Clearly prompting for JSON format is recommended when this is enabled.

### Output Ports

* `response` (string): The model's generated response based on both text and image inputs

### Best Practices

1. **Model Selection**
   * Choose models that support multimodal processing
   * Ensure fallback models also have multimodal capabilities
   * Consider model-specific limitations for image processing
2. **Image Handling**
   * Provide clear, high-quality images
   * Use appropriate image formats supported by the model
3. **Prompt Engineering**
   * Be specific about what aspects of the images to analyze
   * Structure prompts to guide the model's attention
   * Include clear instructions for combining text and image analysis
   * Examples:
     * "Describe the main elements in this image and their relationship"
     * "Compare these two images and explain the differences"
     * "Based on the image and context, answer the following question..."
4. **Temperature Settings**
   * Use lower temperatures (0.1-0.3) for:
     * Factual image descriptions
     * Technical analysis
     * Precise measurements or details
   * Use higher temperatures (0.6-0.9) for:
     * Creative interpretations
     * Brainstorming based on visual inputs
     * Generating varied descriptions
5. **Performance Optimization**
   * Optimize image sizes before processing
   * Limit the number of images per request
   * Consider token limitations when combining images and text

### Common Issues

* Image processing timeouts with large or complex images
* Token limit exceeded when processing multiple images
* Inconsistent responses with high temperature settings


# Dall-E 2 (image generation) Node

### Overview&#x20;

The DALL-E 2 Node enables your flow to generate images using **OpenAI's** DALL-E 2 model. This node transforms text descriptions into high-quality images, making it ideal for applications requiring automated image generation, creative content production, or visual asset creation.

Usage cost: 2 credits

### Configuration Settings

1. **Model Selection**
   * Model\*: Select OpenAI's DALL-E 2 model from available providers
   * Note: Only OpenAI provider is supported for DALL-E 2
2. **Image Generation**
   * Prompt\*: Text description of the image to generate
   * Image Size\*: Select output resolution
     * 256x256: Small size, faster generation
     * 512x512: Medium size, balanced option
     * 1024x1024: Large size, highest detail

### Outputs

* `image` (Image): Generated image object for use in subsequent nodes
* `base64_image` (string): Base64-encoded image data

### Best Practices

1. **Prompt Engineering**
   * Be specific and detailed in descriptions
   * Include key visual elements:
     * Style (e.g., "photorealistic", "oil painting", "3D render")
     * Composition (e.g., "close-up", "wide angle", "overhead view")
     * Lighting (e.g., "bright", "moody", "natural lighting")
     * Colors (e.g., "vibrant", "pastel", "monochromatic")
   * Maintain prompt clarity and coherence
2. **Size Selection**
   * Choose 256x256 for:
     * Thumbnails and previews
     * Quick iterations and testing
     * Resource-efficient generation
   * Choose 512x512 for:
     * Medium-quality assets
     * Social media content
     * Balance between quality and speed
   * Choose 1024x1024 for:
     * High-quality visuals
     * Detailed illustrations
     * Professional content

### Common Issues

* API rate limiting
* Network timeouts during image fetching


# Dall-E 3 (image generation) Node

### Overview&#x20;

The DALL-E 3 Node enables your flow to generate high-quality images using OpenAI's DALL-E 3 model. This advanced image generation node offers enhanced capabilities including better prompt interpretation, more detailed outputs, and additional customization options compared to its predecessor. The node supports both **OpenAI** and **Azure OpenAI** providers.

Usage cost: 2 credits

Configuration Settings

1. **Model Selection**
   * Model\*: Select DALL-E 3 model from available providers
   * Supported Providers:
     * OpenAI
     * Azure OpenAI
2. **Image Generation**
   * Prompt\*: Text description of the image to generate
   * Quality\*: Image quality setting
     * Standard: Regular quality, faster generation
     * HD: Higher detail and clarity, longer generation time
   * Size\*: Output resolution options
     * 1024x1024: Square format
     * 1792x1024: Landscape format
     * 1024x1792: Portrait format
   * Style\*: Image rendering style
     * Vivid: Enhanced colors and contrast
     * Natural: More photorealistic appearance

### Outputs

* `image` (Image): Generated image object for use in subsequent nodes
* `base64_image` (string): Base64-encoded image data

### Best Practices

1. **Prompt Engineering**
   * Provide detailed, clear descriptions
   * Include specific visual elements:
     * Subject matter and composition
     * Art style and medium
     * Lighting and atmosphere
     * Color palette and mood
   * Use natural language rather than keyword lists
   * Specify important details first
   * Example prompt structure:
     * "A professional photograph of \[subject] in \[setting], \[lighting], \[style]"
2. **Quality Selection**
   * Use Standard quality for:
     * Rapid prototyping
     * Draft versions
     * Cost-effective generation
   * Use HD quality for:
     * Final deliverables
     * Detailed artwork
     * Professional content
3. **Size Selection**
   * Choose 1024x1024 for:
     * Social media posts
     * Profile pictures
     * Universal compatibility
   * Choose 1792x1024 for:
     * Landscape photography
     * Banner images
     * Wide-format content
   * Choose 1024x1792 for:
     * Mobile content
     * Story formats
     * Vertical layouts
4. **Style Selection**
   * Use Vivid for:
     * Digital art
     * Marketing materials
     * Eye-catching visuals
   * Use Natural for:
     * Product photography
     * Realistic scenarios
     * Professional documentation

### Common Issues

* API rate limiting and quotas
* Generation timeouts with HD quality
* Network issues during image retrieval


# Sora video generation Node

### Overview

The Sora Video Generation Node enables your flow to create high-quality videos using OpenAI's Sora model. This cutting-edge video generation node transforms text prompts into realistic and imaginative video content, supporting various resolutions, aspect ratios, and durations. Currently, the node supports **Azure OpenAI** providers only.

**Usage cost:** 2 credits

### Configuration Settings

#### 1. **Model Selection**

* **Model**\* Select Sora model from available providers

#### 2. **Video Generation**

* **Prompt**\* Text description of the video to generate
* **Resolution**\* Video quality and pixel height
  * **480p**: Lower resolution, faster generation
  * **720p**: Standard HD quality
  * **1080p**: Full HD quality, highest detail
* **Aspect Ratio**\* Video dimensions and orientation
  * **Square (1:1)**: Equal width and height, ideal for social media
  * **Landscape (16:9)**: Widescreen format for traditional video content
  * **Portrait (9:16)**: Vertical format for mobile and social stories
* **Duration**\* Video length in seconds
  * **5 seconds**: Short clips, quick demonstrations
  * **10 seconds**: Standard short-form content
  * **15 seconds**: Extended clips with more detail
  * **20 seconds**: Longer narrative sequences

### Outputs

* `video` (Video): Generated video object for use in subsequent nodes
* `base64_video` (string): Base64-encoded video data with data URL format

### Best Practices

#### 1. **Prompt Engineering**

* Provide clear, descriptive narratives
* Include specific visual and motion elements:
  * **Subject and action**: "A person walking through a forest"
  * **Camera movement**: "Close-up shot panning left to right"
  * **Environment**: "Sunny morning with dappled light"
  * **Style and mood**: "Cinematic, warm lighting, peaceful atmosphere"
* Structure prompts for video storytelling:
  * "A \[subject] \[action] in \[environment], \[camera angle], \[lighting], \[mood]"
* Specify temporal elements:
  * Movement direction and speed
  * Scene transitions
  * Environmental changes

#### 2. **Resolution Selection**

* Use **480p** for:
  * Rapid prototyping and concept testing
  * Draft versions and previews
  * Cost-effective generation
* Use **720p** for:
  * Standard content creation
  * Social media videos
  * Balanced quality and generation time
* Use **1080p** for:
  * Professional content
  * Final deliverables
  * High-quality presentations

#### 3. **Aspect Ratio Selection**

* Choose **1:1 (Square)** for:
  * Instagram posts and feeds
  * Profile videos
  * Platform-agnostic content
* Choose **16:9 (Landscape)** for:
  * YouTube videos
  * Website headers
  * Traditional video content
* Choose **9:16 (Portrait)** for:
  * TikTok and Instagram Stories
  * Mobile-first content
  * Vertical video platforms

#### 4. **Duration Selection**

* Use **5 seconds** for:
  * Quick animations
  * Logo reveals
  * Simple demonstrations
* Use **10 seconds** for:
  * Standard social media clips
  * Product showcases
  * Brief narratives
* Use **15-20 seconds** for:
  * Complex scenes
  * Detailed storytelling
  * Multi-action sequences

#### 5. **Variable Integration**

All fields support variable interpolation for dynamic content creation.

* **Prompt**: Accepts any string value
* **Resolution**: Must resolve to `'480'`, `'720'`, or `'1080'`
* **Aspect Ratio**: Must resolve to `'1:1'`, `'16:9'`, or `'9:16'`
* **Duration**: Must resolve to `'5'`, `'10'`, `'15'`, or `'20'`

### Technical Considerations

#### **File Handling**

* Videos are returned as MP4 format
* Base64 encoding for easy integration

### Common Issues

* **Provider Limitations**: Currently only Azure OpenAI is supported; OpenAI direct API is not yet available
* **Generation Timeouts**: Complex scenes or longer durations may approach the 10-minute timeout limit
* **Network Issues**: Large video files may experience download delays
* **API Rate Limiting**: Azure OpenAI quotas may affect generation frequency

### Troubleshooting

#### **"Video generation timed out after 10 minutes"**

* Simplify the prompt to reduce complexity
* Try shorter duration settings
* Use lower resolution for faster processing

### Example Prompts

**Simple Scene:**

```
A golden retriever playing in a sunny park, close-up shot, natural lighting, joyful atmosphere
```

**Cinematic Style:**

```
A vintage car driving down a coastal highway at sunset, drone shot following from behind, warm golden hour lighting, peaceful and nostalgic mood
```

**Product Demonstration:**

```
Hands opening a sleek smartphone box on a clean white desk, overhead shot, soft studio lighting, minimalist and professional
```

**Abstract/Artistic:**

```
Colorful paint drops falling into clear water in slow motion, macro lens, high contrast lighting, mesmerizing and fluid motion
```


# Text-to-Speech (TTS) Node

### Overview

The Text-to-Speech Node enables your flow to convert text into natural-sounding speech using advanced AI models. This node supports both **OpenAI** and **Azure OpenAI** providers, making it ideal for applications requiring voice synthesis, audio content creation, or accessibility features.

Usage cost: 2 credit

### Configuration Settings

1. **Model Selection**
   * Model\*: Select from available OpenAI or Azure OpenAI TTS models
   * Note: Only OpenAI and Azure OpenAI providers are currently supported
2. **Voice Configuration**
   * Input Text\*: The text to convert to speech (supports variable interpolation)
   * Voice\*: Select from available voice options:
     * Alloy: Neutral, versatile voice
     * Echo: Deep, resonant voice
     * Fable: Warm, narrative-focused voice
     * Onyx: Authoritative, professional voice
     * Nova: Energetic, youthful voice
     * Shimmer: Clear, bright voice
3. **Audio Settings**
   * Audio Format\*: Choose output format:
     * MP3: Standard compressed audio
     * Opus: High-quality compressed format
     * AAC: Advanced Audio Coding
     * FLAC: Lossless audio compression
     * WAV: Uncompressed audio
     * PCM: Raw audio data
   * Speed: Adjust speech rate (0.25x to 4.0x, default: 1.0x)

### Outputs

* `audio` (Audio): Audio object for use in subsequent nodes
* `base64_audio` (string): Base64-encoded audio data with format prefix (e.g., "data:audio/mp3;base64,...")

### Best Practices

1. **Text Preparation**
   * Keep sentences clear and well-punctuated
   * Use appropriate breaks and pauses for natural speech flow
   * Consider phonetic spelling for complex words or names
   * Test with smaller text segments before processing long content
2. **Voice Selection**
   * Choose voices based on your content's tone and purpose:
     * Alloy: General-purpose applications
     * Echo: Narratives requiring authority
     * Fable: Storytelling and educational content
     * Onyx: Business and professional applications
     * Nova: Dynamic, engaging content
     * Shimmer: Clear instructional content
3. **Format Selection**
   * Choose MP3 for:
     * General-purpose use
     * Web streaming
     * Smaller file sizes
   * Choose FLAC or WAV for:
     * High-quality requirements
     * Professional audio production
     * Further audio processing
   * Choose Opus for:
     * Real-time applications
     * Efficient streaming
     * Low-latency requirements

### Common Issues

1. **API Limitations**
   * Rate limiting from providers
   * Maximum text length restrictions
2. **Audio Quality**
   * Format compatibility with target platforms
   * Speech clarity in complex sentences


# Speech-to-Text (STT) Node

## Speech-to-Text (STT) Node

### Overview

The Speech-to-Text Node enables your flow to convert audio into text using advanced AI models. This node supports **OpenAI**, **Azure OpenAI**, and **Groq** providers, making it ideal for applications requiring audio transcription, voice command processing, or content accessibility features.

Usage cost: 2 credits

### Configuration Settings

1. **Model Selection**
   * Model\*: Select from available OpenAI, Azure OpenAI, or Groq STT models
   * Note: Only OpenAI, Azure OpenAI, and Groq providers are currently supported
2. **Audio Input**
   * Audio File\*: Select an audio input from available audio variables
   * Supported Formats:
     * MP3 (.mp3)
     * MP4 (.mp4)
     * MPEG (.mpeg, .mpga)
     * M4A (.m4a)
     * WAV (.wav)
     * WebM (.webm)
     * FLAC (.flac)
     * OGG (.ogg, .oga)
3. **Transcription Settings**
   * Language: Optional language specification
     * Auto-detect (default)
     * 60+ supported languages including English, Spanish, French, German, etc.
   * Temperature: Controls transcription variability (0.0 to 1.0)
     * Lower values (0.0): More focused and deterministic
     * Higher values (1.0): More variety in word choice

### Outputs

* `text` (string): Transcribed text from the audio input

### Best Practices

1. **Audio Preparation**
   * Use clear, high-quality audio recordings
   * Minimize background noise and interference
   * Ensure proper audio format compatibility
   * Keep file sizes reasonable for processing
2. **Language Selection**
   * Use auto-detect for general transcription
   * Specify language for:
     * Improved accuracy with known language
     * Regional accent consideration
   * Consider target audience when selecting language
3. **Temperature Optimization**
   * Use 0.0 for:
     * Technical content
     * Legal documents
     * Precise transcriptions
   * Use higher values for:
     * Creative content
     * Casual conversations
     * Multiple interpretation scenarios
4. **Format Selection**
   * Use MP3 for:
     * General-purpose transcription
     * Balanced quality and file size
     * Wide compatibility
   * Use WAV or FLAC for:
     * High-fidelity requirements
     * Professional audio
     * Critical accuracy needs

### Common Issues

1. **File Format Issues**
   * Unsupported audio formats
   * Corrupted audio files
   * Invalid file extensions
2. **Transcription Quality**
   * Poor audio quality affecting accuracy
   * Background noise interference
   * Multiple speakers overlap
   * Heavy accents or dialects
3. **API Limitations**
   * File size restrictions
   * Rate limiting


# OCR Node

### Overview

The OCR Node empowers your flows to extract text content from PDF files and images. By leveraging either dedicated OCR APIs or multimodal Large Language Models, this node can process a variety of visual document formats. It handles single files or lists of files, providing structured text output for further analysis or integration within your AI applications.

**Usage cost:** 1 credit

### Configuration Settings

**Input Source**

* **Input Source**\*: Select a variable holding the base64 encoded data URL (or a list of such URLs) of the PDF file(s) or image(s) you want to process.
  * Accepts: `string` (single base64 data URL), `string[]` (list of base64 data URLs), `file` (single file object), `file[]` (list of file objects), `image` (single image object), `image[]` (list of image objects), `pdf` (single PDF object).
  * Behind the scenes, file, image, and PDF objects are converted to their base64 data URL representations.

**Model Selection**

* **Model**\*: Choose the AI model that will perform the Optical Character Recognition.
  * You can select from models specifically designed for OCR tasks (OCR API) or powerful Multimodal Large Language Models capable of analyzing visual content.
  * The platform will intelligently route the processing based on the selected model's capabilities.

**Pages to Process (Optional)**

* **Pages to Process**: This optional field allows you to specify which pages of a **single PDF input** should be processed.
  * Enter page numbers or ranges, using a 1-based indexing (e.g., `1`, `3-5`, `1, 3-5, 7`).
  * If left empty, all pages of the PDF will be processed.
  * This setting is **ignored** when the input source is a list of files or when the input is an image.

#### Output Ports

* **page\_documents (List\[Document])**: A list of Langchain `Document` objects. Each document corresponds to a processed page and contains the extracted text as its `page_content`, along with metadata such as the original `source` filename, the `input_index` (if a list of inputs was provided), and the `page` number (0-based index within the source).
* **full\_document (Document)**: A single Langchain `Document` containing the concatenated text from all processed pages across all input items. The metadata will reflect the details of the last processed page. This output is `None` if no pages were processed.
* **page\_texts (List\[str])**: A simple list of strings, where each string contains the extracted text from a single processed page across all input items, maintaining the order of processing.
* **full\_text (str)**: A single string containing all the extracted text concatenated together, with page breaks indicated by `\n`.
* **raw\_api\_responses (Optional\[List\[Dict\[str, Any]]])**: If an API was used for OCR, this output provides a list of the raw JSON responses received from the API for each processed input item or page. The structure of this output will vary depending on the specific API used. This will be `None` if a Multimodal LLM was used.

### Best Practices

**Model Selection**

* When choosing a model, consider the complexity and quality of your input documents. Dedicated OCR API models might be optimized for speed and accuracy on standard document layouts.
* Multimodal LLMs can be more versatile in handling complex layouts, tables, and even extracting information based on visual understanding in addition to text.
* Experiment with different models to find the best balance of performance and cost for your specific use case.

**Input Preparation**

* Ensure that the PDF files and images provided are of reasonable quality and resolution for optimal OCR results. Blurry or low-resolution images can significantly impact accuracy.
* For large PDF documents, consider processing them in smaller chunks or specifying page ranges to manage processing time and potential API limitations.

**Handling Lists of Inputs**

* When providing a list of files, the "Pages to Process" setting will be disregarded, and all compatible content within each file will be processed. If you need to process specific pages from multiple PDFs, you might need to split them into individual files or use a preceding node to handle page extraction.

#### Common Issues

* **Poor OCR accuracy:** This can often be attributed to low-quality input images or complex document layouts. Consider using higher-resolution images or experimenting with different OCR models.
* **Timeout errors:** Processing very large files or a large number of files can exceed processing time limits. Try breaking down the input into smaller chunks or optimizing the workflow.
* **Unexpected output format:** The output structure might vary slightly depending on whether an OCR API or a Multimodal LLM is used. Refer to the "Output Ports" section for detailed descriptions.


# Agent Node

### Overview

The Agent Node empowers your flow with decision-making capabilities by creating an AI agent that can use multiple tools to accomplish tasks. It combines a large language model with a set of tools, enabling complex reasoning and multi-step task completion based on the input and available tools.

Usage cost: 2 credits

### Configuration

#### Settings

1. **Model Selection**
   * LLM Model\*: Select the AI model for the agent (the selected model must support tools calling)
   * System Prompt: Initial instructions defining the agent's behavior and context
   * Agent Prompt\*: The main instruction or task for the agent
   * Past Message History: Optional chat history for context
2. **Tools Configuration**
   * Tools\*: Select one or more tools for the agent to use
   * Tools must be provided by previous nodes in the flow
3. **Output format**

   * **Output as JSON** (Toggle):
     * **Off (Default):** The node outputs the model's response as a plain string.
     * **On:** Instructs the model to format its response as JSON and attempts to parse the output string. If parsing succeeds, the `response` output port will contain a JSON object/array. If it fails, `response` will contain the original string.

   *Note:* JSON structure and parsing success depend heavily on the model's ability to follow instructions. Clearly prompting for JSON format is recommended when this is enabled.

#### Output Ports

* `response` (string): The agent's complete response after using tools and reasoning

### Best Practices

1. **Tool Selection**
   * Only provide tools that are relevant to the task
   * Order tools from most to least commonly used
   * Ensure tools have clear, descriptive names
   * Limit the number of tools to prevent confusion
2. **Prompt Engineering**
   * Be specific about what tools should be used
   * Clearly define the expected outcome
3. **Performance Optimization**
   * Keep tool descriptions concise
   * Use appropriate model for complexity
   * Balance between instruction detail and flexibility

### Common Issues

* Tool execution timeouts
* Incorrect tool selection by agent
* Incomplete or unclear tool responses
* Model context length limitations


# Reranker Node

### Overview

The Reranker Node optimizes document retrieval by reordering a set of documents based on their relevance to a specific query. It uses specialized reranking models to improve the accuracy and relevance of search results by considering semantic similarity and contextual information.

Usage cost: 1 credit

### Configuration

#### Settings

1. **Model Selection**
   * Reranker Model\*: Select the reranking model to use
   * Top K: Number of documents to return after reranking (default: 3)
   * Query\*: The search query used to rerank documents
   * Documents\*: List of documents to be reranked

#### Output Ports

* `reranked_documents` (Document\[]): Array of reranked documents ordered by relevance

### Best Practices

1. **Document Preparation**
   * Keep document segments concise and focused
   * Ensure documents contain meaningful content
   * Remove duplicate or near-duplicate content
2. **Query Optimization**
   * Use specific, targeted queries
   * Include key terms and concepts
   * Consider query expansion when needed
   * Use consistent query formatting
3. **Performance Tuning**
   * Adjust Top K based on use case requirements
   * Consider document batch size
4. **Integration Tips**
   * Place after retrieval nodes
   * Connect to document transformation nodes when needed


# Knowledge retrieval Node

### Overview

The Knowledge Retrieval Node searches and retrieves relevant documents from your knowledge collections based on a query. It supports semantic search through vector embeddings and allows filtering of results using vector store-specific filtering syntax. Each knowledge collection can be configured with different vector stores (Milvus, Qdrant, Chroma, Pinecone, ...).

Usage cost: 0.1 credit / document

### Configuration

#### Settings

1. **Collection Selection**
   * Collection\*: Select the knowledge collection to search
   * Number of Documents: Number of results to return (default: 5)
   * Query\*: Search query used to find relevant documents
   * Filtering: Optional filtering condition based on metadata

#### Output Ports

* `knowledges` (Document\[]): Retrieved documents with full metadata
* `documents_content` (string\[]): Array of document contents only

### Filtering example depending on vector store

**Milvus/Zilliz**

```sql
metadata["field"] == "value"
```

**Qdrant**

```json
{
  "must": [
    {"key": "metadata.field", "match": {"value": "exact_match"}}
  ]
}
```

**Chroma**

```json
{
  "field": {"$eq": "value"}
}
```

**Pinecone**

```json
{
  "field": {"$eq": "value"}
}
```

### Best Practices

1. **Query Construction**
   * Keep queries clear and focused
   * Include key terms relevant to desired content
   * Consider semantic meaning rather than exact keywords
   * Test queries with different phrasings
2. **Result Optimization**
   * Adjust number of documents based on use case
   * Use filtering to narrow down results, or to built multi-tenant data retrieval
   * Consider document length when setting limits
3. **Filtering Usage**
   * Follow vector store-specific syntax
   * Test filters with sample data
   * Use appropriate operators for data types

For vector store specific filter syntax, refer to:

* Milvus: [Filtering Documentation](https://milvus.io/docs/boolean.md)
* Zilliz: [Filtering Documentation](https://docs.zilliz.com/docs/filtering)
* Qdrant: [Filtering Documentation](https://qdrant.tech/documentation/concepts/filtering/)
* Chroma: [Where Filters Documentation](https://docs.trychroma.com/docs/querying-collections/metadata-filtering)
* Pinecone: [Metadata Filtering Guide](https://docs.pinecone.io/guides/data/filter-with-metadata#metadata-query-language)


# Vector store insert Node

### Overview

The Vector Store Insert Node enables the addition of documents to vector stores for semantic search and retrieval. It supports both existing collections and custom configurations, with options for smart document insertion to prevent duplicates. Documents are automatically converted into embeddings using the specified model before storage.

Usage cost: 0.2 credit / document

### Configuration

#### Settings

1. **Documents Configuration**
   * Documents to Insert\*: Select documents to add to the vector store
   * Smart Insertion: Enable to prevent duplicate documents using content-based IDs (the generated ID is a 32 characters string).
2. **Storage Configuration**

   * Mode Selection:
     * Use Existing Collection: Insert into a pre-configured collection
     * Custom Configuration: Create and insert into a new collection

   **For Existing Collection:**

   * Vector Store Collection\*: Select target collection

   **For Custom Configuration:**

   * Knowledge Source\*: Select vector store provider
   * Embeddings Model\*: Choose model for document embedding
   * Collection Name\*: Define name for new collection

#### Output Ports

* `affected_ids` (string\[]): IDs of documents successfully inserted

### Best Practices

1. **Document Preparation**
   * Format documents consistently
   * Clean and preprocess text before insertion
2. **Collection Management**
   * Use descriptive collection names
   * Plan collection structure beforehand
   * Consider using smart insertion for production
3. **Vector Store Considerations**
   * Milvus/Zilliz: Supports automatic collection creation
   * Chroma: Supports automatic collection creation
   * Pinecone: Requires manual collection setup
   * Qdrant: Requires manual collection setup

### Common Issues

* Document format mismatches
* Embedding model rate limits
* Vector store connection issues
* Large batch processing timeouts


# Vector store record delete Node

### Overview

The Vector Store Record Delete Node enables deletion of records from a vector store collection based on specified criteria. This node supports multiple vector store providers and offers flexible deletion conditions through filtering expressions.

:warning: The pinecone vector store doesn't support record deletion based on filters on severless mode.

Usage cost: 1 credit

### Configuration

#### Settings

1. **Collection Mode**
   * Use Existing Collection: Delete from a predefined collection
   * Custom Configuration: Specify custom collection details
2. **Collection Settings** (based on mode)
   * **Existing Collection Mode:**
     * Vector Store Collection\*: Select from available collections
   * **Custom Configuration Mode:**
     * Knowledge Source\*: Select vector store provider
     * Collection Name\*: Name of the collection to delete from
3. **Deletion Configuration**
   * Deletion Condition\*: Filter expression to identify records for deletion (depends on vector store provider, see below for more informations)
   * Continue on Failure: Toggle to control flow behavior on errors

#### Output Ports

* `success` (boolean): Indicates if deletion was successful
* `error_message` (string, optional): Error details if deletion failed

### Filtering example depending on vector store

**Milvus/Zilliz**

```sql
metadata["field"] == "value"
```

**Qdrant**

```json
{
  "must": [
    {"key": "metadata.field", "match": {"value": "exact_match"}}
  ]
}
```

**Chroma**

```json
{
  "field": {"$eq": "value"}
}
```

**Pinecone**

```json
{
  "field": {"$eq": "value"}
}
```

### Best Practices

1. **Filtering Expressions**
   * Use precise conditions to avoid unintended deletions
   * Test filters on small datasets first
   * Follow vector store-specific syntax guidelines
   * Use variables for dynamic filtering
2. **Error Handling**
   * Enable "Continue on Failure" for non-critical deletions
   * Plan for partial deletion scenarios

### Common Issues

* Invalid filter syntax
* Permission-related failures
* Connection timeouts during large deletions

### Vector Store Filter Documentation

Each vector store has its own filtering syntax. Refer to the respective documentation:

For vector store specific filter syntax, refer to:

* Milvus: [Filtering Documentation](https://milvus.io/docs/boolean.md)
* Zilliz: [Filtering Documentation](https://docs.zilliz.com/docs/filtering)
* Qdrant: [Filtering Documentation](https://qdrant.tech/documentation/concepts/filtering/)
* Chroma: [Where Filters Documentation](https://docs.trychroma.com/docs/querying-collections/metadata-filtering)
* Pinecone: [Metadata Filtering Guide](https://docs.pinecone.io/guides/data/filter-with-metadata#metadata-query-language)


# Gitbook loader

### Overview

The GitBook Loader Node allows you to extract content from GitBook documentation pages. It can either load a single page or recursively load all pages from a GitBook documentation site, making it ideal for creating knowledge bases from GitBook documentation.

Usage cost: 1 credit for unique page / 10 credits for whole documentation

### Configuration

#### Settings

1. **GitBook URL**
   * URL to the GitBook documentation
   * Can be a specific page URL or root URL when loading all paths
   * Required field
   * Supports variable interpolation
2. **Load Options**
   * Load All Paths: Toggle to recursively load all pages
     * When enabled: URL must be the GitBook root
     * When disabled: Loads only the specified page

#### Output Ports

1. `documents` (List\[Document]): List of Document objects containing:
   * Page content
   * Metadata (URL, title, etc.)
2. `documents_content` (List\[string]):
   * List of extracted text content
   * Content only, without metadata

### Best Practices

1. **URL Configuration**
   * Use root URL when loading all paths
   * Ensure URLs are accessible (public documentation)
   * Verify URL format before execution
2. **Content Loading**
   * Use single page loading for specific content
   * Consider load time for large documentation sites

### Common Issues

* Rate limiting from GitBook servers
* Memory limitations with large documentation sites
* Slow loading times for recursive fetching
* Malformed URLs causing loading failures


# Notion Database Node

### Overview

The Notion Database Loader Node enables you to extract content from Notion databases. It provides capabilities to authenticate with Notion's API, select specific databases, and filter the content you want to retrieve, making it perfect for creating dynamic knowledge bases from Notion content.

Usage cost: 0.1 credit / document

### Configuration

#### Settings

1. **Authentication**
   * Integration Token\*: Notion API integration token
   * Database ID\*: Unique identifier of the target Notion database
2. **Request Configuration**
   * Request Timeout: Time limit for API requests (1-60 seconds)
   * Filter Object: JSON object defining content filtering rules
     * Must be valid JSON
     * Follows Notion's filtering syntax

#### Output Ports

1. `documents` (List\[Document]):
   * List of Document objects containing database entries
   * Includes both content and metadata
2. `documents_content` (List\[string]):
   * List of extracted text content
   * Raw content without metadata

### Best Practices

1. **Performance**
   * Use filters to limit data retrieval
2. **Integration Setup**
   * Share database with integration
   * Verify correct permissions
   * Test connection before deployment

### Common Issues

* Integration token authentication failures
* Database access permission errors
* Timeout issues with large databases
* Invalid filter object format
* Rate limiting from Notion API
* Missing database sharing settings

Note: To use this node, you need to first create a Notion integration and share your database with it. Follow the setup guide at: [How to Share Notion Databases with an Integration](https://copytonotion.com/guides/how-to-share-notion-databases-and-pages-with-an-integration)


# Figma Node

### Overview

The Figma Loader Node allows you to extract content and metadata from Figma components (nodes). It enables access to specific elements within Figma designs through node IDs, making it useful for incorporating design content and specifications into your flow.

Usage cost: 1 credit

### Configuration

#### Settings

1. **Authentication**
   * Figma Tool\*: Select a configured Figma integration
     * Must be set up in Knowledge & Tools section
     * Contains API access token
2. **File Configuration**
   * File Key\*: Unique identifier of the Figma file
     * Found in Figma file URL: `figma.com/file/{file_key}/filename`
   * Node IDs\*: Specific elements to extract
     * Comma-separated without spaces
     * Can specify multiple elements

#### Output Ports

1. `documents` (List\[Document]):
   * List of Document objects containing Figma elements
   * Includes content and metadata
   * Element properties and specifications
2. `documents_content` (List\[string]):
   * Extracted text content from elements
   * Raw content without metadata

### Best Practices

1. **File Access**
   * Ensure file sharing permissions are correct
   * Use appropriate view access levels
2. **Performance**
   * Limit number of nodes per request

### Common Issues

* Authentication token expiration
* Invalid file keys
* Incorrect node IDs
* File access permission errors


# Webpage scraper Node

### Overview

The Web Scraper Node extracts and processes content from web pages, converting HTML content into plain text in markdown format. It provides options to control how links and images are handled during the extraction process, making it versatile for various web content extraction needs.

Usage cost: 1 credit

### Configuration

#### Settings

1. **URL Configuration**
   * URL\*: Web page address to scrape
   * Supports variable interpolation
   * Must be publicly accessible
2. **Content Processing Options**
   * Ignore Links: Exclude hyperlinks from output text
   * Ignore Images: Exclude image content from output text

#### Output Ports

1. `document` (Document): Complete document object containing:
   * Page content
   * Metadata (URL, timestamps)
2. `document_content` (string):
   * Extracted text content
   * Processed according to link/image settings

### Best Practices

1. **URL Management**
   * Verify URL accessibility before execution
   * Use complete URLs including protocol (http/https)
   * Consider URL encoding for special characters
2. **Content Extraction**
   * Enable link/image ignoring for cleaner text
   * Monitor content size for large pages

### Common Issues

* JavaScript-rendered content not captured
* Malformed or invalid URLs
* Access restrictions (403 errors)
* SSL/TLS certificate issues


# Sitemap Scraper Node

### Overview

The Sitemap Scraper Node automates the extraction of content from websites by utilizing their XML sitemap. It can process both single sitemaps and nested sitemaps, with the ability to filter URLs based on specific prefixes. This makes it ideal for comprehensive website content extraction and documentation purposes.

Usage cost: 0.5 credit per scraped page

### Configuration

#### Settings

1. **Sitemap URL**\*
   * URL to the XML sitemap
   * Must include protocol (http/https)
   * Example: <https://www.example.com/sitemap.xml>
2. **Starting With**
   * Optional URL prefix filter
   * Only processes URLs beginning with this prefix
   * Example: [https://www.example.com/features/](https://www.example.com/blog/)

#### Output Ports

1. `documents` (List\[Document]): List of documents containing:
   * Processed page content
   * Source URL metadata
   * Extraction timestamps
2. `document_contents` (List\[string]):
   * List of extracted text content
   * One entry per successfully scraped page

### Best Practices

1. **URL Management**
   * Use root sitemap URL for complete site scraping
   * Employ URL filters for targeted content extraction
   * Verify sitemap accessibility before execution
2. **Resource Management**
   * Monitor processing time for large sitemaps
   * Consider memory usage with many pages
   * Use filtering to limit scope when needed

### Common Issues

* Malformed XML in sitemaps
* Rate limiting from target websites
* Memory constraints with large sites
* Invalid sitemap URLs
* Access restrictions
* Nested sitemap processing failures


# API Request Node

### Overview

The API Request Node enables integration with external services through HTTP/HTTPS requests. This node supports various request methods, authentication mechanisms, and response parsing capabilities to seamlessly connect your Gravia workflows with third-party APIs and web services.

Usage cost: 1 credit

### Configuration

#### Settings

1. **Request Configuration**
   * **Method**: HTTP method to use (GET, POST, PUT, DELETE, PATCH, HEAD, OPTIONS)
   * **URL**\*: Target endpoint for the API request
     * Supports variable interpolation (e.g., `https://api.example.com/users/{user_id}`)
     * Must include protocol (http\:// or https\://)
2. **Headers**
   * Key-value pairs for HTTP headers
   * Common examples: `Content-Type`, `Accept`, `Authorization`
   * Supports variable interpolation in both keys and values
3. **Query Parameters**
   * Key-value pairs appended to the URL
   * Automatically URL-encoded
   * Supports variable interpolation in both keys and values
4. **Request Body** (for POST, PUT, PATCH, DELETE methods)
   * **Body Format**: Determines how the request body is formatted
     * JSON: Structured data in JSON format
     * Form Data: Multipart form data
     * URL Encoded: Form data as URL-encoded string
     * Raw: Plain text content
     * Binary: Binary data
   * **Body Content**: The actual content to send
     * Supports variable interpolation
     * For JSON, must be valid JSON syntax
5. **Authentication**
   * **Authentication Type**:
     * None: No authentication
     * Basic Auth: Username/password authentication
     * API Key: Key-based authentication
     * OAuth 2.0: Token-based authentication
   * **Auth Configuration** (varies by type):
     * Basic Auth: Username and password
     * API Key: Key value, placement (header, query, body), parameter name, optional prefix
     * OAuth 2.0: Grant type, client credentials, token URLs, scopes, tokens
6. **Response Mapping**
   * Extracts data from responses into named variables
   * **Variable Name**: Name to assign to the extracted value
   * **Data Source**: Where to extract data from (body, header, status)
   * **Path Expression**: JSONPath (for JSON), XPath (for XML), or header name
   * **Response Format**: Format of the response (JSON, XML, text)
   * **Default Value**: Fallback if extraction fails
7. **Advanced Settings**
   * **Timeout**: Maximum seconds to wait for response (1-300, default: 30)
   * **Follow Redirects**: Whether to automatically follow HTTP redirects
   * **Maximum Retries**: Number of retry attempts for failed requests (0-10)

### Output Ports

1. `response_body` (any): Full response body
   * Automatically parsed according to content type
   * JSON responses are converted to objects/arrays
   * XML and text responses are returned as strings
   * Binary responses are base64-encoded
2. `status_code` (int): HTTP response status code
3. `response_headers` (object): All response headers as key-value pairs
4. `error` (string, optional): Error message if request failed
5. **Custom outputs** (based on response mappings):
   * Additional outputs generated from response mapping rules
   * Types vary based on extracted content

### Best Practices

1. **URL Construction**
   * Use complete URLs including protocol (https\://)
   * Consider URL encoding special characters in path segments
   * For dynamic URLs, use variable interpolation rather than string concatenation
2. **Authentication Security**
   * Store sensitive credentials securely
   * Use OAuth 2.0 when possible for enhanced security
   * Avoid embedding credentials directly in URLs
   * Consider using environment variables for API keys
3. **Error Handling**
   * Configure reasonable timeout values based on expected response time
   * Set appropriate retry counts for mission-critical requests
   * Use response mapping default values to handle missing data gracefully
   * Check status code before processing response data
4. **Response Mapping**
   * Use descriptive variable names that indicate content
   * Create focused mappings that extract only needed data
   * Use JSONPath expressions effectively for complex JSON responses
   * Provide sensible default values for optional fields

### Common Issues

1. **Connection Problems**
   * **401/403 Errors**: Authentication credentials incorrect or missing
   * **Connection Timeout**: Target server not responding within timeout period
   * **SSL/TLS Errors**: Certificate validation issues
2. **Request Format Issues**
   * **400 Bad Request**: Malformed request syntax
   * **415 Unsupported Media Type**: Incorrect Content-Type header
   * **413 Payload Too Large**: Request body exceeds server limits
   * **JSON Parse Errors**: Invalid JSON in request body
3. **Response Handling**
   * **Path Expression Errors**: Incorrect JSONPath or XPath syntax
   * **Missing Fields**: Requested fields not present in response
   * **Type Mismatches**: Expected data type differs from actual response

### Examples

#### Basic GET Request

```
URL: https://api.example.com/users
Method: GET
Headers:
  - Accept: application/json
```

#### Authenticated POST Request with JSON Body

```
URL: https://api.example.com/data
Method: POST
Headers:
  - Content-Type: application/json
Body Format: JSON
Body Content: {"name": "Example", "value": 42}
Authentication Type: API Key
Auth Configuration:
  - Key Placement: Header
  - Parameter Name: X-API-Key
  - Key: your_api_key_here
```

#### Response Mapping Example

```
Variable Name: user_name
Data Source: Response Body
Path Expression: $.data.user.name
Response Format: JSON
Default Value: "Unknown User"
```


# Document Creation Node

### Overview

The Document Creation Node creates new document objects with custom content and metadata for use within your flow. This node is particularly valuable for generating structured documents, preparing content for vector storage, or creating formatted output with rich metadata. It supports dynamic content generation through variable interpolation in both content and metadata fields.

**Usage cost:** 0 credit

### Configuration

#### Settings

**Content Configuration**

* **Document Content**\* (text area): The main text content of the document
  * Supports variable interpolation using standard syntax
  * Can include multi-line content with formatting
  * Example: `"Customer inquiry: ${user_message}\n\nResponse: ${ai_response}"`

**Metadata Configuration**

* **Document Metadata** (dynamic fields): Custom metadata key-value pairs
  * **Add Metadata** button to create new metadata fields
  * Each field has:
    * **Key** (text): Metadata field name (supports variable interpolation)
    * **Value** (text): Metadata field value (supports variable interpolation)
  * Common metadata examples:
    * `source`: Where the content originated
    * `timestamp`: When the document was created
    * `author`: Who created or processed the content
    * `tags`: Classification or categorization tags
    * `version`: Document version or iteration

### Output Ports

* `document` (Document): The created document object
  * Contains the interpolated content as the main text
  * Includes all specified metadata fields
  * Compatible with document processing and vector storage nodes

### Best Practices

#### **Content Structure**

* Use clear, well-formatted content templates for consistency
* Include relevant context and variable interpolation for dynamic content
* Consider downstream processing requirements when structuring content

#### **Metadata Design**

* Use standardized metadata field names across your application
* Include essential information like source, timestamp, and categorization
* Leverage variable interpolation for dynamic metadata values

#### **Variable Management**

* Ensure all referenced variables are available from previous nodes
* Test with various input scenarios to verify proper interpolation
* Handle potential null/missing variables gracefully in templates

#### **Document Organization**

* Create consistent document structures for similar content types
* Use metadata for searchability and filtering in downstream processes
* Consider document lifecycle and versioning in metadata design

### Common Issues

* **Variable interpolation failures** - Verify all referenced variables exist and have expected values
* **Empty metadata keys** - Ensure metadata key fields are not empty or resolve to blank values
* **Content formatting** - Check that variable interpolation produces properly formatted content
* **Metadata type consistency** - Maintain consistent data types for similar metadata fields across documents


# Field Extraction Node

### Overview

The Field Extraction Node extracts specific fields from objects, documents, or complex data structures within your flow. This node is essential for accessing nested data, array elements, or specific properties from structured inputs. It supports both simple field access and advanced dot notation for deep object traversal.

**Usage cost:** 0 credit

### Configuration

**Source Selection**

* **Source Object**\* (dropdown): Select the object or variable to extract from
  * Only variables of type object, document, or any are available
  * Shows variable type and source node for easy identification

**Extraction Configuration**

* **Extraction Mode**\* (dropdown): Method for field access
  * **Simple**: Direct field access for top-level properties
    * Use field names like `"name"`, `"email"`
    * Use numeric indices for arrays like `"0"`, `"1"`
  * **Dot Notation**: Nested access for complex structures
    * Use paths like `"user.profile.name"`, `"items.0.title"`
    * Supports mixed object/array navigation
* **Field Key/Path**\* (text): The field identifier
  * **Simple mode**: Direct field name or array index
  * **Dot notation mode**: Full path using dot separation
  * Examples: `"name"`, `"user.profile.email"`, `"items.0.metadata.source"`

**Default Handling**

* **Default Value** (text): Value returned if field is not found
  * Supports variable interpolation for dynamic defaults
  * Leave empty to return `null` when field is missing
  * Can reference other variables as fallback values

### Output Ports

* `extracted_value` (any): The extracted field value
  * Returns the actual data type of the extracted field
  * Returns default value if field doesn't exist or is null
  * Preserves original data structure (strings, numbers, objects, arrays)

### Best Practices

#### **Field Path Design**

* Verify field names are exact matches (case-sensitive)
* Use dot notation for accessing nested structures consistently
* Test extraction paths with sample data before deployment

#### **Default Value Strategy**

* Provide meaningful defaults for optional fields
* Use variable references for dynamic fallback values
* Consider downstream node requirements when setting defaults

#### **Data Type Handling**

* Remember that extracted values maintain their original data types
* Plan for different data types in downstream processing
* Use appropriate type checking in subsequent nodes

### Common Issues

* **Case sensitivity errors** - Field names must match exactly including capitalization
* **Array index out of bounds** - Verify array length before accessing specific indices
* **Nested path errors** - Check that all intermediate objects exist in the path
* **Type mismatch expectations** - Extracted values retain original data types


# Document metadata extraction Node

### Overview

The Document Metadata Field Extraction Node extracts specific metadata field from document objects within your flow. This node is particularly useful when you need to access and utilize document metadata such as source information, timestamps, or custom metadata fields that were added during document processing.

Usage cost: 0 credit

### Configuration

#### Settings

1. **Document Selection**
   * Document\*: Select the source document variable
   * Only single documents are supported (not document arrays)
2. **Field Configuration**
   * Metadata Field\*: Name of the metadata field to extract
   * Supports both standard and custom metadata fields

#### Output Ports

* `metadata_field_value` (string, optional): The extracted field value
  * Returns `null` if the field doesn't exist
  * Always converts the value to string format

### Best Practices

1. **Field Selection**
   * Verify field names are exact matches
   * Consider case sensitivity
   * Use consistent metadata field naming across your flow

### Common Issues

* Field name mismatches
* Missing metadata fields
* Unexpected metadata value types


# Document metadata update Node

### Overview

The Document Metadata Update Node allows you to modify or add metadata fields to existing documents in your flow. It provides flexibility in updating document metadata either by merging with existing metadata or completely reinitializing it with new values.

Usage cost: 0 credit

### Configuration

#### Settings

1. **Document Selection**
   * Document\*: Select the source document to update
   * Only single documents are supported (not document arrays)
2. **Metadata Configuration**
   * Metadata Fields\*: JSON object containing the metadata fields to update
   * Reinitialize: Toggle to clear existing metadata before applying new fields
     * When enabled: Replaces all existing metadata
     * When disabled: Merges new fields with existing metadata

#### Output Ports

* `document` (Document): Updated document with new metadata
  * Contains the original document content
  * Updated metadata based on configuration

### Best Practices

1. **JSON Structure**
   * Use valid JSON format for metadata fields
   * Use double quotes for keys and string values
   * Structure nested data appropriately
2. **Metadata Management**
   * Document metadata schema changes
   * Use consistent field names
   * Consider data types when updating

### Common Issues

* Invalid JSON syntax in metadata fields
* Missing required metadata fields
* Inconsistent field naming
* Special characters in JSON
* Nested object handling


# Concatenation Node

### Overview

The Concatenation Node creates strings by combining text templates with variables from your flow. This node is particularly useful for formatting output messages, creating dynamic content, or combining multiple data sources into a single text output. It supports flexible variable insertion with customizable array formatting and robust error handling for missing variables.

**Usage cost:** 0 credit

### Configuration

#### Settings

**Template Configuration**

* **Template**\* (text area): The text template where you can insert variables
  * Use the variable insertion interface to add variables from previous nodes
  * Supports multi-line templates for complex formatting
  * Variables are inserted visually and automatically formatted
  * Example: `"Title: {inserted_title_variable}, Body: {inserted_content_variable}"`

**Array Formatting**

* **Array Separator** (text): Custom separator for array variables
  * Used when an inserted variable resolves to an array/list
  * Common examples: `", "` (comma space), `" | "` (pipe), `"\n"` (new line)
  * Leave empty to use default array formatting

**Error Handling**

* **Handle Missing Variables**\* (dropdown): Strategy for missing or null variables
  * **Error**: Stop execution and throw an error if variable not found
  * **Empty**: Replace missing variables with empty string
  * **Skip**: Keep original variable reference in output for missing variables

### Output Ports

* `result` (string): The concatenated string result
  * All inserted variables are replaced with their actual values
  * Arrays are formatted using the specified separator
  * Missing variables are handled according to the selected strategy

### Common Issues

* **Variable availability** - Ensure selected variables come from nodes that execute before this concatenation node
* **Unexpected array formatting** - Verify array separator settings when working with list variables
* **Template structure** - Check that your template creates the intended output format
* **Missing variable handling** - Review error handling strategy if execution stops unexpectedly


# Substring Extraction Node

### Overview

The Substring Extraction Node extracts a portion of text from a source string using start and end position indices. This node is particularly useful for parsing structured text, extracting specific segments from larger content, or processing text data where you need only a particular section. It supports both positive and negative indexing with robust boundary handling.

**Usage cost:** 0 credit

### Configuration

#### Settings

**Source Configuration**

* **Source Text**\* (text area): The text from which to extract a substring
  * Use the variable insertion interface to reference text from other nodes
  * Supports multi-line text input
  * Variables are automatically interpolated during execution

**Position Configuration**

* **Start Index** (number): Starting position for substring extraction
  * Uses 0-based indexing (first character is position 0)
  * Negative values count from the end of the string
  * Default: `0` (beginning of string)
  * Examples:
    * `0`: Start from beginning
    * `5`: Start from 6th character
    * `-3`: Start 3 characters from end
* **End Index** (number): Ending position for substring extraction
  * Position is exclusive (character at end index is not included)
  * Use `-1` to extract to the end of the string
  * Negative values count from the end of the string
  * Default: `-1` (end of string)
  * Examples:
    * `-1`: Extract to end of string
    * `10`: Extract up to (but not including) 10th character
    * `-2`: Extract until 2 characters from end

### Output Ports

* `substring` (string): The extracted portion of the source text
  * Returns empty string if start index is greater than end index
  * Automatically handles out-of-bounds indices by clamping to valid ranges
  * Preserves original character encoding and formatting

### Best Practices

#### **Index Selection**

* Remember that indexing is 0-based (first character is at position 0)
* Use negative indices for extracting from the end of strings
* Test with sample data to verify correct positioning
* Consider string length variations when setting fixed indices

#### **Variable Integration**

* Use variables from previous nodes to make extraction dynamic
* Ensure source text variables are available when the node executes
* Test with different text lengths to verify robust extraction

#### **Boundary Handling**

* The node automatically handles out-of-bounds indices safely
* Start indices beyond string length will return empty results
* End indices beyond string length will extract to actual string end

#### **Common Patterns**

* **First N characters**: Start: `0`, End: `N`
* **Last N characters**: Start: `-N`, End: `-1`
* **Skip first N characters**: Start: `N`, End: `-1`
* **Remove last N characters**: Start: `0`, End: `-N`

### Common Issues

* **Empty results** - Check that start index is not greater than end index
* **Unexpected boundaries** - Verify indices are within expected string length ranges
* **Variable interpolation** - Ensure source text variables contain string data
* **Index confusion** - Remember that end index is exclusive (not included in result)


# Character splitter Node

### Overview

The Character Splitter Node splits text or documents into smaller chunks using a recursive character-based approach. It's particularly useful for preparing text for LLMs that have token limits or when you need to process long documents in smaller segments.

Usage cost: 1 credit

### Configuration

#### Settings

1. **Chunk Configuration**
   * Chunk Size\*: Number of characters per chunk
   * Chunk Overlap\*: Number of overlapping characters between chunks
   * Separators: List of strings that define where to split the text (comma-separated)
2. **Input Selection**
   * Documents/Text to Split\*: Select one or more inputs to process
   * Supports:
     * Single text strings
     * Document objects
     * Arrays of text strings
     * Arrays of documents

#### Output Ports

* `split_documents` (Document\[]): Array of split documents
  * Each document maintains original metadata
  * Chunks respect natural text boundaries based on separators

### Best Practices

1. **Chunk Size Selection**
   * Consider model token limits
   * Balance information density
   * Account for desired context window
   * Test with representative content
2. **Overlap Configuration**
   * Use overlap to maintain context
   * Consider semantic boundaries
   * Avoid too large overlaps (waste)
3. **Separator Usage**
   * Use natural text boundaries
   * Consider document structure
   * Common separators: "\n\n", "\n", ".", "!", "?"
   * Order separators from specific to general

### Common Issues

* Memory issues with large documents
* Inconsistent chunk sizes
* Improper handling of special characters


# HTML splitter Node

### Overview

The HTML Splitter Node divides HTML content into segments based on header tags (h1, h2, etc.). It's particularly useful for structuring content hierarchically and maintaining the semantic relationship between different sections of HTML documents.

Usage cost: 1 credit

### Configuration

#### Settings

1. **Documents Selection**
   * Documents to Split\*: Select input content to process
   * Supports:
     * HTML strings
     * Document objects with HTML content
     * Arrays of HTML content
2. **Header Configuration**
   * Headers to Split On: Define header tags and their metadata keys
     * Header Tag: HTML tag to split on (e.g., h1, h2)
     * Metadata Key: Key used to store header content (e.g. Header 1, Header 2)
   * Return Each Element: Toggle to control output granularity
     * When enabled: Returns each element with associated headers
     * When disabled: Groups content between headers

#### Output Ports

* `split_documents` (Document\[]): Array of split documents
  * Each document contains the content between headers
  * Metadata includes hierarchical header information
  * Maintains original document metadata

### Best Practices

1. **Header Selection**
   * Choose appropriate header levels
   * Maintain logical hierarchy
   * Use consistent header structure
2. **Metadata Keys**
   * Use descriptive key names
   * Follow consistent naming convention
   * Consider hierarchical relationships

### Common Issues

* Inconsistent HTML structure
* Missing header tags
* Invalid HTML formatting


# Markdown Splitter

### Overview

The Markdown Splitter Node divides Markdown content into segments based on header levels. It enables structured splitting of Markdown documents while preserving the hierarchical relationship between sections, making it ideal for processing documentation, articles, and other Markdown-formatted content.

Usage cost: 1 credit

### Configuration

#### Settings

1. **Documents Selection**
   * Documents to Split\*: Select input content to process
   * Supports:
     * Markdown strings
     * Document objects with Markdown content
     * Arrays of Markdown content
2. **Header Configuration**
   * Headers to Split On: Define header syntax and metadata keys
     * Header Syntax: Markdown header symbols (e.g., #, ##)
     * Metadata Key: Key used to store header content (e.g., Header 1, Header 2)
3. **Processing Options**
   * Return Each Line: Split content line by line
     * When enabled: Each line becomes a separate document
     * When disabled: Groups content between headers
   * Strip Headers: Remove header syntax from content
     * When enabled: Headers removed from output content
     * When disabled: Headers preserved in content

#### Output Ports

* `split_documents` (Document\[]): Array of split documents
  * Each document contains sectioned content
  * Metadata includes header information
  * Preserves original document metadata

### Best Practices

1. **Header Definition**
   * Use consistent header levels
   * Start with highest level needed
   * Maintain logical hierarchy
   * Use clear metadata keys
2. **Content Processing**
   * Consider document structure
   * Plan metadata organization
   * Test with sample content
3. **Options Selection**
   * Use Return Each Line for granular analysis
   * Enable Strip Headers for clean content
   * Consider downstream processing needs
   * Balance granularity vs. context

### Common Issues

* Inconsistent header formatting
* Missing header levels
* Special character handling


# Calculator tool Node

### Overview

The Calculator Tool Node provides mathematical calculation capabilities to your flow, particularly useful in agent-based tasks. It enables real-time evaluation of mathematical expressions through a standardized tool interface that can be used by agent nodes.

Usage cost: 0 credit

### Configuration

This node has no configurable settings as it provides a standard calculator tool interface.

#### Output Ports

* `calculator_tool` (Tool): A tool object that can:
  * Evaluate mathematical expressions
  * Handle basic and complex calculations
  * Provide formatted results
  * Process numeric operations safely

### Best Practices

1. **Expression Formatting**
   * Use clear mathematical syntax
   * Ensure proper operator spacing
   * Group complex expressions with parentheses
   * Validate input expressions
2. **Error Handling**
   * Plan for division by zero
   * Handle invalid expressions gracefully
   * Validate numeric inputs
   * Check for calculation overflow

### Common Issues

* Syntax errors in expressions
* Floating-point precision errors
* Invalid mathematical operations
* Expression parsing failures
* Invalid function calls


# Text as tool Node

### Overview

The Text as Tool Node converts text content into a tool that can be used by agents. It's particularly useful for providing agents with static information, methodologies, or guidelines that can be referenced during task execution.

Usage cost: 0 credit

### Configuration

#### Settings

1. **Tool Identity**
   * Tool Name\*: Unique identifier for the tool (no spaces)
   * Tool Description\*: Explanation of the tool's purpose and usage
2. **Content Configuration**
   * Tool Content\*: The text content to be provided
   * Supports variables for dynamic content
   * Content is interpolated at runtime

#### Output Ports

* `text_as_tool` (Tool): A structured tool object that:
  * Returns the configured text content
  * Can be used by agent nodes
  * Maintains consistent formatting
  * Supports optional input parameters

### Best Practices

1. **Tool Naming**
   * Use descriptive, unique names
   * Avoid spaces in names
   * Follow consistent naming convention
   * Keep names concise but clear
2. **Description Writing**
   * Be specific about tool purpose
   * Include usage instructions
   * Define input expectations
   * Explain output format
3. **Content Management**
   * Structure content logically
   * Use variables where appropriate
   * Keep content focused
   * Consider agent context

### Common Issues

* Duplicate tool names
* Missing content variables
* Unclear tool descriptions
* Variable interpolation errors


# Knowledge retrieval tool Node

### Overview

The Knowledge Retrieval Tool Node creates a tool that enables agents to search and retrieve information from vector store collections. It provides semantic search capabilities with customizable filtering options and can be used to integrate knowledge bases into agent-based flows.

Usage cost: 1 credit

### Configuration

#### Settings

1. **Collection Settings**
   * Collection\*: Select the vector store collection to search
   * Number of Documents\*: Specify how many documents to retrieve (minimum 1)
2. **Tool Configuration**
   * Tool Name\*: Unique identifier for the tool (no spaces)
   * Tool Description\*: Explanation of when and how to use the tool
   * Filtering: Optional conditions to filter search results

#### Output Ports

* `retrieval_tool` (Tool): A tool object that:
  * Searches the specified collection
  * Returns relevant documents
  * Applies configured filters
  * Maintains metadata

### Best Practices

1. **Tool Configuration**
   * Use clear, descriptive tool names
   * Write comprehensive descriptions
   * Set appropriate document limits
   * Consider search context
2. **Filter Design**
   * Follow vector store syntax
   * Test filters thoroughly
   * Use variables strategically
3. **Performance**
   * Optimize document count
   * Design efficient filters

### Common Issues

* Invalid filter syntax
* Excessive document retrieval
* Filter parsing errors
* Collection connectivity issues

For vector store specific filter syntax, refer to:

* Milvus: [Filtering Documentation](https://milvus.io/docs/boolean.md)
* Zilliz: [Filtering Documentation](https://docs.zilliz.com/docs/filtering)
* Qdrant: [Filtering Documentation](https://qdrant.tech/documentation/concepts/filtering/)
* Chroma: [Where Filters Documentation](https://docs.trychroma.com/docs/querying-collections/metadata-filtering)
* Pinecone: [Metadata Filtering Guide](https://docs.pinecone.io/guides/data/filter-with-metadata#metadata-query-language)


# Conditional Node

### Overview

The Conditional Node enables you to create branching logic in your flows based on variable values. This node evaluates conditions in sequence and directs the flow through different paths depending on which condition is met first. It supports various data types and comparison operations, making it versatile for complex decision-making scenarios.

Usage cost: 1 credit

### Configuration Settings

#### Conditions

Each condition consists of:

* **Variable**: Select from available variables in your flow
* **Operator**: Choose a comparison operator based on the variable type
* **Value**: Enter the value to compare against (not required for empty/not empty checks)

#### Operator Types

Based on the variable type, different operators are available (contains, starts with, is, is not, is empty, equals, less than, ...

### Output Ports

The node provides multiple output ports:

* One port for each defined condition (IF/ELIF)
* One default port (ELSE) for when no conditions are met

#### Output Variables

* `result` (string): "true" if any condition matched, "false" if none matched
* `matched_condition_name` (string): Name of the matched condition or "Else case (default)"

### Best Practices

#### Condition Organization

1. **Order Matters**: Conditions are evaluated in sequence from top to bottom
2. **Default Case**: Always consider what should happen when no conditions are met (ELSE case)

#### Variable Selection

1. Choose variables that are guaranteed to be available when the node executes
2. Consider the variable type when planning your conditions
3. Ensure variable values will be in the expected format

#### Operator Usage

1. Use 'Is empty' and 'Is not empty' for null checks
2. For numerical comparisons, ensure values can be converted to numbers
3. When using string operations, consider case sensitivity

### Common Issues and Solutions

#### No Conditions Matching

**Problem**: Flow always goes to ELSE case **Solutions**:

* Verify variable values in debug mode
* Check condition order - first matching condition wins
* Ensure value comparisons match variable types

#### Type Mismatches

**Problem**: Conditions fail due to type mismatches **Solutions**:

* Verify variable types before comparison
* Use appropriate operators for the data type
* Convert values to correct type if needed

#### Performance Considerations

* Add conditions in order of likelihood to match (most common cases first)
* Use simple conditions when possible
* Avoid unnecessary complex string operations


# Iteration loop Node

### Overview

The Iteration Loop Node enables repetitive execution of a sequence of nodes over a collection of items. It creates an isolated execution context for each iteration, making it ideal for processing arrays of data, batch operations, or repetitive tasks.

Usage cost: 0 credit

### Configuration

#### Settings

1. **Iteration Control**
   * Iterator\*: Select array variable to iterate over
   * Maximum Iterations: Limit the number of iterations (0-10,000)
   * Output Collection: Select child node output to collect results
2. **Context Variables** Available in child nodes during iteration:
   * `current_item`: Current item being processed
   * `index`: Current iteration index (number)

#### Output Ports

* `output` (Any\[]): Array of collected outputs from iterations
  * When Output Collection is specified
  * Maintains order of iterations
  * Preserves original data types

### Best Practices

1. **Iterator Selection**
   * Verify array data structure
   * Consider data volume
2. **Performance Management**
   * Set appropriate iteration limits
   * Consider batch processing
   * Optimize child node operations
3. **Output Collection**
   * Choose relevant outputs
   * Plan data aggregation
   * Consider memory usage

### Common Issues

* Memory overflow from large collections
* Iteration limit exceeded
* Missing iterator variable


# Testing and Debugging

Effective testing and debugging are crucial for developing robust flows and workflows in Waterflai. This guide will walk you through the tools and techniques available for ensuring your AI applications perform as expected.

### Live Chat Testing

The Mini Chat feature in the Dream Builder Editor allows you to test your flow in real-time.

#### Using Mini Chat

1. **Opening Chat**: Click the "Chat" button in the top right corner of the Dream Builder.
2. **Interacting with Your Flow**: Type messages into the chat interface to test your flow's responses.
3. **Viewing Outputs**: Observe how your flow processes inputs and generates outputs.

<figure><img src="https://189411847-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGxqXoeVSKzSmLzXgA3zn%2Fuploads%2F1Qeub7tC404fhoh7n5IM%2Fimage.png?alt=media&amp;token=a8cc08f2-717b-4ba7-a7fa-f70323aae161" alt="" width="375"><figcaption><p>Chat interface for flows (Dream Builder)</p></figcaption></figure>

#### Tips for Effective Testing

* Test with a variety of inputs, including edge cases.
* Use the chat history to track conversation flow.
* Pay attention to how your flow handles unexpected inputs.

### Execution Detail Panel

The Execution Detail Panel provides in-depth information about how data flows through your nodes during testing.

#### Accessing the Execution Detail Panel

* Click on the check/cross icon, on top-right of a node in your flow after running a test to view its execution details.

<figure><img src="https://189411847-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FGxqXoeVSKzSmLzXgA3zn%2Fuploads%2FDraE6gYMQ4lJTbtefMqI%2Fimage.png?alt=media&amp;token=d6d5d5b0-7a8b-4aa5-8046-b23feed2548a" alt="" width="188"><figcaption><p>Access to Execution Detail Panel</p></figcaption></figure>

#### Understanding Execution Details

* **Input Data**: See what data was passed into the node.
* **Output Data**: View the results produced by the node.
* **Execution Time**: Check how long each node took to process.
* **Errors**: Identify any errors that occurred during execution.

#### Using Execution Details for Debugging

* Trace the flow of data through your nodes to identify where issues might be occurring.
* Compare expected vs. actual outputs at each step.
* Look for bottlenecks in processing time.

### Configuration Popover

The Configuration Popover allows you to adjust node settings on the fly for testing different scenarios.

#### Accessing the Configuration Popover

* Click on a node in your flow to open its Configuration Popover.

#### Testing Different Configurations

* Modify node parameters and immediately test the changes in Mini Chat.
* Experiment with different model settings, prompts, or knowledge bases.
* Use variable references to test how data flows between nodes.

### Common Debugging Scenarios

#### 1. Unexpected Outputs

* Check the prompts and instructions in your LLM Model and Agent nodes.
* Verify that the correct knowledge bases are being accessed in Knowledge Retrieval nodes.
* Ensure that data is being correctly passed between nodes using variable references.

#### 2. Error Messages

* Review the Execution Detail Panel for the node where the error occurred.
* Check node configurations for missing required fields or incorrect data types.
* Verify API keys and permissions for external services.

#### 3. Performance Issues

* Look for nodes with long execution times in the Execution Detail Panel.
* Consider optimizing large text inputs using Splitter nodes.
* Review your use of API calls and consider caching strategies where appropriate.

#### 4. Inconsistent Behavior

* Test your flow multiple times with the same input to check for consistency.
* Review any random elements in your flow (e.g., temperature settings in LLM nodes).
* Check for race conditions in parallel executions.

### Best Practices for Testing and Debugging

1. **Incremental Testing**: Test each node or small group of nodes before adding complexity.
2. **Use Descriptive Node Labels**: Clear labels make it easier to understand the flow during debugging.
3. **Comment Your Flow**: Add comments to complex sections to aid in troubleshooting.
4. **Version Control**: Save versions of your flow as you make significant changes.

By leveraging these testing and debugging tools and techniques, you can ensure that your Waterflai flows are robust, efficient, and produce the expected results. Remember that testing is an iterative process, and regular debugging will help you refine and improve your AI applications over time.


# Publishing

Publishing in Waterflai is the process of making your chatbot or workflow available for use in production environments (API, or Chat interface). This page guides you through the publishing process and explains the various integration options available after publication.

### Publishing Your Chatbot

There are two main ways to publish your chatbot in Waterflai:

1. **Save and Publish**:
   * When editing your chatbot configuration, use the "Save and Publish" option from the dropdown menu next to the "Save" button.
   * This action saves your current configuration and immediately makes it live.
2. **Publish from Chatbot List**:
   * In the Studio page, find your chatbot in the list.
   * Click the three-dot menu (⋮) on the chatbot card.
   * Select "Publish" from the dropdown menu.

> **Note**: Publishing creates a new version of your chatbot. Previous versions are retained, allowing you to roll back if needed.

### Best Practices for Publishing

1. **Testing**: Thoroughly test your chatbot in the live experimentation environment before publishing.
2. **Version Control**: Keep track of your chatbot versions.
3. **Monitor Performance**: Use Waterflai's analytics tools to monitor your chatbot's performance after publishing.
4. **Update Regularly**: Regularly review and update your published chatbots to improve their effectiveness over time.

### Managing Published Chatbots

* You can edit a published chatbot at any time. Changes will not affect the live version until you publish again.
* :warning: Deleting a chatbot will remove all its published versions and make it unavailable for use. Exercise caution when deleting.


# Integration with API

## Waterflai API Documentation

This comprehensive guide explains how to integrate your Waterflai chatbots with external applications using our API. You'll learn how to manage API keys, understand different endpoints for synchronous and asynchronous execution, handle various content types, and implement best practices for a robust integration.

For a complete technical specification of all schemas and endpoints, please refer to our [OpenAPI Reference Documentation](/api-reference/openai-compatible).

### API Overview

Waterflai provides different API endpoints based on your chatbot type and desired execution mode:

* **Simple Chatbots**: An OpenAI-compatible endpoint for basic, non-flow-based chat interactions.
* **Dream Builder (Chatflows)**: Specialized endpoints for executing complex conversational flows.
* **Workflow Builder**: Dedicated endpoints for running automated, multi-step workflows.

You can execute your chatbots in two ways:

* **Synchronous Execution**: For quick-running flows where you need an immediate response. The API holds the connection open and returns the final result in a single request. Streaming is available for real-time progress updates.
* **Asynchronous Execution**: For long-running tasks that might exceed standard timeout limits. The API immediately confirms the request and provides an ID to track the job's progress separately.

### Managing API Keys

API keys are essential for authenticating your requests. All API calls must include your key in the `X-API-Key` header.

#### Viewing API Keys

1. In the Studio page, click the **"API Keys"** button.
2. A modal will open, displaying a list of your existing API keys.
3. Each key shows its name and the actual key value.

#### Creating a New API Key

1. Click the **"API Keys"** button, then select **"New API Key"** from the dropdown.
2. In the **Create API Key** modal, enter a descriptive name for your new key.
3. Click **"Create API Key"**.
4. The new key will be displayed. **Copy it immediately**, as you won't be able to see the full key again for security reasons.

**Important**: Store your API key securely. It won't be displayed again after you close the modal.

#### Deleting an API Key

1. In the API Keys list, click the trash icon next to the key you want to delete.
2. Confirm the deletion in the popup.

**Note**: Deleting an API key will immediately and permanently revoke access for any applications using that key.

### API Endpoints

#### 1. Simple Chatbots (OpenAI Compatible)

This endpoint provides a drop-in replacement for the OpenAI Chat Completions API, designed specifically for **Simple Chatbots**.

* **Endpoint**: `POST /v1/chat/completions`
* **Purpose**: Interact with a Simple Chatbot. Supports both streaming and non-streaming responses.
* **Headers**:
  * `X-API-Key`: `YOUR_API_KEY_HERE`
  * `Content-Type`: `application/json`
* **Request Body**:

  ```
  {
    "model": "YOUR_SIMPLE_CHATBOT_ID",
    "messages": [
      {
        "role": "user",
        "content": "Hello! Can you help me today?"
      }
    ],
    "stream": false
  }

  ```
* **Response Format**:

  ```
  {
    "id": "chatcmpl-123",
    "object": "chat.completion",
    "created": 1677652288,
    "model": "YOUR_SIMPLE_CHATBOT_ID",
    "choices": [
      {
        "index": 0,
        "message": {
          "role": "assistant",
          "content": "Of course! How can I assist you?"
        },
        "finish_reason": "stop"
      }
    ],
    "usage": {
      "prompt_tokens": 10,
      "completion_tokens": 9,
      "total_tokens": 19
    }
  }

  ```

#### 2. Synchronous Execution: Dream Builder (Chatflow)

**Execute Chatflow**

* **Endpoint**: `POST /execute_chatflow/{chatflow_id}/execute`
* **Purpose**: Execute a chatflow and receive the complete response.
* **Headers**:
  * `X-API-Key`: `YOUR_API_KEY_HERE`
  * `Content-Type`: `application/json`
* **Request Body (Option 1: String Message)**:

  ```
  {
    "input_data": {
      "query": "Your message here",
      "custom_input": "..."
    }
  }
  ```
* **Request Body (Option 2: List of Messages)**:

  ```
  {
    "input_data": {
      "query": [
        {
          "role": "assistant",
          "content": "Initial message from the assistant"
        },
        {
          "role": "user",
          "content": "User message here"
        }
      ],
      "custom_input": "..."
    }
  }
  ```
* **Response Format**:

  ```
  {
    "model": "chatflow_id",
    "choices": [
      {
        "index": 0,
        "message": {
          "role": "assistant",
          "content": "Response content"
        }
      }
    ],
    "usage": {
      "prompt_tokens": 0,
      "completion_tokens": 0,
      "total_tokens": 0
    }
  }
  ```

**Stream Execute Chatflow**

* **Endpoint**: `POST /execute_chatflow/{chatflow_id}/stream_execute`
* **Purpose**: Execute a chatflow with real-time streaming updates (adequate for long-time execution flows).
* **Headers**: Same as non-streaming endpoint.
* **Request Body**: Same as non-streaming endpoint.
* **Response**: A Server-Sent Events (SSE) stream with the following events:

  ```
  {
    "type": "execution_started",
    "timestamp": "2025-02-11T14:34:08.678088"
  }

  {
    "type": "node_started",
    "node_id": "inputNodeType-19d7",
    "node_label": "Input",
    "node_type": "inputNodeType",
    "timestamp": "2025-02-11T14:34:08.681607"
  }

  {
    "type": "node_completed",
    "node_id": "inputNodeType-19d7",
    "node_label": "Input",
    "node_type": "inputNodeType",
    "timestamp": "2025-02-11T14:34:08.687736"
  }

  {
    "type": "execution_completed",
    "final_output": {
      "query": "Hello.",
      "response": "Response content"
    }
  }
  ```

#### 3. Synchronous Execution: Workflow Builder

**Execute Workflow**

* **Endpoint**: `POST /execute_workflow/{workflow_id}/execute`
* **Purpose**: Execute a workflow and receive the complete response.
* **Request Body**: The request body format is the same as the Chatflow `execute` endpoint.
* **Response**: A detailed JSON object containing the workflow execution results.

**Stream Execute Workflow**

* **Endpoint**: `POST /execute_workflow/{workflow_id}/stream_execute`
* **Purpose**: Execute a workflow with streaming updates.
* **Response**: An SSE stream with execution updates, similar to the Chatflow streaming endpoint.

#### 4. Asynchronous Execution (For Long-Running Tasks)

**Pro Tip:** For complex flows that may take a long time to complete, always use the asynchronous endpoints to avoid client-side timeouts.

* **Start Execution**: `POST /v1/executions/{chatbot_id}/async`
* **Get Status**: `GET /v1/executions/{execution_id}`
* **Stream Progress**: `GET /v1/executions/{execution_id}/stream`
* **Cancel Execution**: `DELETE /v1/executions/{execution_id}`

### Content Types and Message Handling

#### Text Messages

For simple text messages, use a string directly:

```
{
  "role": "user",
  "content": "Hello, how can you help me today?"
}
```

#### Image Messages

For messages containing images, use the multimodal content format with base64-encoded images:

```
{
  "role": "user",
  "content": [
    {
      "type": "text",
      "text": "What can you tell me about this image?"
    },
    {
      "type": "image_url",
      "image_url": {
        "data": "data:image/jpeg;filename=photo.jpg;base64,/9j/4AAQSkZJRg..."
      }
    }
  ]
}
```

#### Mixed Content Messages

You can combine multiple content types in a single message:

```
{
  "role": "user",
  "content": [
    {
      "type": "text",
      "text": "I found these two diagrams. Can you compare them?"
    },
    {
      "type": "image_url",
      "image_url": {
        "data": "data:image/png;filename=diagram1.png;base64,iVBORw0KGgoAAAANSU..."
      }
    },
    {
      "type": "image_url",
      "image_url": {
        "data": "data:image/png;filename=diagram2.png;base64,iVBORw0KGgoAAAANSU..."
      }
    }
  ]
}
```

### File Handling

#### Text Files (PDF, PPTX, etc.)

Upload text files using base64-encoded data with metadata: `data:[MIME type];filename=[filename];base64,[encoded content]`

Examples:

```
# For PDF files
data:application/pdf;filename=document.pdf;base64,JVBERi0xLjcKCjEgMCBvYmo...

# For PPTX
data:application/vnd.openxmlformats-officedocument.presentationml.presentation;filename=document.pptx;base64,UEsDBBQABgA...
```

#### Image Files

Two options for image files:

1. **Base64-encoded data**: `data:image/jpeg;filename=photo.jpg;base64,/9j/4AAQSkZJRg...`
2. **Direct URL**:

   ```
   {
     "type": "image_url",
     "image_url": {
       "url": "https://example.com/image.jpg"
     }
   }
   ```

### Code Examples

#### Python

```
import requests
import base64

api_key = 'YOUR_API_KEY_HERE'
headers = {
    'X-API-Key': f'{api_key}',
    'Content-Type': 'application/json'
}

# Regular execution
data = {
    'input_data': {
      'query': 'Hello, how are you?'
    }
}
response = requests.post(
    'https://api.waterflai.ai/execute_chatflow/CHATFLOW_ID/execute',
    json=data,
    headers=headers
)
print(response.json()['choices'][0]['message']['content'])

# Streaming execution
def handle_stream():
    response = requests.post(
        'https://api.waterflai.ai/execute_chatflow/CHATFLOW_ID/stream_execute',
        json=data,
        headers=headers,
        stream=True
    )
    for line in response.iter_lines():
        if line:
            print(line.decode('utf-8'))

# File handling
def convert_file_to_base64(file_path):
    with open(file_path, 'rb') as file:
        return base64.b64encode(file.read()).decode('utf-8')
```

#### JavaScript

```
// Regular execution
const response = await fetch('https://api.waterflai.ai/execute_chatflow/CHATFLOW_ID/execute', {
  method: 'POST',
  headers: {
    'X-API-Key': 'YOUR_API_KEY_HERE',
    'Content-Type': 'application/json'
  },
  body: JSON.stringify({
    input_data: { query: 'Hello, how are you?' }
  })
});
const data = await response.json();
console.log(data.choices[0].message.content);

// Streaming execution (Conceptual for browser, requires backend proxy)
const eventSource = new EventSource('https://api.waterflai.ai/execute_chatflow/CHATFLOW_ID/stream_execute'
  // Note: Standard EventSource does not support custom headers or POST.
);
eventSource.onmessage = (event) => {
  const data = JSON.parse(event.data);
  console.log(data);
};

// File handling helper
const convertFileToBase64 = (file) => {
  return new Promise((resolve, reject) => {
    const reader = new FileReader();
    reader.onload = () => {
      if (typeof reader.result === 'string') {
        if (file.type.startsWith('image/')) {
          resolve(`data:${file.type};base64,${reader.result.split(',')[1]}`);
        } else {
          resolve(`data:${file.type};filename=${file.name};base64,${reader.result.split(',')[1]}`);
        }
      } else {
        reject(new Error('Failed to convert file to base64'));
      }
    };
    reader.onerror = reject;
    reader.readAsDataURL(file);
  });
};
```

### Best Practices

* **Security**: Store API keys securely and never expose them in client-side code. Regularly rotate API keys.
* **Performance**: Use streaming endpoints for real-time updates and asynchronous endpoints for long-duration flows to avoid timeout errors.
* **Error Handling**: Implement proper timeout handling and retry logic for transient network errors.

### Troubleshooting

* **Authentication Errors**: Verify API key is valid and active. Check `X-API-Key` header format.
* **Request Format Errors**: Validate JSON structure. Ensure required fields are present.
* **File Upload Issues**: Check file format support. Ensure proper base64 encoding.


# Embedding in website

This guide explains how to embed your Waterflai chatbots directly into your website using our custom web component. This allows your users to interact with your chatbot without leaving your site.

### Prerequisites

Before you begin, ensure you have:

1. A published Waterflai chatbot (Simple or Chatflow type)
2. An API key for authentication (see the "Integration with API" guide for details on creating API keys)

### Embedding Process

#### Step 1: Access the Embedding Guide

1. In the Studio page, find your chatbot in the list.
2. Click the globe icon on your chatbot card to open the Embedding Guide modal.

#### Step 2: Copy the Embedding Code

In the Embedding Guide modal, you'll see a code snippet similar to this:

```html
<body>
    <div class="container">
        <h1>Waterflai Simple Chatbot Integration</h1>
    </div>

    <!-- Include the Waterflai Chatbot web component -->
    <script src="https://app.waterflai.ai/web_components/waterflai-chat-web-component.js"></script>

    <!-- Initialize the chatbot with settings -->
    <waterflai-chatbot 
        id="myWaterflaiChatbot"
        chatbot-id="YOUR_CHATBOT_ID"
        api-key="YOUR_API_KEY"
        api-url="https://api.waterflai.ai"
        chatbot-type="simple"
        welcome-message="Welcome! How can I assist you today?"
        header-title="Chat with us"
        input-placeholder="Type your message..."
        primary-color="#6366f1"
        stream-response>
    </waterflai-chatbot>
</body>
```

Click the copy button in the top-right corner of the code block to copy this code to your clipboard.

#### Step 3: Choose Your Display Mode

The chatbot can be displayed in two modes:

Widget Mode (Default)

The chatbot appears as a floating button that expands into a chat window when clicked. This is the default mode.

```html
<waterflai-chatbot 
    chatbot-id="YOUR_CHATBOT_ID"
    api-key="YOUR_API_KEY"
    api-url="https://api.waterflai.ai"
    chatbot-type="simple"
    primary-color="#6366f1">
</waterflai-chatbot>
```

Inline Mode

The chatbot is embedded directly within your page layout. Add the `inline-mode` attribute and place the component within a container with specified dimensions:

```html
<div style="width: 100%; height: 600px;">
    <waterflai-chatbot 
        chatbot-id="YOUR_CHATBOT_ID"
        api-key="YOUR_API_KEY"
        api-url="https://api.waterflai.ai"
        chatbot-type="simple"
        primary-color="#6366f1"
        inline-mode>
    </waterflai-chatbot>
</div>
```

#### Step 4: Customize the Embedding Code

Modify the copied code as follows:

* Replace `YOUR_CHATBOT_ID` with your actual chatbot ID
* Replace `YOUR_API_KEY` with your Waterflai API key
* Adjust other attributes as needed:
  * `welcome-message`: The initial message displayed by the chatbot
  * `header-title`: The title shown in the chatbot header
  * `input-placeholder`: The placeholder text for the user input field
  * `primary-color`: The main color used in the chatbot interface (hex value)

#### Step 5: Insert the Embedding Code

Place the modified embedding code where you want the chatbot to appear on your website.

### Customization Options

The `<`waterflai`-chatbot>` component accepts several attributes for customization:

#### Required Attributes

* `chatbot-id`: The ID of your Waterflai chatbot
* `api-key`: Your Waterflai API key

#### Optional Attributes

* `api-url`: The URL of the Waterflai API (default: "<https://api.waterflai.ai>")
* `chatbot-type`: The type of your chatbot ("simple" or "chatflow")
* `welcome-message`: The initial message displayed by the chatbot
* `header-title`: The title shown in the chatbot header
* `input-placeholder`: The placeholder text for the user input field
* `primary-color`: The main color used in the chatbot interface (hex value, default: "#6366f1")
* `inline-mode`: Enable inline display mode (remove for widget mode)
* `stream-response`: (For Simple chatbots only) Enable streaming responses
* `info-message`: Custom message displayed at the bottom of the chat interface

### Display Mode Considerations

#### Widget Mode

* Appears as a floating button on your website
* Automatically adjusts position on mobile devices
* Can be opened/closed by users
* Ideal for most websites where the chat is a supplementary feature

#### Inline Mode

* Embedded directly in your page layout
* Requires a container with specified dimensions
* Always visible to users
* Perfect for dedicated chat pages or customer support sections

### Troubleshooting

If you encounter issues with your embedded chatbot:

1. Verify that you're using the correct chatbot ID and API key.
2. Check your browser's console for any error messages.
3. Ensure the Waterflai web component script is properly loaded.
4. Test your API key separately to confirm it's active and has the necessary permissions.

For more advanced customization options and detailed API documentation, visit our [Developer Portal](https://developers.gravia.io).

By following these steps, you can successfully embed your Waterflai chatbot into your website, providing an interactive AI-powered chat experience for your users.


# Analytics Overview

Welcome to the Analytics section of Waterflai's documentation. Here, you'll learn how to gain valuable insights into the performance and usage of your AI applications.

### What are Analytics in Waterflai?

Analytics in Waterflai provide you with data-driven insights about your AI applications. These tools help you understand how users interact with your chatbots and workflows, identify areas for improvement, and make informed decisions about your AI strategy.

### Scope of Analytics

It's important to understand what Waterflai's analytics currently cover:

* **Production Usage**: Analytics primarily focus on interactions that occur in external environments, such as:
  * API calls to your AI applications
  * Embedded chatbots on websites or in applications
* **Not Included**: The current analytics do not cover:
  * Tests or interactions made directly within the Waterflai platform

### What You'll Learn in This Section

* How to navigate and use the Analytics space
* Strategies for optimizing your AI applications based on analytics data

### Key Topics

* **Analytics Space**: An introduction to the dedicated area for viewing and managing your analytics.
* **Dashboards**: Learn how to interpret visual representations of your data.
* **Logs**: Understand how to access and analyze detailed logs of your AI applications' activities.

### Use Cases

Whether you're looking to:

* Improve the performance of a customer service chatbot
* Optimize a complex AI workflow
* Understand user adoption of your AI features
* Identify areas for model fine-tuning

This section will equip you with the tools and knowledge to make data-driven decisions based on real-world usage of your AI applications.

Let's begin by exploring the Analytics Space and setting up your first dashboard!


# Dashboards

The Analytics Dashboards in Waterflai provide a comprehensive view of your AI applications' performance and usage. This section will guide you through using and interpreting the various dashboards available.

### Accessing the Dashboards

1. Navigate to the Analytics section in your Waterflai workspace.
2. You'll see a tabbed interface with different dashboard views: Overview, User Engagement, Performance, and Logs.

### Best Practices

1. Regularly review all dashboard views to get a comprehensive understanding of your AI applications' performance.
2. Use the date range selector to compare performance across different time periods.
3. Pay attention to sudden changes in metrics, as they may indicate issues that need addressing.
4. Use the insights gained from these dashboards to guide optimization efforts and resource allocation.

By effectively using these dashboards, you can ensure your AI applications are performing optimally and meeting user needs.


# Logs

The Logs section in Waterflai's Analytics provides detailed information about individual AI model calls and interactions. This powerful tool allows you to dive deep into the specifics of your AI applications' operations.

### Accessing the Logs

1. Navigate to the Analytics section in your Waterflai workspace.
2. Select the "Logs" tab from the tabbed interface.

### Using the Logs Interface

#### Date Range Selection

Use the Date Range Picker at the top of the Analytics page to select the time period for which you want to view logs. The logs view will update to show entries within the selected range.

#### Log Entries

Each log entry typically includes:

* Timestamp: When the AI model call or interaction occurred.
* User ID: Identifier for the user who initiated the interaction (if applicable).
* Model: The specific AI model used for the interaction.
* Input: A snippet or summary of the input provided to the AI model.
* Output: A snippet or summary of the AI model's response.
* Response Time: How long the AI model took to generate a response.
* Status: Whether the interaction was successful or if there was an error.

#### Filtering and Searching

The Logs interface likely includes options to filter and search log entries. Common filter options might include:

* Status (e.g., successful, error)
* Model type
* Response time range

Use the search functionality to look for specific terms in inputs or outputs.

### Interpreting Log Data

* Look for patterns in errors or unusually long response times.
* Identify frequently used inputs or types of queries.
* Monitor the usage of different AI models within your applications.
* Track specific user interactions if troubleshooting user-reported issues.

### Use Cases for Logs

1. **Troubleshooting**: Investigate specific errors or issues reported by users.
2. **Performance Optimization**: Identify slow-performing queries or models.
3. **Usage Analysis**: Understand how users are interacting with your AI applications in detail.
4. **Quality Assurance**: Review AI model outputs for accuracy and appropriateness.
5. **Compliance**: Maintain records of AI interactions for regulatory or internal compliance needs.

### Best Practices

1. Regularly review logs to stay aware of your AI applications' operations.
2. Use log data in conjunction with dashboard metrics for a complete picture of performance.
3. Set up alerts for critical errors or performance thresholds.
4. Ensure that your log retention policies comply with relevant data protection regulations.
5. Use insights from logs to inform model selection, prompt engineering, and application design.

### Privacy and Security Considerations

* Ensure that sensitive information is properly masked or encrypted in log entries.
* Restrict access to log data to authorized personnel only.
* Be aware of data retention laws and regulations that may apply to your log data.

By effectively using the Logs feature, you can gain deep insights into your AI applications' operations, troubleshoot issues quickly, and continuously improve your AI-driven services.


# Organization users

This page explains how to manage users within your Waterflai organization. As an administrator, you can view, add, edit, and delete users, as well as manage their roles and permissions.

### Viewing Users

The Users page displays a table of all users in your organization. Each user entry includes:

* Email address
* First name
* Last name
* Role (not visible in the table, but can be filtered)

You can use the search bar to find specific users by email address, and filter users by their role using the dropdown menu.

### Adding a New User

To add a new user to your organization:

1. Click the "New User" button at the top right of the Users table.
2. In the User Form modal:
   * Enter the user's email address
   * Select the user's role from the dropdown
   * Enter the user's first name and last name
   * Set an initial password for the user
   * Optionally, enter the user's job title
3. Click "Create" to add the user

> **Note:** After creation, the user will automatically receive an email with instructions to set up their password.

### Editing a User

To edit an existing user's information:

1. Click on the user's email in the Users table, or select "Edit" from the dropdown menu at the end of the user's row.
2. In the User Form modal, modify the user's information as needed.
3. Click "Save" to apply your changes.

### Deleting a User

To remove a user from your organization:

1. Click the three-dot menu at the end of the user's row in the Users table.
2. Select "Delete" from the dropdown menu.
3. Confirm the deletion in the confirmation dialog.

> **Caution:** Deleting a user will permanently remove their access to your Waterflai organization. This action cannot be undone.

### User Roles and Permissions

Waterflai supports different user roles to manage access and permissions within your organization. The available roles are:

* Admin: Full access to all features and settings
* Creator: Can create and manage workspaces, but cannot access organization-wide settings
* User: Basic access to use Waterflai features within assigned workspaces

When adding or editing a user, you can assign or change their role using the "Role" dropdown in the User Form modal.


# Workspace

This page explains how to manage workspaces in Waterflai. Workspaces allow you to organize your projects and control access to resources within your organization.

### Creating a Workspace

To create a new workspace:

1. Click on the workspace selector in the header.
2. Select "Create New Workspace" from the dropdown.
3. In the Workspace Modal:
   * Enter a name for your new workspace.
   * Click "Create" to finalize the workspace creation.

### Editing a Workspace

To edit an existing workspace:

1. Select the workspace you want to edit from the workspace selector.
2. Click on the workspace settings or edit icon.
3. In the Workspace Modal:
   * Modify the workspace name as needed.
   * Click "Update" to save your changes.

### Managing Workspace Members

#### Viewing Workspace Members

To view and manage the members of a workspace:

1. Select the desired workspace from the workspace selector.
2. Navigate to the workspace settings or members section.
3. Open the Workspace Members Modal to see a list of current members.

#### Inviting Members to a Workspace

To invite new members to your workspace:

1. In the Workspace Members Modal, click "Invite Member" or a similar option.
2. In the Workspace Invite Modal:
   * Select the user you want to invite from the dropdown or search for them.
   * Choose the appropriate role for the new member.
   * Click "Invite" to send the invitation.

#### Changing Member Roles

To change a member's role within a workspace:

1. In the Workspace Members Modal, find the member whose role you want to change.
2. Use the role dropdown to select a new role for the member.
3. Click the checkmark icon to apply the change.

#### Removing Members from a Workspace

To remove a member from your workspace:

1. In the Workspace Members Modal, locate the member you want to remove.
2. Click the trash icon next to their name.
3. Confirm the removal in the deletion confirmation dialog.

### Workspace Roles

Waterflai supports different roles within a workspace to manage access and permissions:

* Workspace Admin: Full control over the workspace
* Workspace Creator: Can create and manage most resources within the workspace
* Workspace User: Basic access to use features within the workspace

Refer to the "Security and Permissions" documentation for detailed information on the permissions associated with each role.

### Best Practices

1. **Naming Convention**: Use clear, descriptive names for your workspaces to easily identify their purpose or associated projects.
2. **Regular Review**: Periodically review your workspace members and their roles to ensure appropriate access.
3. **Role Assignment**: Assign the least privileged role necessary for each member to maintain security.
4. **Workspace Organization**: Use separate workspaces for different projects or teams to maintain clear boundaries and simplify resource management.

By following these instructions and best practices, you can effectively manage workspaces in Waterflai, ensuring proper organization and security for your projects and teams.


# Security and permissions

## Security and Permissions

This page explains the security model and permission system in Waterflai. Waterflai uses a role-based access control (RBAC) system to manage user permissions at both the global (organization) level and the workspace level.

### User Roles

Waterflai has three main user roles at the global level:

1. **Admin**: Full access to all features and administrative functions
2. **Creator**: Can create and manage workspaces
3. **User**: Basic access to use Waterflai features within assigned workspaces

### Global Permissions

Global permissions apply across the entire Waterflai organization. Here's an overview of the permissions for each global role:

#### Admin

* Full access to all features and permissions

#### Creator

* Create workspaces
* List and enter into assigned workspaces

#### User

* List and enter into assigned workspaces

### Workspace Roles and Permissions

Within each workspace, users can have one of three roles:

1. **Workspace Admin**: Full control over the workspace
2. **Workspace Creator**: Can create and manage most resources within the workspace
3. **Workspace User**: Basic access to use features within the workspace

Here's a detailed breakdown of permissions for each workspace role:

#### Workspace Admin

* Full access to all workspace features and permissions

#### Workspace Creator

* API Keys: Create, List, Delete
* Chatbots: Create, List, View, Edit, Publish, Delete
* Conversations: Create, List, View, Edit, Delete
* Providers: Create, List, View, Edit, Delete
* Inference Analytics: List, View, Delete
* Models: Create, List, View, Edit, Delete
* RAG Collections: Create, List, View, Edit, Delete
* RAG Connector Configs: Create, List, View, Edit, Delete
* Chatflows: Create, List, View, Edit, Execute, Delete
* Workflows: Create, List, View, Edit, Execute, Delete

#### Workspace User

* Chatbots: List, View, Chat
* Conversations: Create, List, View, Edit, Delete
* Inference Analytics: List, View

### Best Practices for Managing Permissions

1. **Least Privilege**: Assign users the minimum role necessary for their tasks to maintain security.
2. **Regular Audits**: Periodically review user roles and permissions to ensure they are still appropriate.
3. **Role Separation**: Use workspace roles to create separation of duties within projects or teams.
4. **Education**: Ensure all users understand their permissions and the responsibilities that come with their role.

### Customizing Permissions

While Waterflai's default roles and permissions cover most use cases, organizations with specific needs can contact Waterflai support to discuss custom permission configurations.

By understanding and properly utilizing this permission system, you can ensure that your Waterflai organization maintains a secure and well-organized environment for all users.


# FAQs


# Support

Welcome to the Waterflai Support page. We're here to help you resolve any issues you may encounter and ensure you have the best possible experience with our platform.

### Getting Help

#### Documentation

Before reaching out for support, we recommend checking our comprehensive documentation. It covers most aspects of using Waterflai and can often provide quick answers to your questions.

* Getting Started Guide
* User Manual
* API Documentation
* FAQs

### Contacting Support

If you couldn't find a solution in our documentation or community resources, our support team is ready to assist you.

Email: support(at)waterflai.ai


# Documentation pages

This page contains a set of documentation examples that can be used to make experimentations on Gravia by using the Gitbook component.


# Pricing chatbot (FR)

Cette page décrit la méthodologie pour établir la tarification du service.

### Facteurs de base

Ces facteurs constituent les éléments fondamentaux pour déterminer le prix de nos services de livraison d'énergie. Ils reflètent la diversité de notre offre et la flexibilité de notre approche pour répondre aux besoins variés de nos clients.

1. Type d'énergie
   * Biodiesel : Une alternative renouvelable au diesel traditionnel
   * Bio-GNV (Gaz Naturel pour Véhicules) : Une option écologique pour les véhicules au gaz
   * Électrique : Pour les véhicules électriques, une énergie propre et silencieuse
   * Hydrogène : L'énergie du futur, zéro émission
2. Type de véhicule
   * Voiture particulière : Pour les flottes de véhicules légers
   * Véhicule Utilitaire Léger (VUL) : Adapté aux besoins des petites et moyennes entreprises
   * Poids Lourd : Pour le transport routier et la logistique
   * Bus : Pour les transports en commun et les flottes de transport de personnes
3. Volume de livraison
   * Petit (< 100 L ou équivalent) : Pour les petites flottes ou les livraisons d'appoint
   * Moyen (100 L - 500 L ou équivalent) : Adapté à la plupart des besoins réguliers
   * Grand (> 500 L ou équivalent) : Pour les grandes flottes ou les besoins importants
4. Fréquence de livraison
   * Ponctuelle : Pour des besoins occasionnels
   * Hebdomadaire : Pour un approvisionnement régulier et fréquent
   * Bi-mensuelle : Un bon compromis entre régularité et flexibilité
   * Mensuelle : Pour une planification à long terme

### Formule de tarification

Cette formule permet de calculer un prix personnalisé en fonction des caractéristiques spécifiques de chaque client et de sa demande.

Prix de base = (Coût de l'énergie + Coût de livraison + Frais de service) \* Remise sur volume \* Remise sur fréquence

#### 1. Coût de l'énergie

Les prix indiqués reflètent les coûts moyens du marché et notre engagement à proposer des tarifs compétitifs.

* Biodiesel : 1,20 €/L
* Bio-GNV : 1,00 €/kg
* Électrique : 0,20 €/kWh
* Hydrogène : 10 €/kg

#### 2. Coût de livraison

Ces coûts varient en fonction de la distance et de la complexité de la livraison dans différentes zones.

* Urbain : 50 €
* Périurbain : 75 €
* Rural : 100 €

#### 3. Frais de service

Ces frais couvrent les coûts opérationnels liés à la gestion de différents types de véhicules.

* Voiture particulière : 20 €
* Véhicule Utilitaire Léger (VUL) : 30 €
* Poids Lourd : 50 €
* Bus : 50 €

#### 4. Remise sur fréquence

Des livraisons régulières permettent une meilleure planification et des économies que nous répercutons sur nos clients. La remise d’applique sur le prix total.

* Ponctuelle : 1,0 (pas de remise)
* Mensuelle : 0,98 (2% de remise)
* Bi-mensuelle : 0,95 (5% de remise)
* Hebdomadaire : 0,92 (8% de remise)

#### 5. Remise sur la taille de la flotte

La remise s’applique sur le prix total.

* 5 à 20 véhicules : 2% de remise supplémentaire
* 21 à 50 véhicules : 5% de remise supplémentaire
* plus de 51 véhicules : 8% de remise supplémentaire

### Résumé des informations nécessaires

* taille de la flotte de véhicule, et type de véhicule
* carburant
* fréquence et zone de livraison

### Exemple de calcul

Cet exemple illustre comment le modèle de tarification s'applique à un cas concret.

Pour une entreprise de logistique de taille moyenne avec 30 VUL nécessitant des livraisons bi-mensuelles de Bio-GNV en zone périurbaine :

1. Coût de l'énergie : 1,00 €/kg \* 200 kg = 200 €
2. Coût de livraison : 75 €
3. Frais de service : 30 € \* 30 véhicules = 900 €
4. Prix de base : (200 € + 75 € + 900 €) = 1 175 €
5. Remise sur fréquence : (1 - 0,05) (Bi-mensuelle)
6. Remise sur la taille de la flotte : (1 - 0,05) (21 - 50 véhicules)

Prix final = 1 175 € \* (1 - 0,05) \* (1 - 0,05) = 1 060,44 € par livraison


# OpenAI Compatible

## OpenAI Compatible Chat Completions (Simple Chatbots)

> Provides a drop-in replacement for the OpenAI Chat Completions API, designed specifically for \*\*Simple Chatbots\*\* built in Waterflai. This endpoint is not intended for executing Chatflows or Workflows.\
> You can use this for both streaming and non-streaming responses.

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"servers":[{"url":"https://api.waterflai.ai","description":"Production Server"}],"security":[{"ApiKeyAuth":[]}],"components":{"securitySchemes":{"ApiKeyAuth":{"type":"apiKey","in":"header","name":"X-API-Key","description":"Your secret API key."}},"schemas":{"ChatCompletionRequest":{"type":"object","required":["model","messages"],"properties":{"model":{"type":"string","description":"The ID of the Simple Chatbot to use for this completion."},"messages":{"type":"array","items":{"$ref":"#/components/schemas/ChatMessage"}},"conversation_id":{"type":"string","description":"A unique identifier for the conversation session.","default":"UID"},"stream":{"type":"boolean","description":"If set, partial message deltas will be sent, like in ChatGPT.","default":false},"temperature":{"type":"number","format":"float","default":0.7},"top_p":{"type":"number","format":"float","default":1},"n":{"type":"integer","default":1},"max_tokens":{"type":"integer","default":4096},"stop":{"oneOf":[{"type":"string"},{"type":"array","items":{"type":"string"}}]},"presence_penalty":{"type":"number","format":"float","default":0},"frequency_penalty":{"type":"number","format":"float","default":0}}},"ChatMessage":{"type":"object","required":["role","content"],"properties":{"role":{"type":"string","enum":["system","user","assistant"],"description":"The role of the message author."},"content":{"type":"string","description":"The content of the message."}}},"ChatCompletionResponse":{"type":"object","properties":{"id":{"type":"string"},"object":{"type":"string"},"created":{"type":"integer","format":"unixtime"},"model":{"type":"string","description":"The model that generated the response (the Chatbot ID)."},"choices":{"type":"array","items":{"$ref":"#/components/schemas/ChatCompletionResponseChoice"}},"usage":{"$ref":"#/components/schemas/UsageInfo"}}},"ChatCompletionResponseChoice":{"type":"object","properties":{"index":{"type":"integer"},"message":{"$ref":"#/components/schemas/ResponseChatMessage"},"finish_reason":{"type":"string","enum":["stop","length","model_length","error","tool_calls",null]}}},"ResponseChatMessage":{"type":"object","properties":{"role":{"type":"string","description":"The role of the author of this message."},"content":{"type":"string","description":"The contents of the message."}}},"UsageInfo":{"type":"object","properties":{"prompt_tokens":{"type":"integer"},"completion_tokens":{"type":"integer"},"total_tokens":{"type":"integer"}}},"ChatCompletionStreamResponse":{"type":"object","description":"Represents a chunk of the streaming response.","properties":{"id":{"type":"string"},"object":{"type":"string"},"created":{"type":"integer","format":"unixtime"},"model":{"type":"string","description":"The model that generated the response (the Chatbot ID)."},"choices":{"type":"array","items":{"$ref":"#/components/schemas/ChatCompletionResponseStreamChoice"}}}},"ChatCompletionResponseStreamChoice":{"type":"object","properties":{"index":{"type":"integer"},"delta":{"$ref":"#/components/schemas/StreamDelta"},"finish_reason":{"type":"string","enum":["stop","length","model_length","error","tool_calls",null],"nullable":true}}},"StreamDelta":{"type":"object","properties":{"role":{"type":"string","enum":["assistant"],"description":"The role of the message author, typically 'assistant'."},"content":{"type":"string","nullable":true,"description":"The content delta of the message."}}},"ErrorResponse":{"type":"object","required":["detail"],"properties":{"detail":{"type":"string","description":"A human-readable description of the error."}}}},"responses":{"UnauthorizedError":{"description":"API key is missing or invalid.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ErrorResponse"}}}},"InternalServerError":{"description":"An unexpected error occurred on the server.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ErrorResponse"}}}}}},"paths":{"/v1/chat/completions":{"post":{"summary":"OpenAI Compatible Chat Completions (Simple Chatbots)","description":"Provides a drop-in replacement for the OpenAI Chat Completions API, designed specifically for **Simple Chatbots** built in Waterflai. This endpoint is not intended for executing Chatflows or Workflows.\nYou can use this for both streaming and non-streaming responses.","tags":["OpenAI Compatible"],"requestBody":{"required":true,"content":{"application/json":{"schema":{"$ref":"#/components/schemas/ChatCompletionRequest"}}}},"responses":{"200":{"description":"Successful response. The format depends on the `stream` parameter in the request.","content":{"application/json":{"schema":{"description":"The full completion response object (when `stream` is `false`).","$ref":"#/components/schemas/ChatCompletionResponse"}},"text/event-stream":{"schema":{"$ref":"#/components/schemas/ChatCompletionStreamResponse","description":"A stream of Server-Sent Events (SSE). Each event is a JSON object corresponding to the `ChatCompletionStreamResponse` schema. The stream is terminated by a `data: [DONE]` message."}}}},"401":{"$ref":"#/components/responses/UnauthorizedError"},"499":{"description":"Client Closed Request. This custom status code indicates an internal inference error occurred. It is used to prevent client-side retries for errors that have already been handled or retried internally.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ErrorResponse"}}}},"500":{"$ref":"#/components/responses/InternalServerError"}}}}}}
```


# Synchronous Execution

## Execute Chatflow (Synchronous)

> Executes the latest published version of a specific Chatflow and waits for the complete result. The response is formatted for immediate use in chat applications.\
> This is a blocking call, best used for quick-running chatflows.

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"servers":[{"url":"https://api.waterflai.ai","description":"Production Server"}],"security":[{"ApiKeyAuth":[]}],"components":{"securitySchemes":{"ApiKeyAuth":{"type":"apiKey","in":"header","name":"X-API-Key","description":"Your secret API key."}},"schemas":{"ExecutionRequest":{"type":"object","properties":{"input_data":{"type":"object","description":"A JSON object containing the input variables for the Chatflow or Workflow. The keys should match the names of the input nodes.","additionalProperties":true}}},"ChatCompletionResponse":{"type":"object","properties":{"id":{"type":"string"},"object":{"type":"string"},"created":{"type":"integer","format":"unixtime"},"model":{"type":"string","description":"The model that generated the response (the Chatbot ID)."},"choices":{"type":"array","items":{"$ref":"#/components/schemas/ChatCompletionResponseChoice"}},"usage":{"$ref":"#/components/schemas/UsageInfo"}}},"ChatCompletionResponseChoice":{"type":"object","properties":{"index":{"type":"integer"},"message":{"$ref":"#/components/schemas/ResponseChatMessage"},"finish_reason":{"type":"string","enum":["stop","length","model_length","error","tool_calls",null]}}},"ResponseChatMessage":{"type":"object","properties":{"role":{"type":"string","description":"The role of the author of this message."},"content":{"type":"string","description":"The contents of the message."}}},"UsageInfo":{"type":"object","properties":{"prompt_tokens":{"type":"integer"},"completion_tokens":{"type":"integer"},"total_tokens":{"type":"integer"}}},"ErrorResponse":{"type":"object","required":["detail"],"properties":{"detail":{"type":"string","description":"A human-readable description of the error."}}}},"responses":{"UnauthorizedError":{"description":"API key is missing or invalid.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ErrorResponse"}}}},"InternalServerError":{"description":"An unexpected error occurred on the server.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ErrorResponse"}}}}}},"paths":{"/execute_chatflow/{chatflow_id}/execute":{"post":{"summary":"Execute Chatflow (Synchronous)","description":"Executes the latest published version of a specific Chatflow and waits for the complete result. The response is formatted for immediate use in chat applications.\nThis is a blocking call, best used for quick-running chatflows.","tags":["Synchronous Execution"],"parameters":[{"name":"chatflow_id","in":"path","required":true,"description":"The unique identifier of the Chatflow to execute.","schema":{"type":"string"}}],"requestBody":{"required":true,"content":{"application/json":{"schema":{"$ref":"#/components/schemas/ExecutionRequest"}}}},"responses":{"200":{"description":"The execution was successful and the final output is returned in an OpenAI-compatible format.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ChatCompletionResponse"}}}},"401":{"$ref":"#/components/responses/UnauthorizedError"},"500":{"$ref":"#/components/responses/InternalServerError"}}}}}}
```

## Execute Chatflow with Streaming (Synchronous)

> Executes the latest published version of a specific Chatflow and streams structured events in real-time using Server-Sent Events (SSE).\
> Each event is a JSON object sent in the format \`data: \<json\_object>\n\n\`. This provides a detailed, live feed of the execution progress, node by node.

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"servers":[{"url":"https://api.waterflai.ai","description":"Production Server"}],"security":[{"ApiKeyAuth":[]}],"components":{"securitySchemes":{"ApiKeyAuth":{"type":"apiKey","in":"header","name":"X-API-Key","description":"Your secret API key."}},"schemas":{"ExecutionRequest":{"type":"object","properties":{"input_data":{"type":"object","description":"A JSON object containing the input variables for the Chatflow or Workflow. The keys should match the names of the input nodes.","additionalProperties":true}}},"StreamEvent":{"oneOf":[{"$ref":"#/components/schemas/StreamEvent_ExecutionStarted"},{"$ref":"#/components/schemas/StreamEvent_NodeStarted"},{"$ref":"#/components/schemas/StreamEvent_NodeCompleted"},{"$ref":"#/components/schemas/StreamEvent_NodeSkipped"},{"$ref":"#/components/schemas/StreamEvent_NodeError"},{"$ref":"#/components/schemas/StreamEvent_ExecutionCompleted"},{"$ref":"#/components/schemas/StreamEvent_ExecutionError"}],"discriminator":{"propertyName":"type"}},"StreamEvent_ExecutionStarted":{"type":"object","properties":{"type":{"type":"string","enum":["execution_started"]},"timestamp":{"type":"string","format":"date-time"}}},"StreamEvent_NodeStarted":{"type":"object","properties":{"type":{"type":"string","enum":["node_started"]},"node_id":{"type":"string"},"node_label":{"type":"string"},"node_type":{"type":"string"},"timestamp":{"type":"string","format":"date-time"}}},"StreamEvent_NodeCompleted":{"type":"object","properties":{"type":{"type":"string","enum":["node_completed"]},"node_id":{"type":"string"},"node_label":{"type":"string"},"node_type":{"type":"string"},"timestamp":{"type":"string","format":"date-time"}}},"StreamEvent_NodeSkipped":{"type":"object","properties":{"type":{"type":"string","enum":["node_skipped"]},"node_id":{"type":"string"},"node_label":{"type":"string"},"node_type":{"type":"string"},"reason":{"type":"string","description":"Reason why the node was skipped (e.g., Condition not met)."},"timestamp":{"type":"string","format":"date-time"}}},"StreamEvent_NodeError":{"type":"object","properties":{"type":{"type":"string","enum":["node_error"]},"node_id":{"type":"string"},"node_label":{"type":"string"},"error":{"type":"string","description":"The error message from the node."},"timestamp":{"type":"string","format":"date-time"}}},"StreamEvent_ExecutionCompleted":{"type":"object","properties":{"type":{"type":"string","enum":["execution_completed"]},"final_output":{"type":"object","additionalProperties":true,"description":"The final computed output of the entire flow."},"workflow_execution":{"$ref":"#/components/schemas/ExecutionResult"},"timestamp":{"type":"string","format":"date-time"}}},"ExecutionResult":{"type":"object","description":"The detailed result from a synchronous execution.","properties":{"final_output":{"type":"object","additionalProperties":true,"description":"A JSON object containing the outputs from the designated output nodes."},"node_executions":{"type":"array","items":{"$ref":"#/components/schemas/NodeExecutionResult"},"nullable":true,"description":"A list of detailed execution results for each node, if requested."},"error_occurred":{"type":"boolean"},"error_message":{"type":"string","nullable":true}}},"NodeExecutionResult":{"type":"object","properties":{"node_id":{"type":"string"},"node_type":{"type":"string"},"execution_detail":{"$ref":"#/components/schemas/NodeExecutionDetail"},"error_occurred":{"type":"boolean"},"error_message":{"type":"string","nullable":true}}},"NodeExecutionDetail":{"type":"object","properties":{"parameters":{"type":"object","additionalProperties":true,"description":"Input parameters for the node."},"execution_info":{"$ref":"#/components/schemas/NodeExecutionInfo"},"outputs":{"type":"object","additionalProperties":true,"description":"Output data from the node."}}},"NodeExecutionInfo":{"type":"object","properties":{"duration":{"type":"number","format":"float","description":"Duration of the node execution in seconds."}}},"StreamEvent_ExecutionError":{"type":"object","properties":{"type":{"type":"string","enum":["execution_error"]},"error":{"type":"string","description":"A fatal error that stopped the execution."},"timestamp":{"type":"string","format":"date-time"}}},"ErrorResponse":{"type":"object","required":["detail"],"properties":{"detail":{"type":"string","description":"A human-readable description of the error."}}}},"responses":{"UnauthorizedError":{"description":"API key is missing or invalid.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ErrorResponse"}}}},"InternalServerError":{"description":"An unexpected error occurred on the server.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ErrorResponse"}}}}}},"paths":{"/execute_chatflow/{chatflow_id}/stream_execute":{"post":{"summary":"Execute Chatflow with Streaming (Synchronous)","description":"Executes the latest published version of a specific Chatflow and streams structured events in real-time using Server-Sent Events (SSE).\nEach event is a JSON object sent in the format `data: <json_object>\\n\\n`. This provides a detailed, live feed of the execution progress, node by node.","tags":["Synchronous Execution"],"parameters":[{"name":"chatflow_id","in":"path","required":true,"description":"The unique identifier of the Chatflow to execute.","schema":{"type":"string"}}],"requestBody":{"required":true,"content":{"application/json":{"schema":{"$ref":"#/components/schemas/ExecutionRequest"}}}},"responses":{"200":{"description":"A stream of structured JSON events representing the real-time execution progress and output.","content":{"text/event-stream":{"schema":{"$ref":"#/components/schemas/StreamEvent"}}}},"401":{"$ref":"#/components/responses/UnauthorizedError"},"500":{"$ref":"#/components/responses/InternalServerError"}}}}}}
```

## Execute Workflow (Synchronous)

> Executes the latest published version of a specific Workflow and waits for the complete, detailed result.\
> This is a blocking call that returns the final output and optionally the execution details of each node.

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"servers":[{"url":"https://api.waterflai.ai","description":"Production Server"}],"security":[{"ApiKeyAuth":[]}],"components":{"securitySchemes":{"ApiKeyAuth":{"type":"apiKey","in":"header","name":"X-API-Key","description":"Your secret API key."}},"schemas":{"ExecutionRequest":{"type":"object","properties":{"input_data":{"type":"object","description":"A JSON object containing the input variables for the Chatflow or Workflow. The keys should match the names of the input nodes.","additionalProperties":true}}},"ExecutionResult":{"type":"object","description":"The detailed result from a synchronous execution.","properties":{"final_output":{"type":"object","additionalProperties":true,"description":"A JSON object containing the outputs from the designated output nodes."},"node_executions":{"type":"array","items":{"$ref":"#/components/schemas/NodeExecutionResult"},"nullable":true,"description":"A list of detailed execution results for each node, if requested."},"error_occurred":{"type":"boolean"},"error_message":{"type":"string","nullable":true}}},"NodeExecutionResult":{"type":"object","properties":{"node_id":{"type":"string"},"node_type":{"type":"string"},"execution_detail":{"$ref":"#/components/schemas/NodeExecutionDetail"},"error_occurred":{"type":"boolean"},"error_message":{"type":"string","nullable":true}}},"NodeExecutionDetail":{"type":"object","properties":{"parameters":{"type":"object","additionalProperties":true,"description":"Input parameters for the node."},"execution_info":{"$ref":"#/components/schemas/NodeExecutionInfo"},"outputs":{"type":"object","additionalProperties":true,"description":"Output data from the node."}}},"NodeExecutionInfo":{"type":"object","properties":{"duration":{"type":"number","format":"float","description":"Duration of the node execution in seconds."}}},"ErrorResponse":{"type":"object","required":["detail"],"properties":{"detail":{"type":"string","description":"A human-readable description of the error."}}}},"responses":{"UnauthorizedError":{"description":"API key is missing or invalid.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ErrorResponse"}}}},"InternalServerError":{"description":"An unexpected error occurred on the server.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ErrorResponse"}}}}}},"paths":{"/execute_workflow/{workflow_id}/execute":{"post":{"summary":"Execute Workflow (Synchronous)","description":"Executes the latest published version of a specific Workflow and waits for the complete, detailed result.\nThis is a blocking call that returns the final output and optionally the execution details of each node.","tags":["Synchronous Execution"],"parameters":[{"name":"workflow_id","in":"path","required":true,"description":"The unique identifier of the Workflow to execute.","schema":{"type":"string"}}],"requestBody":{"required":true,"content":{"application/json":{"schema":{"$ref":"#/components/schemas/ExecutionRequest"}}}},"responses":{"200":{"description":"The execution was successful and the final output is returned as a detailed JSON object.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ExecutionResult"}}}},"401":{"$ref":"#/components/responses/UnauthorizedError"},"500":{"$ref":"#/components/responses/InternalServerError"}}}}}}
```

## Execute Workflow with Streaming (Synchronous)

> Executes the latest published version of a specific Workflow and streams structured events in real-time using Server-Sent Events (SSE).\
> Each event is a JSON object sent in the format \`data: \<json\_object>\n\n\`. This provides a detailed, live feed of the workflow's progress, node by node.

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"servers":[{"url":"https://api.waterflai.ai","description":"Production Server"}],"security":[{"ApiKeyAuth":[]}],"components":{"securitySchemes":{"ApiKeyAuth":{"type":"apiKey","in":"header","name":"X-API-Key","description":"Your secret API key."}},"schemas":{"ExecutionRequest":{"type":"object","properties":{"input_data":{"type":"object","description":"A JSON object containing the input variables for the Chatflow or Workflow. The keys should match the names of the input nodes.","additionalProperties":true}}},"StreamEvent":{"oneOf":[{"$ref":"#/components/schemas/StreamEvent_ExecutionStarted"},{"$ref":"#/components/schemas/StreamEvent_NodeStarted"},{"$ref":"#/components/schemas/StreamEvent_NodeCompleted"},{"$ref":"#/components/schemas/StreamEvent_NodeSkipped"},{"$ref":"#/components/schemas/StreamEvent_NodeError"},{"$ref":"#/components/schemas/StreamEvent_ExecutionCompleted"},{"$ref":"#/components/schemas/StreamEvent_ExecutionError"}],"discriminator":{"propertyName":"type"}},"StreamEvent_ExecutionStarted":{"type":"object","properties":{"type":{"type":"string","enum":["execution_started"]},"timestamp":{"type":"string","format":"date-time"}}},"StreamEvent_NodeStarted":{"type":"object","properties":{"type":{"type":"string","enum":["node_started"]},"node_id":{"type":"string"},"node_label":{"type":"string"},"node_type":{"type":"string"},"timestamp":{"type":"string","format":"date-time"}}},"StreamEvent_NodeCompleted":{"type":"object","properties":{"type":{"type":"string","enum":["node_completed"]},"node_id":{"type":"string"},"node_label":{"type":"string"},"node_type":{"type":"string"},"timestamp":{"type":"string","format":"date-time"}}},"StreamEvent_NodeSkipped":{"type":"object","properties":{"type":{"type":"string","enum":["node_skipped"]},"node_id":{"type":"string"},"node_label":{"type":"string"},"node_type":{"type":"string"},"reason":{"type":"string","description":"Reason why the node was skipped (e.g., Condition not met)."},"timestamp":{"type":"string","format":"date-time"}}},"StreamEvent_NodeError":{"type":"object","properties":{"type":{"type":"string","enum":["node_error"]},"node_id":{"type":"string"},"node_label":{"type":"string"},"error":{"type":"string","description":"The error message from the node."},"timestamp":{"type":"string","format":"date-time"}}},"StreamEvent_ExecutionCompleted":{"type":"object","properties":{"type":{"type":"string","enum":["execution_completed"]},"final_output":{"type":"object","additionalProperties":true,"description":"The final computed output of the entire flow."},"workflow_execution":{"$ref":"#/components/schemas/ExecutionResult"},"timestamp":{"type":"string","format":"date-time"}}},"ExecutionResult":{"type":"object","description":"The detailed result from a synchronous execution.","properties":{"final_output":{"type":"object","additionalProperties":true,"description":"A JSON object containing the outputs from the designated output nodes."},"node_executions":{"type":"array","items":{"$ref":"#/components/schemas/NodeExecutionResult"},"nullable":true,"description":"A list of detailed execution results for each node, if requested."},"error_occurred":{"type":"boolean"},"error_message":{"type":"string","nullable":true}}},"NodeExecutionResult":{"type":"object","properties":{"node_id":{"type":"string"},"node_type":{"type":"string"},"execution_detail":{"$ref":"#/components/schemas/NodeExecutionDetail"},"error_occurred":{"type":"boolean"},"error_message":{"type":"string","nullable":true}}},"NodeExecutionDetail":{"type":"object","properties":{"parameters":{"type":"object","additionalProperties":true,"description":"Input parameters for the node."},"execution_info":{"$ref":"#/components/schemas/NodeExecutionInfo"},"outputs":{"type":"object","additionalProperties":true,"description":"Output data from the node."}}},"NodeExecutionInfo":{"type":"object","properties":{"duration":{"type":"number","format":"float","description":"Duration of the node execution in seconds."}}},"StreamEvent_ExecutionError":{"type":"object","properties":{"type":{"type":"string","enum":["execution_error"]},"error":{"type":"string","description":"A fatal error that stopped the execution."},"timestamp":{"type":"string","format":"date-time"}}},"ErrorResponse":{"type":"object","required":["detail"],"properties":{"detail":{"type":"string","description":"A human-readable description of the error."}}}},"responses":{"UnauthorizedError":{"description":"API key is missing or invalid.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ErrorResponse"}}}},"InternalServerError":{"description":"An unexpected error occurred on the server.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ErrorResponse"}}}}}},"paths":{"/execute_workflow/{chatflow_id}/stream_execute":{"post":{"summary":"Execute Workflow with Streaming (Synchronous)","description":"Executes the latest published version of a specific Workflow and streams structured events in real-time using Server-Sent Events (SSE).\nEach event is a JSON object sent in the format `data: <json_object>\\n\\n`. This provides a detailed, live feed of the workflow's progress, node by node.","tags":["Synchronous Execution"],"parameters":[{"name":"chatflow_id","in":"path","required":true,"description":"The unique identifier of the Workflow to execute.","schema":{"type":"string"}}],"requestBody":{"required":true,"content":{"application/json":{"schema":{"$ref":"#/components/schemas/ExecutionRequest"}}}},"responses":{"200":{"description":"A stream of structured JSON events representing the real-time execution progress and output.","content":{"text/event-stream":{"schema":{"$ref":"#/components/schemas/StreamEvent"}}}},"401":{"$ref":"#/components/responses/UnauthorizedError"},"500":{"$ref":"#/components/responses/InternalServerError"}}}}}}
```


# Asynchronous Execution

## Start Asynchronous Execution

> Starts an asynchronous execution of a published Chatbot (Chatflow or Workflow). This is ideal for long-running tasks.\
> The API queues the job and immediately returns an \`execution\_id\` and tracking URLs, allowing you to check the status later without keeping the connection open.

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"servers":[{"url":"https://api.waterflai.ai","description":"Production Server"}],"security":[{"ApiKeyAuth":[]}],"components":{"securitySchemes":{"ApiKeyAuth":{"type":"apiKey","in":"header","name":"X-API-Key","description":"Your secret API key."}},"schemas":{"ExecutionRequest":{"type":"object","properties":{"input_data":{"type":"object","description":"A JSON object containing the input variables for the Chatflow or Workflow. The keys should match the names of the input nodes.","additionalProperties":true}}},"AsyncExecutionStartResponse":{"type":"object","properties":{"execution_id":{"type":"string","description":"The unique identifier for this execution job."},"status_url":{"type":"string","format":"uri","description":"The URL to poll for the execution status."},"stream_url":{"type":"string","format":"uri","description":"The URL to stream real-time progress."},"cancel_url":{"type":"string","format":"uri","description":"The URL to cancel the execution."}}},"ErrorResponse":{"type":"object","required":["detail"],"properties":{"detail":{"type":"string","description":"A human-readable description of the error."}}}},"responses":{"UnauthorizedError":{"description":"API key is missing or invalid.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ErrorResponse"}}}},"NotFoundError":{"description":"The requested resource was not found.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ErrorResponse"}}}},"InternalServerError":{"description":"An unexpected error occurred on the server.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ErrorResponse"}}}}}},"paths":{"/v1/executions/{chatbot_id}/async":{"post":{"summary":"Start Asynchronous Execution","description":"Starts an asynchronous execution of a published Chatbot (Chatflow or Workflow). This is ideal for long-running tasks.\nThe API queues the job and immediately returns an `execution_id` and tracking URLs, allowing you to check the status later without keeping the connection open.","tags":["Asynchronous Execution"],"parameters":[{"name":"chatbot_id","in":"path","required":true,"description":"The unique identifier of the Chatbot to execute.","schema":{"type":"string"}}],"requestBody":{"required":true,"content":{"application/json":{"schema":{"$ref":"#/components/schemas/ExecutionRequest"}}}},"responses":{"202":{"description":"The execution has been accepted for processing. The response body contains details to track the job.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/AsyncExecutionStartResponse"}}}},"401":{"$ref":"#/components/responses/UnauthorizedError"},"404":{"$ref":"#/components/responses/NotFoundError"},"500":{"$ref":"#/components/responses/InternalServerError"}}}}}}
```

## Get Execution Status

> Retrieves the current status and result of a specific asynchronous execution.\
> You should poll this endpoint to check the job's progress. Once the \`status\` is \`COMPLETED\`, the \`final\_output\` field will contain the result.

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"servers":[{"url":"https://api.waterflai.ai","description":"Production Server"}],"security":[{"ApiKeyAuth":[]}],"components":{"securitySchemes":{"ApiKeyAuth":{"type":"apiKey","in":"header","name":"X-API-Key","description":"Your secret API key."}},"schemas":{"ExecutionJobResponse":{"type":"object","properties":{"execution_id":{"type":"string"},"status":{"type":"string","enum":["PENDING","RUNNING","COMPLETED","FAILED","CANCELLED"]},"progress":{"type":"number","format":"float","description":"A value from 0.0 to 100.0 indicating the completion percentage."},"current_node":{"type":"string","nullable":true,"description":"The ID of the node currently being executed."},"completed_nodes":{"type":"integer"},"total_nodes":{"type":"integer"},"final_output":{"type":"object","nullable":true,"additionalProperties":true,"description":"The final result of the execution, available when status is `COMPLETED`."},"error_message":{"type":"string","nullable":true,"description":"Details about the error, available when status is `FAILED`."},"created_at":{"type":"string","format":"date-time"},"started_at":{"type":"string","format":"date-time","nullable":true},"completed_at":{"type":"string","format":"date-time","nullable":true},"retry_count":{"type":"integer"},"execution_source":{"type":"string","enum":["CHATBOT","STUDIO","API"]},"is_temporary":{"type":"boolean"},"cleanup_after":{"type":"string","format":"date-time","nullable":true}}},"ErrorResponse":{"type":"object","required":["detail"],"properties":{"detail":{"type":"string","description":"A human-readable description of the error."}}}},"responses":{"UnauthorizedError":{"description":"API key is missing or invalid.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ErrorResponse"}}}},"NotFoundError":{"description":"The requested resource was not found.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ErrorResponse"}}}},"InternalServerError":{"description":"An unexpected error occurred on the server.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ErrorResponse"}}}}}},"paths":{"/v1/executions/{execution_id}":{"get":{"summary":"Get Execution Status","description":"Retrieves the current status and result of a specific asynchronous execution.\nYou should poll this endpoint to check the job's progress. Once the `status` is `COMPLETED`, the `final_output` field will contain the result.","tags":["Asynchronous Execution"],"parameters":[{"name":"execution_id","in":"path","required":true,"description":"The unique identifier of the execution job.","schema":{"type":"string"}}],"responses":{"200":{"description":"The current state of the execution job.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ExecutionJobResponse"}}}},"401":{"$ref":"#/components/responses/UnauthorizedError"},"404":{"$ref":"#/components/responses/NotFoundError"},"500":{"$ref":"#/components/responses/InternalServerError"}}}}}}
```

## Cancel Asynchronous Execution

> Cancels a \`PENDING\` or \`RUNNING\` execution.\
> Completed, failed, or already cancelled jobs cannot be cancelled again.

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"servers":[{"url":"https://api.waterflai.ai","description":"Production Server"}],"security":[{"ApiKeyAuth":[]}],"components":{"securitySchemes":{"ApiKeyAuth":{"type":"apiKey","in":"header","name":"X-API-Key","description":"Your secret API key."}},"schemas":{"ExecutionCancelResponse":{"type":"object","properties":{"execution_id":{"type":"string"},"cancelled":{"type":"boolean","description":"True if the cancellation was successful."},"message":{"type":"string","description":"A confirmation message."},"previous_status":{"type":"string","enum":["PENDING","RUNNING","COMPLETED","FAILED","CANCELLED"],"description":"The status of the job before cancellation was attempted."}}},"ErrorResponse":{"type":"object","required":["detail"],"properties":{"detail":{"type":"string","description":"A human-readable description of the error."}}}},"responses":{"UnauthorizedError":{"description":"API key is missing or invalid.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ErrorResponse"}}}},"NotFoundError":{"description":"The requested resource was not found.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ErrorResponse"}}}},"InternalServerError":{"description":"An unexpected error occurred on the server.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ErrorResponse"}}}}}},"paths":{"/v1/executions/{execution_id}":{"delete":{"summary":"Cancel Asynchronous Execution","description":"Cancels a `PENDING` or `RUNNING` execution.\nCompleted, failed, or already cancelled jobs cannot be cancelled again.","tags":["Asynchronous Execution"],"parameters":[{"name":"execution_id","in":"path","required":true,"description":"The unique identifier of the execution job to cancel.","schema":{"type":"string"}}],"responses":{"200":{"description":"The cancellation request was successfully processed.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ExecutionCancelResponse"}}}},"401":{"$ref":"#/components/responses/UnauthorizedError"},"404":{"$ref":"#/components/responses/NotFoundError"},"500":{"$ref":"#/components/responses/InternalServerError"}}}}}}
```

## Stream Asynchronous Execution Progress

> Streams the real-time progress of a specific asynchronous execution via Server-Sent Events (SSE).\
> This provides a live feed of events like \`node\_started\`, \`node\_completed\`, and \`execution\_completed\`. The stream closes automatically when the job finishes.

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"servers":[{"url":"https://api.waterflai.ai","description":"Production Server"}],"security":[{"ApiKeyAuth":[]}],"components":{"securitySchemes":{"ApiKeyAuth":{"type":"apiKey","in":"header","name":"X-API-Key","description":"Your secret API key."}},"responses":{"UnauthorizedError":{"description":"API key is missing or invalid.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ErrorResponse"}}}},"NotFoundError":{"description":"The requested resource was not found.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ErrorResponse"}}}},"InternalServerError":{"description":"An unexpected error occurred on the server.","content":{"application/json":{"schema":{"$ref":"#/components/schemas/ErrorResponse"}}}}},"schemas":{"ErrorResponse":{"type":"object","required":["detail"],"properties":{"detail":{"type":"string","description":"A human-readable description of the error."}}}}},"paths":{"/v1/executions/{execution_id}/stream":{"get":{"summary":"Stream Asynchronous Execution Progress","description":"Streams the real-time progress of a specific asynchronous execution via Server-Sent Events (SSE).\nThis provides a live feed of events like `node_started`, `node_completed`, and `execution_completed`. The stream closes automatically when the job finishes.","tags":["Asynchronous Execution"],"parameters":[{"name":"execution_id","in":"path","required":true,"description":"The unique identifier of the execution job.","schema":{"type":"string"}}],"responses":{"200":{"description":"A stream of events representing the real-time execution progress.","content":{"text/event-stream":{"schema":{"type":"string"}}}},"401":{"$ref":"#/components/responses/UnauthorizedError"},"404":{"$ref":"#/components/responses/NotFoundError"},"500":{"$ref":"#/components/responses/InternalServerError"}}}}}}
```


# Models

## The ExecutionRequest object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"ExecutionRequest":{"type":"object","properties":{"input_data":{"type":"object","description":"A JSON object containing the input variables for the Chatflow or Workflow. The keys should match the names of the input nodes.","additionalProperties":true}}}}}}
```

## The ChatCompletionRequest object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"ChatCompletionRequest":{"type":"object","required":["model","messages"],"properties":{"model":{"type":"string","description":"The ID of the Simple Chatbot to use for this completion."},"messages":{"type":"array","items":{"$ref":"#/components/schemas/ChatMessage"}},"conversation_id":{"type":"string","description":"A unique identifier for the conversation session.","default":"UID"},"stream":{"type":"boolean","description":"If set, partial message deltas will be sent, like in ChatGPT.","default":false},"temperature":{"type":"number","format":"float","default":0.7},"top_p":{"type":"number","format":"float","default":1},"n":{"type":"integer","default":1},"max_tokens":{"type":"integer","default":4096},"stop":{"oneOf":[{"type":"string"},{"type":"array","items":{"type":"string"}}]},"presence_penalty":{"type":"number","format":"float","default":0},"frequency_penalty":{"type":"number","format":"float","default":0}}},"ChatMessage":{"type":"object","required":["role","content"],"properties":{"role":{"type":"string","enum":["system","user","assistant"],"description":"The role of the message author."},"content":{"type":"string","description":"The content of the message."}}}}}}
```

## The StreamDelta object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"StreamDelta":{"type":"object","properties":{"role":{"type":"string","enum":["assistant"],"description":"The role of the message author, typically 'assistant'."},"content":{"type":"string","nullable":true,"description":"The content delta of the message."}}}}}}
```

## The ChatCompletionResponseStreamChoice object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"ChatCompletionResponseStreamChoice":{"type":"object","properties":{"index":{"type":"integer"},"delta":{"$ref":"#/components/schemas/StreamDelta"},"finish_reason":{"type":"string","enum":["stop","length","model_length","error","tool_calls",null],"nullable":true}}},"StreamDelta":{"type":"object","properties":{"role":{"type":"string","enum":["assistant"],"description":"The role of the message author, typically 'assistant'."},"content":{"type":"string","nullable":true,"description":"The content delta of the message."}}}}}}
```

## The ChatCompletionStreamResponse object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"ChatCompletionStreamResponse":{"type":"object","description":"Represents a chunk of the streaming response.","properties":{"id":{"type":"string"},"object":{"type":"string"},"created":{"type":"integer","format":"unixtime"},"model":{"type":"string","description":"The model that generated the response (the Chatbot ID)."},"choices":{"type":"array","items":{"$ref":"#/components/schemas/ChatCompletionResponseStreamChoice"}}}},"ChatCompletionResponseStreamChoice":{"type":"object","properties":{"index":{"type":"integer"},"delta":{"$ref":"#/components/schemas/StreamDelta"},"finish_reason":{"type":"string","enum":["stop","length","model_length","error","tool_calls",null],"nullable":true}}},"StreamDelta":{"type":"object","properties":{"role":{"type":"string","enum":["assistant"],"description":"The role of the message author, typically 'assistant'."},"content":{"type":"string","nullable":true,"description":"The content delta of the message."}}}}}}
```

## The ChatMessage object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"ChatMessage":{"type":"object","required":["role","content"],"properties":{"role":{"type":"string","enum":["system","user","assistant"],"description":"The role of the message author."},"content":{"type":"string","description":"The content of the message."}}}}}}
```

## The UsageInfo object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"UsageInfo":{"type":"object","properties":{"prompt_tokens":{"type":"integer"},"completion_tokens":{"type":"integer"},"total_tokens":{"type":"integer"}}}}}}
```

## The ResponseChatMessage object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"ResponseChatMessage":{"type":"object","properties":{"role":{"type":"string","description":"The role of the author of this message."},"content":{"type":"string","description":"The contents of the message."}}}}}}
```

## The NodeExecutionInfo object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"NodeExecutionInfo":{"type":"object","properties":{"duration":{"type":"number","format":"float","description":"Duration of the node execution in seconds."}}}}}}
```

## The NodeExecutionDetail object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"NodeExecutionDetail":{"type":"object","properties":{"parameters":{"type":"object","additionalProperties":true,"description":"Input parameters for the node."},"execution_info":{"$ref":"#/components/schemas/NodeExecutionInfo"},"outputs":{"type":"object","additionalProperties":true,"description":"Output data from the node."}}},"NodeExecutionInfo":{"type":"object","properties":{"duration":{"type":"number","format":"float","description":"Duration of the node execution in seconds."}}}}}}
```

## The NodeExecutionResult object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"NodeExecutionResult":{"type":"object","properties":{"node_id":{"type":"string"},"node_type":{"type":"string"},"execution_detail":{"$ref":"#/components/schemas/NodeExecutionDetail"},"error_occurred":{"type":"boolean"},"error_message":{"type":"string","nullable":true}}},"NodeExecutionDetail":{"type":"object","properties":{"parameters":{"type":"object","additionalProperties":true,"description":"Input parameters for the node."},"execution_info":{"$ref":"#/components/schemas/NodeExecutionInfo"},"outputs":{"type":"object","additionalProperties":true,"description":"Output data from the node."}}},"NodeExecutionInfo":{"type":"object","properties":{"duration":{"type":"number","format":"float","description":"Duration of the node execution in seconds."}}}}}}
```

## The ExecutionResult object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"ExecutionResult":{"type":"object","description":"The detailed result from a synchronous execution.","properties":{"final_output":{"type":"object","additionalProperties":true,"description":"A JSON object containing the outputs from the designated output nodes."},"node_executions":{"type":"array","items":{"$ref":"#/components/schemas/NodeExecutionResult"},"nullable":true,"description":"A list of detailed execution results for each node, if requested."},"error_occurred":{"type":"boolean"},"error_message":{"type":"string","nullable":true}}},"NodeExecutionResult":{"type":"object","properties":{"node_id":{"type":"string"},"node_type":{"type":"string"},"execution_detail":{"$ref":"#/components/schemas/NodeExecutionDetail"},"error_occurred":{"type":"boolean"},"error_message":{"type":"string","nullable":true}}},"NodeExecutionDetail":{"type":"object","properties":{"parameters":{"type":"object","additionalProperties":true,"description":"Input parameters for the node."},"execution_info":{"$ref":"#/components/schemas/NodeExecutionInfo"},"outputs":{"type":"object","additionalProperties":true,"description":"Output data from the node."}}},"NodeExecutionInfo":{"type":"object","properties":{"duration":{"type":"number","format":"float","description":"Duration of the node execution in seconds."}}}}}}
```

## The ChatCompletionResponseChoice object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"ChatCompletionResponseChoice":{"type":"object","properties":{"index":{"type":"integer"},"message":{"$ref":"#/components/schemas/ResponseChatMessage"},"finish_reason":{"type":"string","enum":["stop","length","model_length","error","tool_calls",null]}}},"ResponseChatMessage":{"type":"object","properties":{"role":{"type":"string","description":"The role of the author of this message."},"content":{"type":"string","description":"The contents of the message."}}}}}}
```

## The ChatCompletionResponse object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"ChatCompletionResponse":{"type":"object","properties":{"id":{"type":"string"},"object":{"type":"string"},"created":{"type":"integer","format":"unixtime"},"model":{"type":"string","description":"The model that generated the response (the Chatbot ID)."},"choices":{"type":"array","items":{"$ref":"#/components/schemas/ChatCompletionResponseChoice"}},"usage":{"$ref":"#/components/schemas/UsageInfo"}}},"ChatCompletionResponseChoice":{"type":"object","properties":{"index":{"type":"integer"},"message":{"$ref":"#/components/schemas/ResponseChatMessage"},"finish_reason":{"type":"string","enum":["stop","length","model_length","error","tool_calls",null]}}},"ResponseChatMessage":{"type":"object","properties":{"role":{"type":"string","description":"The role of the author of this message."},"content":{"type":"string","description":"The contents of the message."}}},"UsageInfo":{"type":"object","properties":{"prompt_tokens":{"type":"integer"},"completion_tokens":{"type":"integer"},"total_tokens":{"type":"integer"}}}}}}
```

## The AsyncExecutionStartResponse object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"AsyncExecutionStartResponse":{"type":"object","properties":{"execution_id":{"type":"string","description":"The unique identifier for this execution job."},"status_url":{"type":"string","format":"uri","description":"The URL to poll for the execution status."},"stream_url":{"type":"string","format":"uri","description":"The URL to stream real-time progress."},"cancel_url":{"type":"string","format":"uri","description":"The URL to cancel the execution."}}}}}}
```

## The ExecutionJobResponse object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"ExecutionJobResponse":{"type":"object","properties":{"execution_id":{"type":"string"},"status":{"type":"string","enum":["PENDING","RUNNING","COMPLETED","FAILED","CANCELLED"]},"progress":{"type":"number","format":"float","description":"A value from 0.0 to 100.0 indicating the completion percentage."},"current_node":{"type":"string","nullable":true,"description":"The ID of the node currently being executed."},"completed_nodes":{"type":"integer"},"total_nodes":{"type":"integer"},"final_output":{"type":"object","nullable":true,"additionalProperties":true,"description":"The final result of the execution, available when status is `COMPLETED`."},"error_message":{"type":"string","nullable":true,"description":"Details about the error, available when status is `FAILED`."},"created_at":{"type":"string","format":"date-time"},"started_at":{"type":"string","format":"date-time","nullable":true},"completed_at":{"type":"string","format":"date-time","nullable":true},"retry_count":{"type":"integer"},"execution_source":{"type":"string","enum":["CHATBOT","STUDIO","API"]},"is_temporary":{"type":"boolean"},"cleanup_after":{"type":"string","format":"date-time","nullable":true}}}}}}
```

## The ExecutionCancelResponse object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"ExecutionCancelResponse":{"type":"object","properties":{"execution_id":{"type":"string"},"cancelled":{"type":"boolean","description":"True if the cancellation was successful."},"message":{"type":"string","description":"A confirmation message."},"previous_status":{"type":"string","enum":["PENDING","RUNNING","COMPLETED","FAILED","CANCELLED"],"description":"The status of the job before cancellation was attempted."}}}}}}
```

## The ErrorResponse object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"ErrorResponse":{"type":"object","required":["detail"],"properties":{"detail":{"type":"string","description":"A human-readable description of the error."}}}}}}
```

## The StreamEvent\_ExecutionStarted object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"StreamEvent_ExecutionStarted":{"type":"object","properties":{"type":{"type":"string","enum":["execution_started"]},"timestamp":{"type":"string","format":"date-time"}}}}}}
```

## The StreamEvent\_NodeStarted object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"StreamEvent_NodeStarted":{"type":"object","properties":{"type":{"type":"string","enum":["node_started"]},"node_id":{"type":"string"},"node_label":{"type":"string"},"node_type":{"type":"string"},"timestamp":{"type":"string","format":"date-time"}}}}}}
```

## The StreamEvent\_NodeCompleted object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"StreamEvent_NodeCompleted":{"type":"object","properties":{"type":{"type":"string","enum":["node_completed"]},"node_id":{"type":"string"},"node_label":{"type":"string"},"node_type":{"type":"string"},"timestamp":{"type":"string","format":"date-time"}}}}}}
```

## The StreamEvent\_NodeSkipped object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"StreamEvent_NodeSkipped":{"type":"object","properties":{"type":{"type":"string","enum":["node_skipped"]},"node_id":{"type":"string"},"node_label":{"type":"string"},"node_type":{"type":"string"},"reason":{"type":"string","description":"Reason why the node was skipped (e.g., Condition not met)."},"timestamp":{"type":"string","format":"date-time"}}}}}}
```

## The StreamEvent\_NodeError object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"StreamEvent_NodeError":{"type":"object","properties":{"type":{"type":"string","enum":["node_error"]},"node_id":{"type":"string"},"node_label":{"type":"string"},"error":{"type":"string","description":"The error message from the node."},"timestamp":{"type":"string","format":"date-time"}}}}}}
```

## The StreamEvent\_ExecutionCompleted object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"StreamEvent_ExecutionCompleted":{"type":"object","properties":{"type":{"type":"string","enum":["execution_completed"]},"final_output":{"type":"object","additionalProperties":true,"description":"The final computed output of the entire flow."},"workflow_execution":{"$ref":"#/components/schemas/ExecutionResult"},"timestamp":{"type":"string","format":"date-time"}}},"ExecutionResult":{"type":"object","description":"The detailed result from a synchronous execution.","properties":{"final_output":{"type":"object","additionalProperties":true,"description":"A JSON object containing the outputs from the designated output nodes."},"node_executions":{"type":"array","items":{"$ref":"#/components/schemas/NodeExecutionResult"},"nullable":true,"description":"A list of detailed execution results for each node, if requested."},"error_occurred":{"type":"boolean"},"error_message":{"type":"string","nullable":true}}},"NodeExecutionResult":{"type":"object","properties":{"node_id":{"type":"string"},"node_type":{"type":"string"},"execution_detail":{"$ref":"#/components/schemas/NodeExecutionDetail"},"error_occurred":{"type":"boolean"},"error_message":{"type":"string","nullable":true}}},"NodeExecutionDetail":{"type":"object","properties":{"parameters":{"type":"object","additionalProperties":true,"description":"Input parameters for the node."},"execution_info":{"$ref":"#/components/schemas/NodeExecutionInfo"},"outputs":{"type":"object","additionalProperties":true,"description":"Output data from the node."}}},"NodeExecutionInfo":{"type":"object","properties":{"duration":{"type":"number","format":"float","description":"Duration of the node execution in seconds."}}}}}}
```

## The StreamEvent\_ExecutionError object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"StreamEvent_ExecutionError":{"type":"object","properties":{"type":{"type":"string","enum":["execution_error"]},"error":{"type":"string","description":"A fatal error that stopped the execution."},"timestamp":{"type":"string","format":"date-time"}}}}}}
```

## The StreamEvent object

```json
{"openapi":"3.0.3","info":{"title":"Waterflai Public API","version":"v1"},"components":{"schemas":{"StreamEvent":{"oneOf":[{"$ref":"#/components/schemas/StreamEvent_ExecutionStarted"},{"$ref":"#/components/schemas/StreamEvent_NodeStarted"},{"$ref":"#/components/schemas/StreamEvent_NodeCompleted"},{"$ref":"#/components/schemas/StreamEvent_NodeSkipped"},{"$ref":"#/components/schemas/StreamEvent_NodeError"},{"$ref":"#/components/schemas/StreamEvent_ExecutionCompleted"},{"$ref":"#/components/schemas/StreamEvent_ExecutionError"}],"discriminator":{"propertyName":"type"}},"StreamEvent_ExecutionStarted":{"type":"object","properties":{"type":{"type":"string","enum":["execution_started"]},"timestamp":{"type":"string","format":"date-time"}}},"StreamEvent_NodeStarted":{"type":"object","properties":{"type":{"type":"string","enum":["node_started"]},"node_id":{"type":"string"},"node_label":{"type":"string"},"node_type":{"type":"string"},"timestamp":{"type":"string","format":"date-time"}}},"StreamEvent_NodeCompleted":{"type":"object","properties":{"type":{"type":"string","enum":["node_completed"]},"node_id":{"type":"string"},"node_label":{"type":"string"},"node_type":{"type":"string"},"timestamp":{"type":"string","format":"date-time"}}},"StreamEvent_NodeSkipped":{"type":"object","properties":{"type":{"type":"string","enum":["node_skipped"]},"node_id":{"type":"string"},"node_label":{"type":"string"},"node_type":{"type":"string"},"reason":{"type":"string","description":"Reason why the node was skipped (e.g., Condition not met)."},"timestamp":{"type":"string","format":"date-time"}}},"StreamEvent_NodeError":{"type":"object","properties":{"type":{"type":"string","enum":["node_error"]},"node_id":{"type":"string"},"node_label":{"type":"string"},"error":{"type":"string","description":"The error message from the node."},"timestamp":{"type":"string","format":"date-time"}}},"StreamEvent_ExecutionCompleted":{"type":"object","properties":{"type":{"type":"string","enum":["execution_completed"]},"final_output":{"type":"object","additionalProperties":true,"description":"The final computed output of the entire flow."},"workflow_execution":{"$ref":"#/components/schemas/ExecutionResult"},"timestamp":{"type":"string","format":"date-time"}}},"ExecutionResult":{"type":"object","description":"The detailed result from a synchronous execution.","properties":{"final_output":{"type":"object","additionalProperties":true,"description":"A JSON object containing the outputs from the designated output nodes."},"node_executions":{"type":"array","items":{"$ref":"#/components/schemas/NodeExecutionResult"},"nullable":true,"description":"A list of detailed execution results for each node, if requested."},"error_occurred":{"type":"boolean"},"error_message":{"type":"string","nullable":true}}},"NodeExecutionResult":{"type":"object","properties":{"node_id":{"type":"string"},"node_type":{"type":"string"},"execution_detail":{"$ref":"#/components/schemas/NodeExecutionDetail"},"error_occurred":{"type":"boolean"},"error_message":{"type":"string","nullable":true}}},"NodeExecutionDetail":{"type":"object","properties":{"parameters":{"type":"object","additionalProperties":true,"description":"Input parameters for the node."},"execution_info":{"$ref":"#/components/schemas/NodeExecutionInfo"},"outputs":{"type":"object","additionalProperties":true,"description":"Output data from the node."}}},"NodeExecutionInfo":{"type":"object","properties":{"duration":{"type":"number","format":"float","description":"Duration of the node execution in seconds."}}},"StreamEvent_ExecutionError":{"type":"object","properties":{"type":{"type":"string","enum":["execution_error"]},"error":{"type":"string","description":"A fatal error that stopped the execution."},"timestamp":{"type":"string","format":"date-time"}}}}}}
```